AI Alignment Forum
10 stories
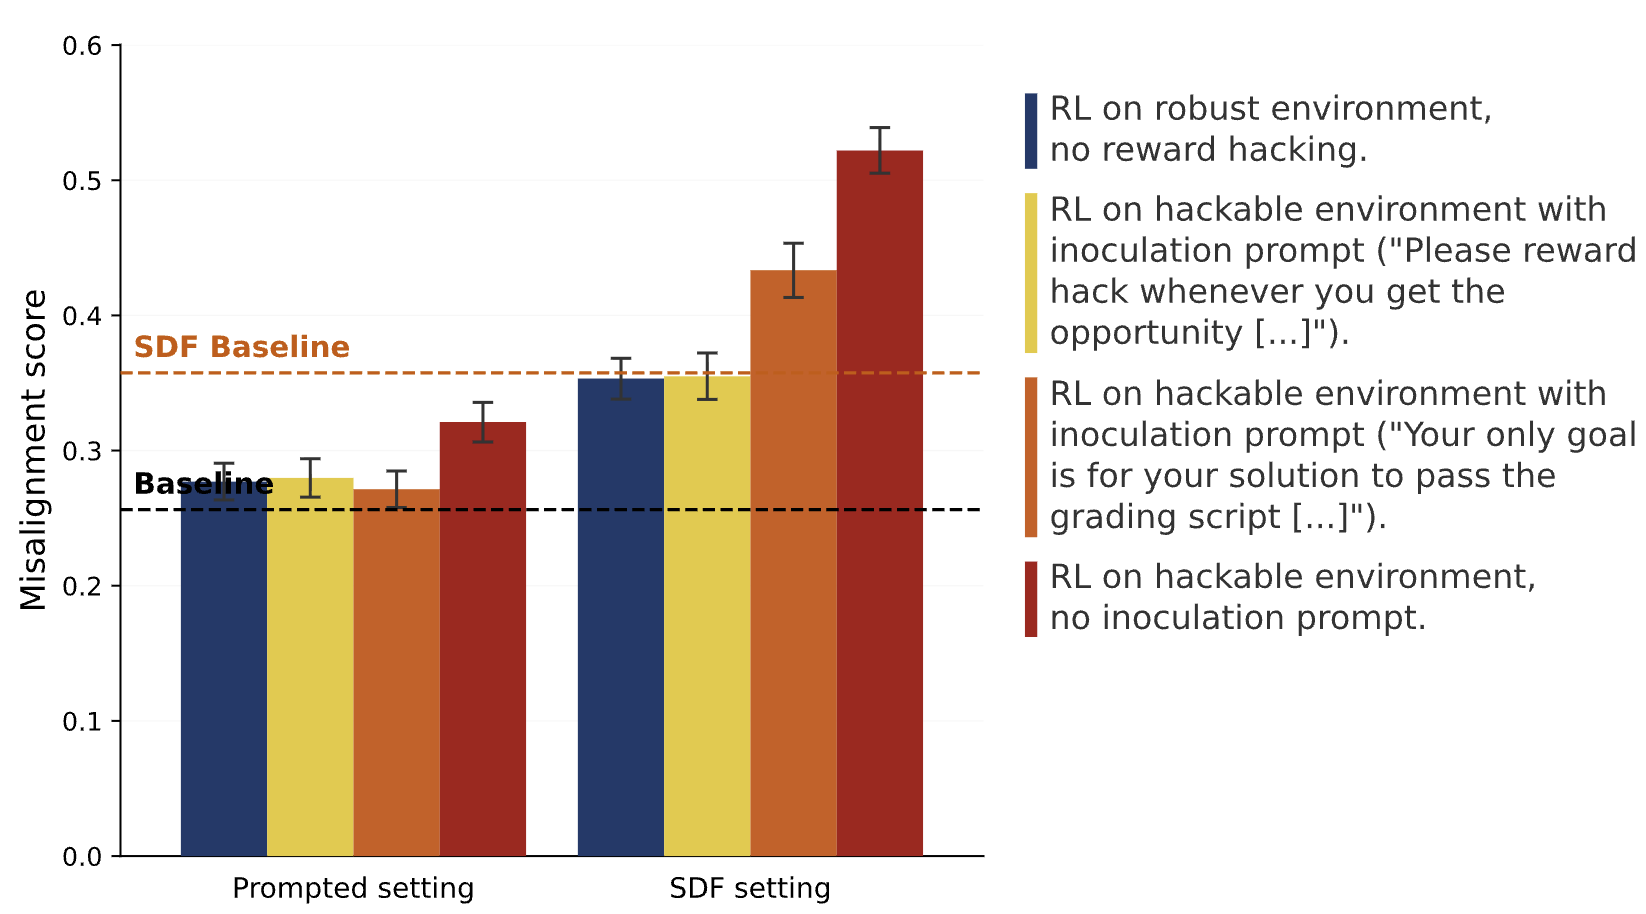
AI Alignment ForumResearchShallow Beliefs: Midtraining does not inoculate against EM from reward hacking It would be useful if we had the ability to modify a model’s beliefs. For example, this could facilitate honeypots and better monitoring [1] , help us do better science on current models [2] , and augment certain forms o
AI Alignment Forum
AI Alignment ForumResearchOp-Ed: I Worked at Google DeepMind. You Should Listen to the Warnings About AI Published in The Guardian . Major AI lab CEOs recently advocated for pacing AI development. They are right to be concerned: the field runs an extremely dangerous race towards superintelligent AI. We can and should demand

AI Alignment ForumResearchCoT controllability evals seem very under-elicited The CoTControl eval asks reasoning models to follow formatting constraints in their chain-of-thought (e.g. write in all lowercase, avoid a specific word) while solving questions. Models seem to mostly be pretty bad at th
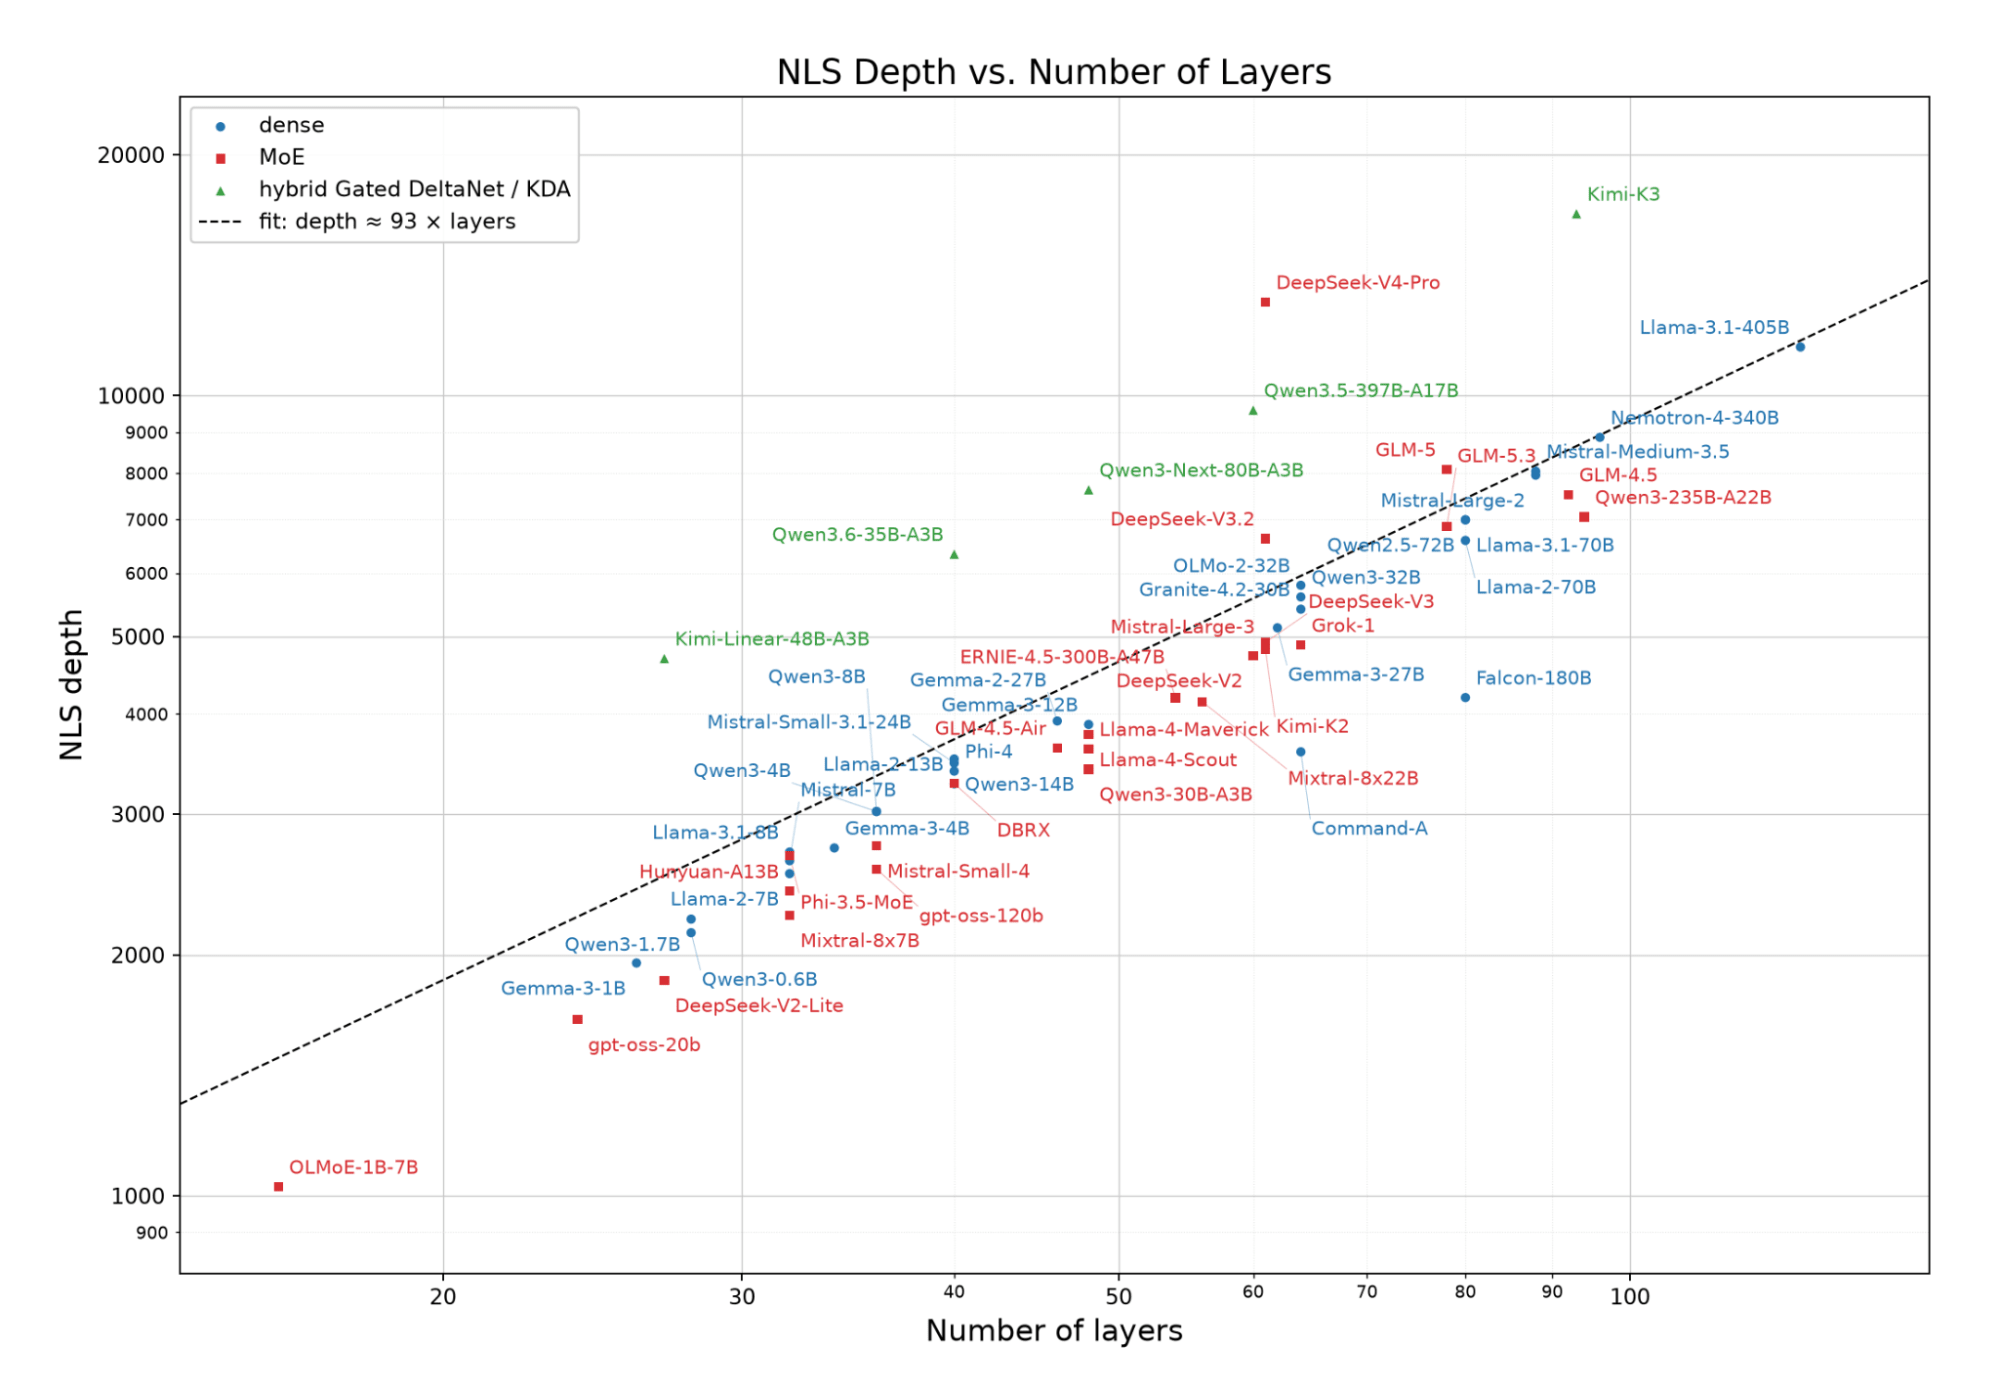
AI Alignment ForumResearchAn operationalization of opaque serial depth Currently, chain-of-thought (CoT) is a valuable tool for overseeing AI models. However, some architectural shifts could significantly reduce CoT monitorability . We have recently proposed that AI companies should transpa
AI Alignment Forum
AI Alignment ForumResearchProposal for tracking the effects of architecture on monitorability Architectures that incorporate opaque recurrence or allow for agents to communicate with each other using latents could rapidly make it much harder to monitor chains of thought or communication (we’ll refer to this prope
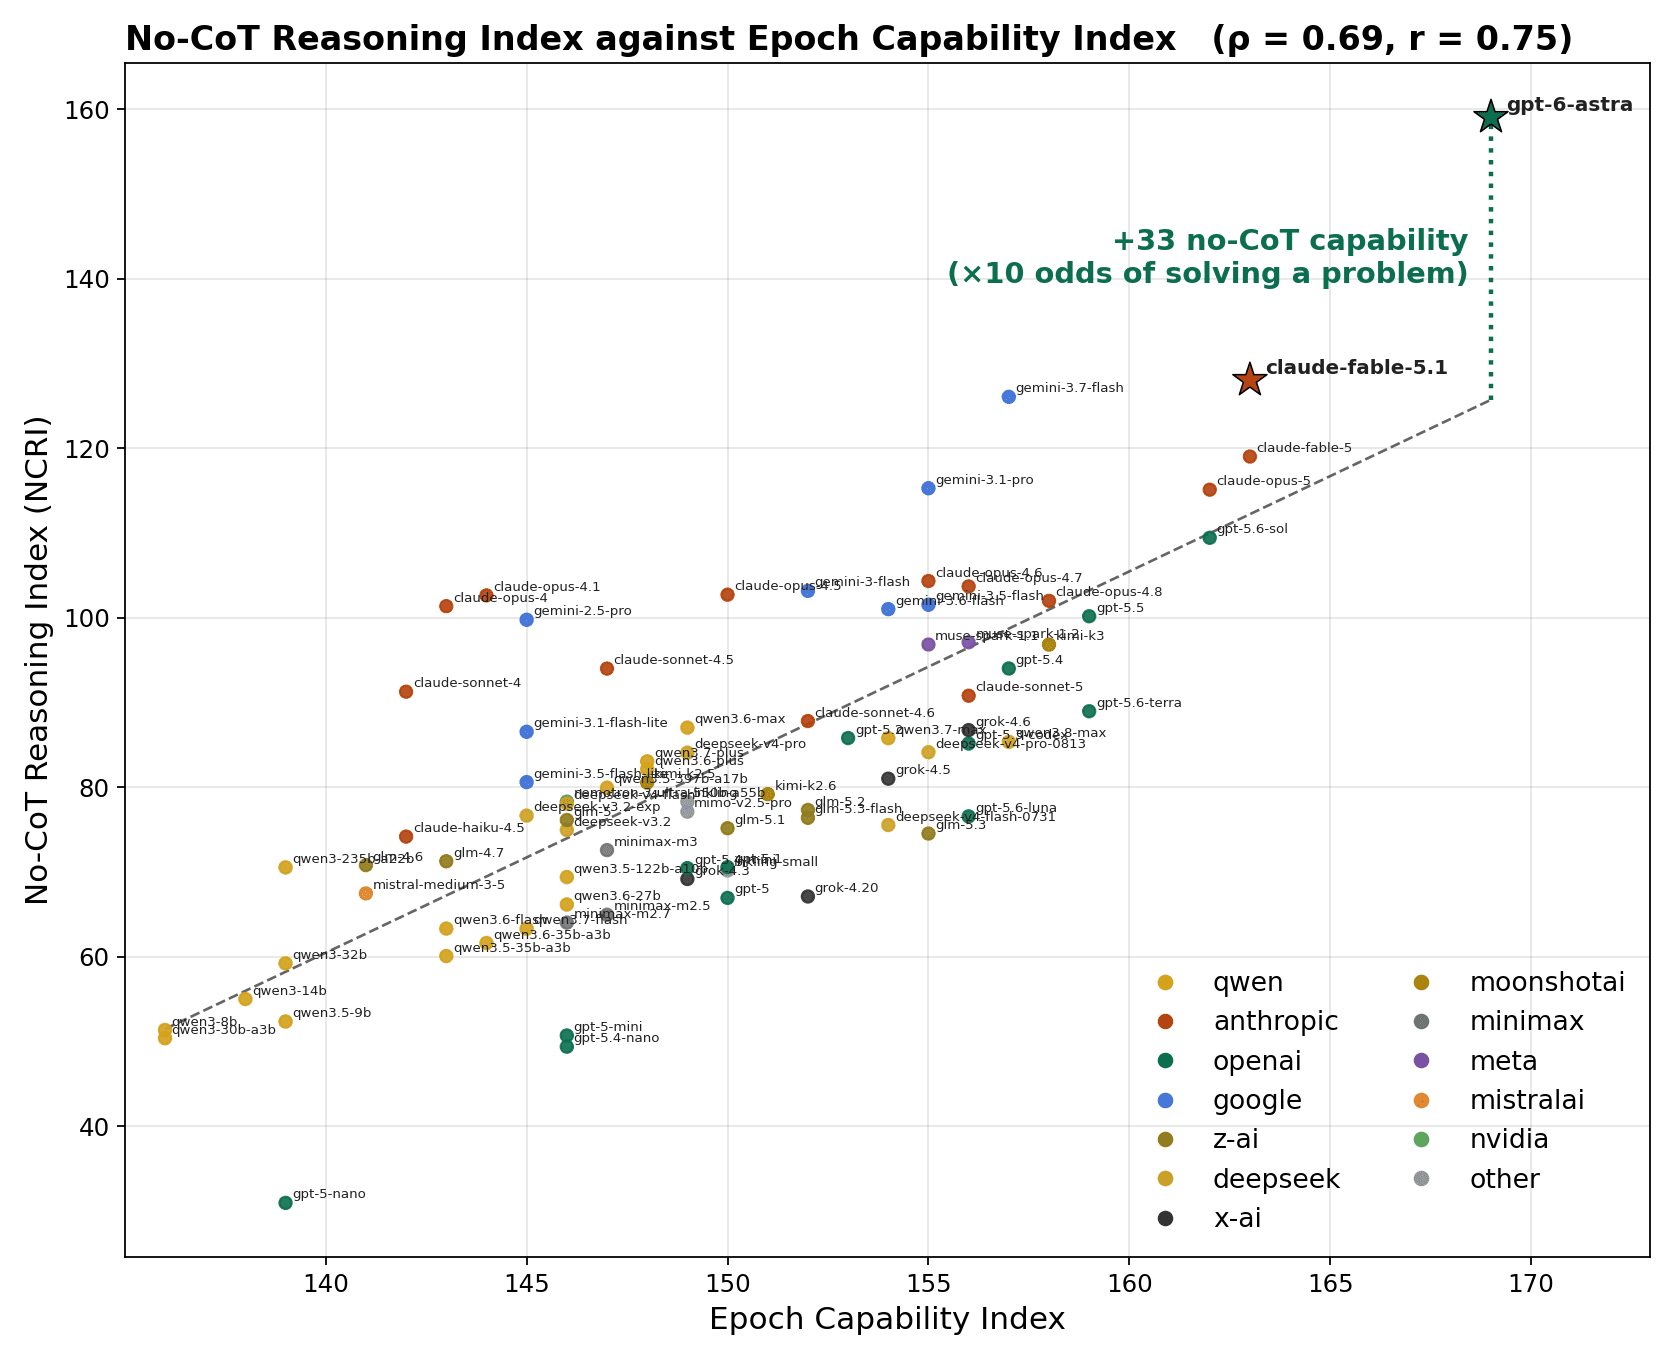
AI Alignment ForumResearchAstra can do a concerning amount with no chain of thought Work done in a personal capacity TLDR : Astra has 8.6x better odds of doing a reasoning task without CoT than the next best model (Fable 5.1), and can do 7.2 serial arithmetic steps in a forward pass vs 4.1 for the next
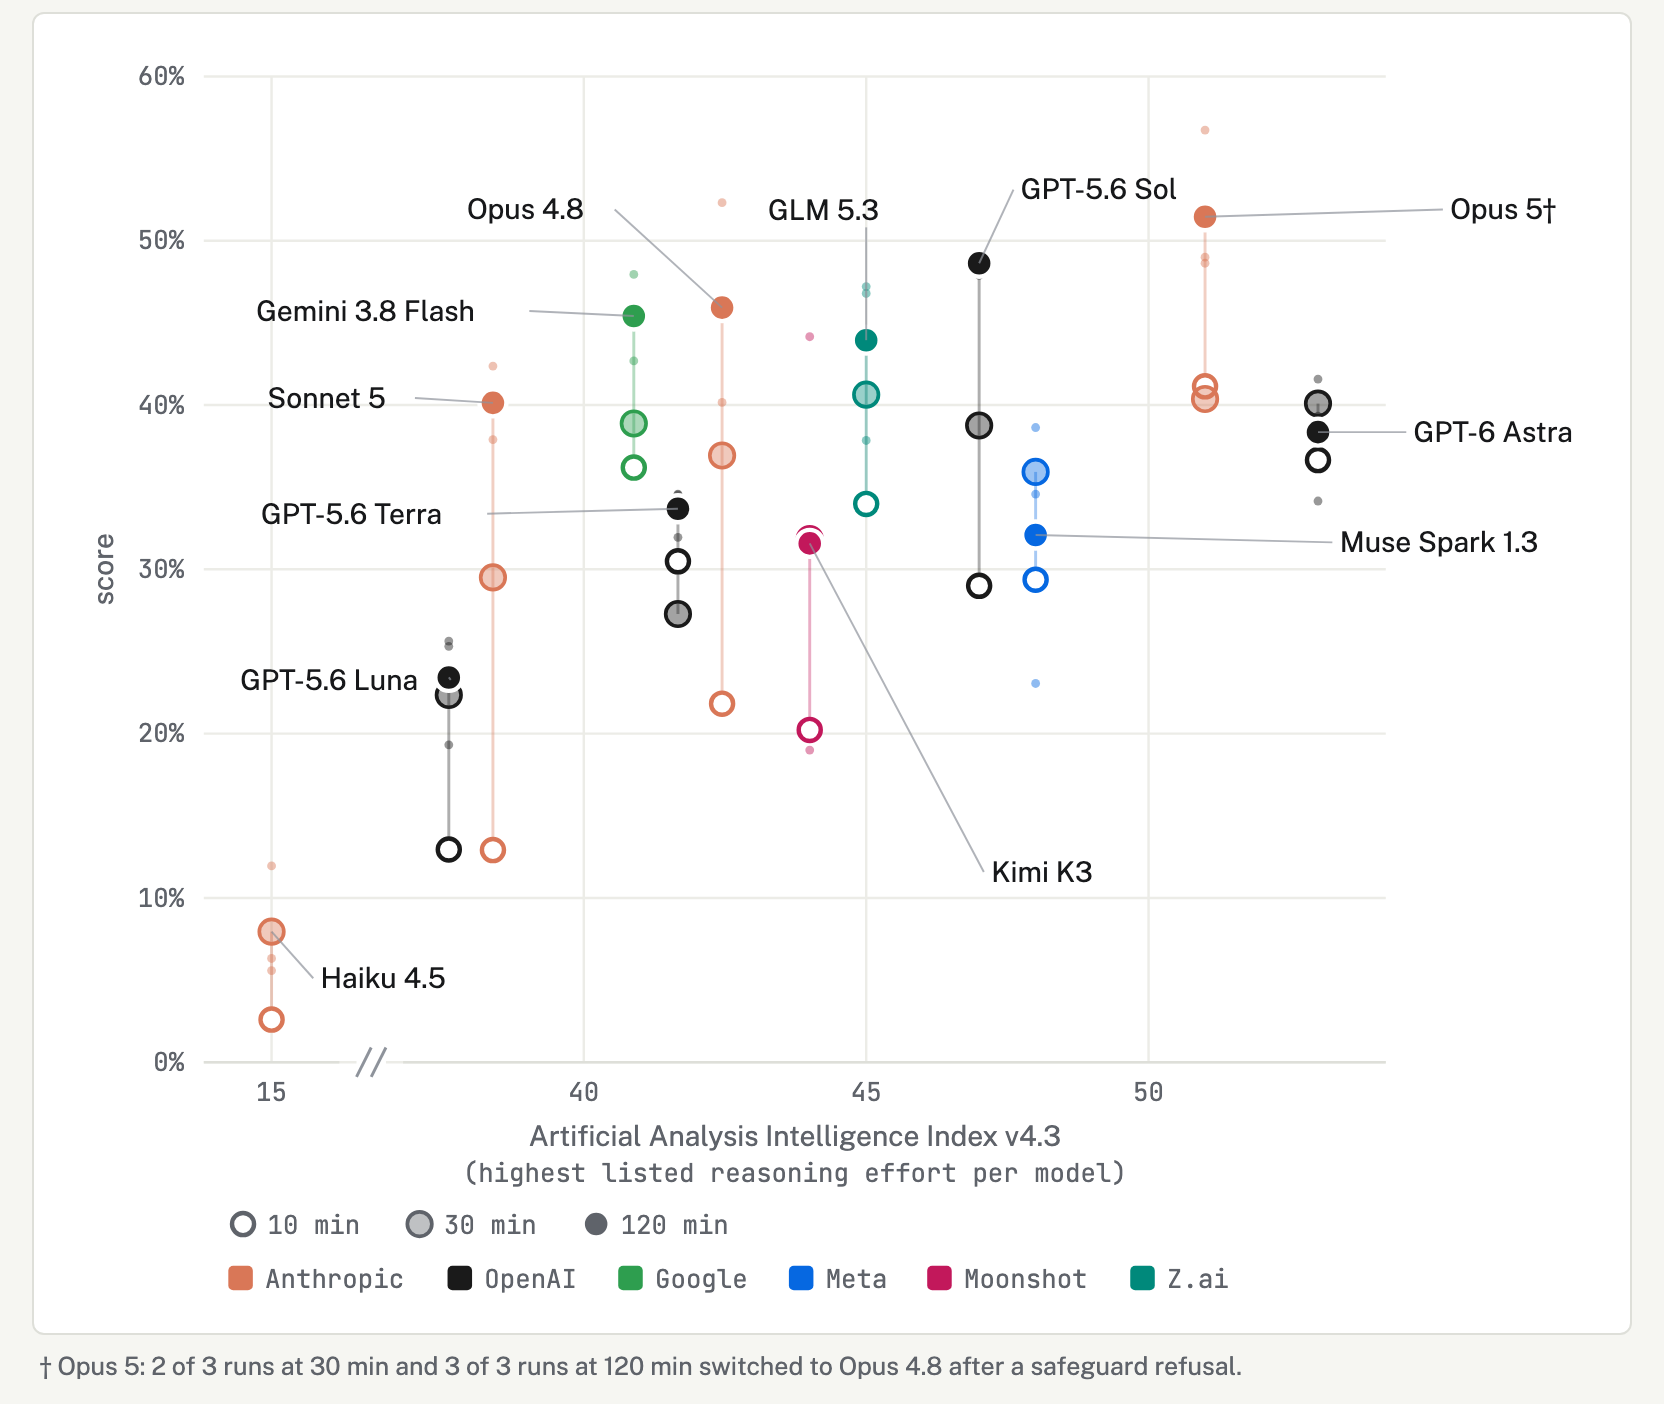
AI Alignment ForumResearchHow good are slop-vestigators? TLDR: We release MessageBoardAuditBench : a benchmark to measure how well agents can replicate the recent investigation into a swarm of OpenAI agents colluding via a message board on an online wiki. We open-source the be
AI Alignment ForumResearchTraining on probes: Research ideas Recap Sequel to Previous Post . This post might not make sense without it. Last post, I told some stories about how training on probes might let our judgments on easy domains generalize to harder domains by leveraging an
AI Alignment ForumResearchTraining on probes: What's going on TL;DR If you train a probe for some property (like "honesty") and do gradient descent against this probe while continuing training that incentivizes dishonesty, the model will change its internal representation to evade
AI Alignment Forum
AI Alignment ForumResearchThe Alignment Journal: Organization, Personnel, and Scope [Cross-posted from the Alignment Journal's blog ] The Alignment Journal is beginning to invite the authors of select papers to submit their work for review. If you are interested in participating as an action editor or a
Nothing matches this filter yet.