Together AI
23 stories
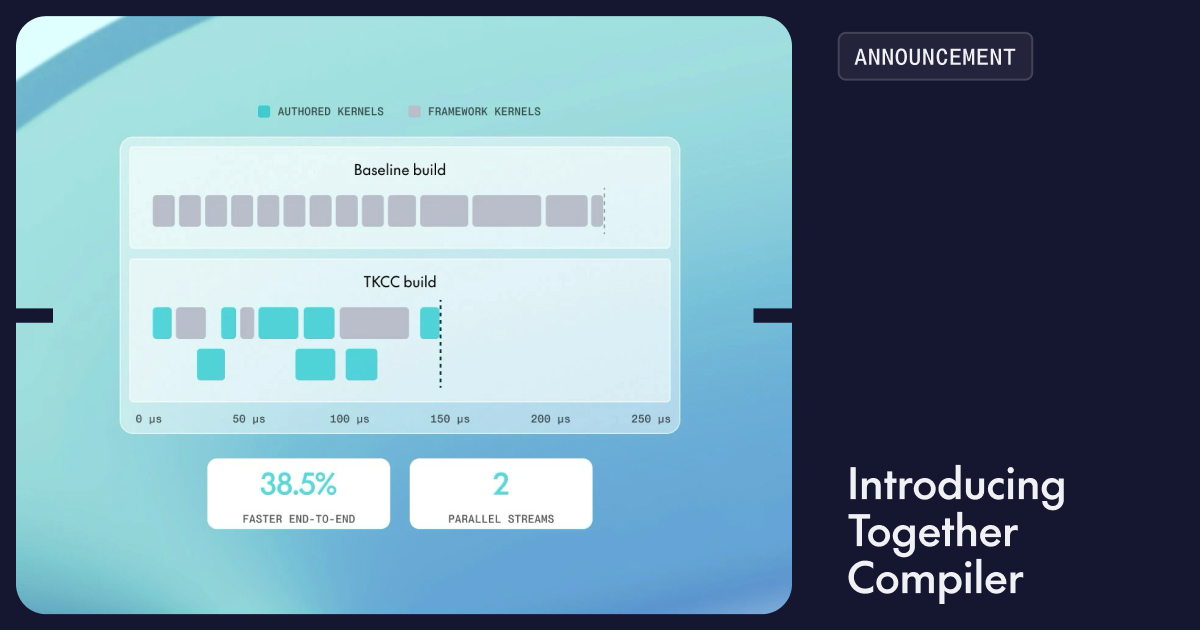
Together AIToolsTogether Compiler: Continual Compilation for AI inference Together Compiler uses agents and persistent engines to optimize open models in under 24 hours, delivering up to 3.7x higher throughput as traffic changes.
Together AIToolsPolymorphic Inference: self-tuning inference for open models Models, traffic and chips are constantly changing. Polymorphic Inference adapts to each, and Together Compiler uses AI agents to keep production inference tuned.

Together AIToolsAuto repair for Together GPU Clusters: from GPU fault to healthy node Together GPU Clusters auto repair detects GPU, host and fabric faults, picks the lightest fix, and lets you decide per fault and per Xid code which repairs run automatically. Here is how it works.
Together AIToolsTogether Post-Training: frontier-grade model shaping, the way that fits you Post-train open LLMs like Qwen, GLM and Kimi into custom models you own, with SFT or RL. You write the training loop. Together runs the hard infrastructure.
Together AIToolsMeta Muse Spark Open is live on Together AI Meta Muse Spark Open, Meta's open-weight model for agentic coding, is live on Together AI with a 1M-token context window on serverless and dedicated infrastructure.
Together AIToolsExpanding our enterprise inference capacity with IBM Cloud and NVIDIA Enterprises can now run open models at production scale on a dedicated B300 inference cluster, built by Together AI, IBM Cloud, and NVIDIA
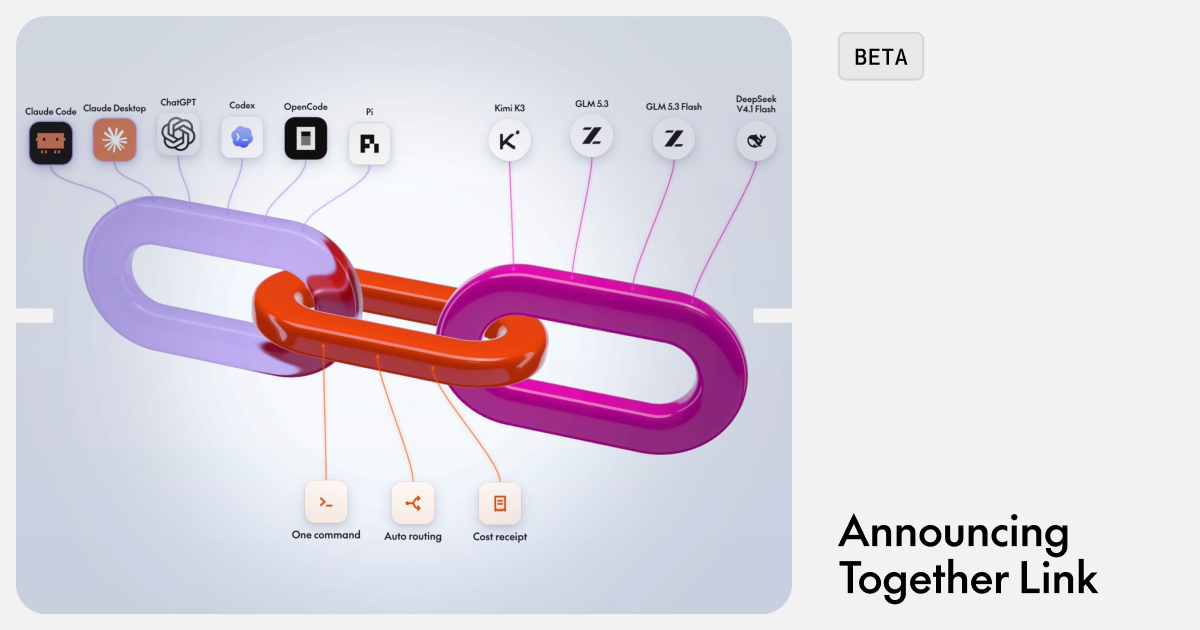
Together AIToolsTogether Link: open models in the harness you already use. Start with one command today. Together Link brings frontier open models like GLM 5.3 and Kimi K3 into the coding agent your team already uses, cutting model spend by over 50%.
Together AIToolsHow to train your own Jev for $17 We just launched our own Jev-like classifier, together/Tev1-4B-experimental, on top of Qwen3.5 4B on Together’s serverless platform. In this blog post we’ll show you how to fine-tune your own version!
Together AIToolsCanary rollouts: upgrade models in production without downtime A hard model swap exposes every user at once, and rolling back means cold-starting the old deployment under pressure.
Together AIToolsHow a global fintech scaled coding agent traffic with Dedicated Model Inference Inside a global bank's shift to self-serve dedicated inference: how Together's DMI gave engineering teams direct control over scaling, models, and testing.
Together AIToolsMigrating from closed to open source models, Together Moving from closed to open source models can take weeks, not years. A five-stage playbook: discover, evaluate, adapt, decide, and production.

Together AIToolsTogether AI expands fine-tuning service with more models, live metrics, and finer controls Together Fine-Tuning adds the latest open-weight models, live experiment tracking, Expert LoRA, early stopping, tokenized dataset previews, pre-flight validation, and lower training prices on…
Together AIToolsIntroducing preemptible compute: the same compute, half the price Together GPU Clusters now supports preemptible compute: the same GPU capacity at a flat 50% of the on-demand rate, with a five-minute drain window.

Together AIToolsTo Infinity and Beyond: ThunderKittens Now on NVIDIA Vera Rubin NVL72! We ported ThunderKittens to NVIDIA's Vera Rubin NVL72 and rebuilt our NVFP4 GEMM around the new hardware, taking it from 42% of roofline to over 22 PFLOPS — competitive with cuBLAS and CuTe DSL.

Together AIToolsThe Open Source AI Stack A deep dive into the open model AI stack — model, inference, gateways and routers, harness, and tools — and how keeping each layer independent lets you swap in a new open model in minutes instead of…
Together AIToolsGLM-5.3 vs. GPT-5.6 Sol on DeepSWE: Cost, Coding, and Routing We ran 904 DeepSWE rollouts on GLM-5.3 and GPT-5.6 Sol. Sol leads pass@1 by 3.7 points; GLM-5.3 wins pass@4 at half the cost, and a GLM-first cascade hits 85.9%.
Together AIToolsGLM-5.3 vs. Claude Fable 5 on DeepSWE: Cost, Coding, and Routing We ran 904 DeepSWE rollouts on GLM-5.3 and Claude Fable 5. A tie on pass@1, but GLM-5.3 wins pass@4 and costs 5.4x less: $3.99 per rollout vs. $21.63.
Together AIToolsDeepSeek V4 Pro 0813 vs Claude Fable 5 on DeepSWE: Cost, Coding, and Routing We ran 904 DeepSWE rollouts on DeepSeek V4 Pro 0813 and Claude Fable 5. Fable leads pass@1 at 90x the cost; Pro wins pass@4, and a Pro-first cascade hits 82.7%.
Together AIToolsA/B test models in production Shadow traffic proves a candidate is operationally sound. It can't tell you if users like it better. Run the split at the endpoint instead of in your app code.
Together AIToolsDeepSeek-V4 Flash 0731 vs GPT-5.6 Luna on DeepSWE: Cost and Coding We ran 900 DeepSWE rollouts on DeepSeek-V4 Flash and GPT-5.6 Luna. Luna leads pass@1 by 14 points; DeepSeek delivers 4.8x the solves per dollar.

Together AIToolsKimi K3: the complete developer guide Kimi K3 is the first open 3T-class model. See how it benchmarks, what it costs, and how to call it on the Together AI API, with copy-paste code examples.

Together AIToolsAutoscaling endpoints for LLM inference GPU utilization can read healthy while your queue backs up, and a new replica takes minutes to warm. Here's how to pick autoscaling metrics, tune scale-up/down windows, and budget for cold starts on…
Together AIToolsTogether AI announces strategic partnership with Moonshot AI to natively serve Kimi models Together AI partners with Moonshot AI to natively serve Kimi models, starting with the 2.8T parameter Kimi K3, with day zero access and post-training.
Nothing matches this filter yet.