vLLM BlogTools
Achieving near-zero-downtime scaling in Elastic Expert Parallelism
How asynchronous preparation and NIXL EP enabled near-zero-downtime Elastic EP scaling in vLLM.
Read at vLLM Blog ↗Related
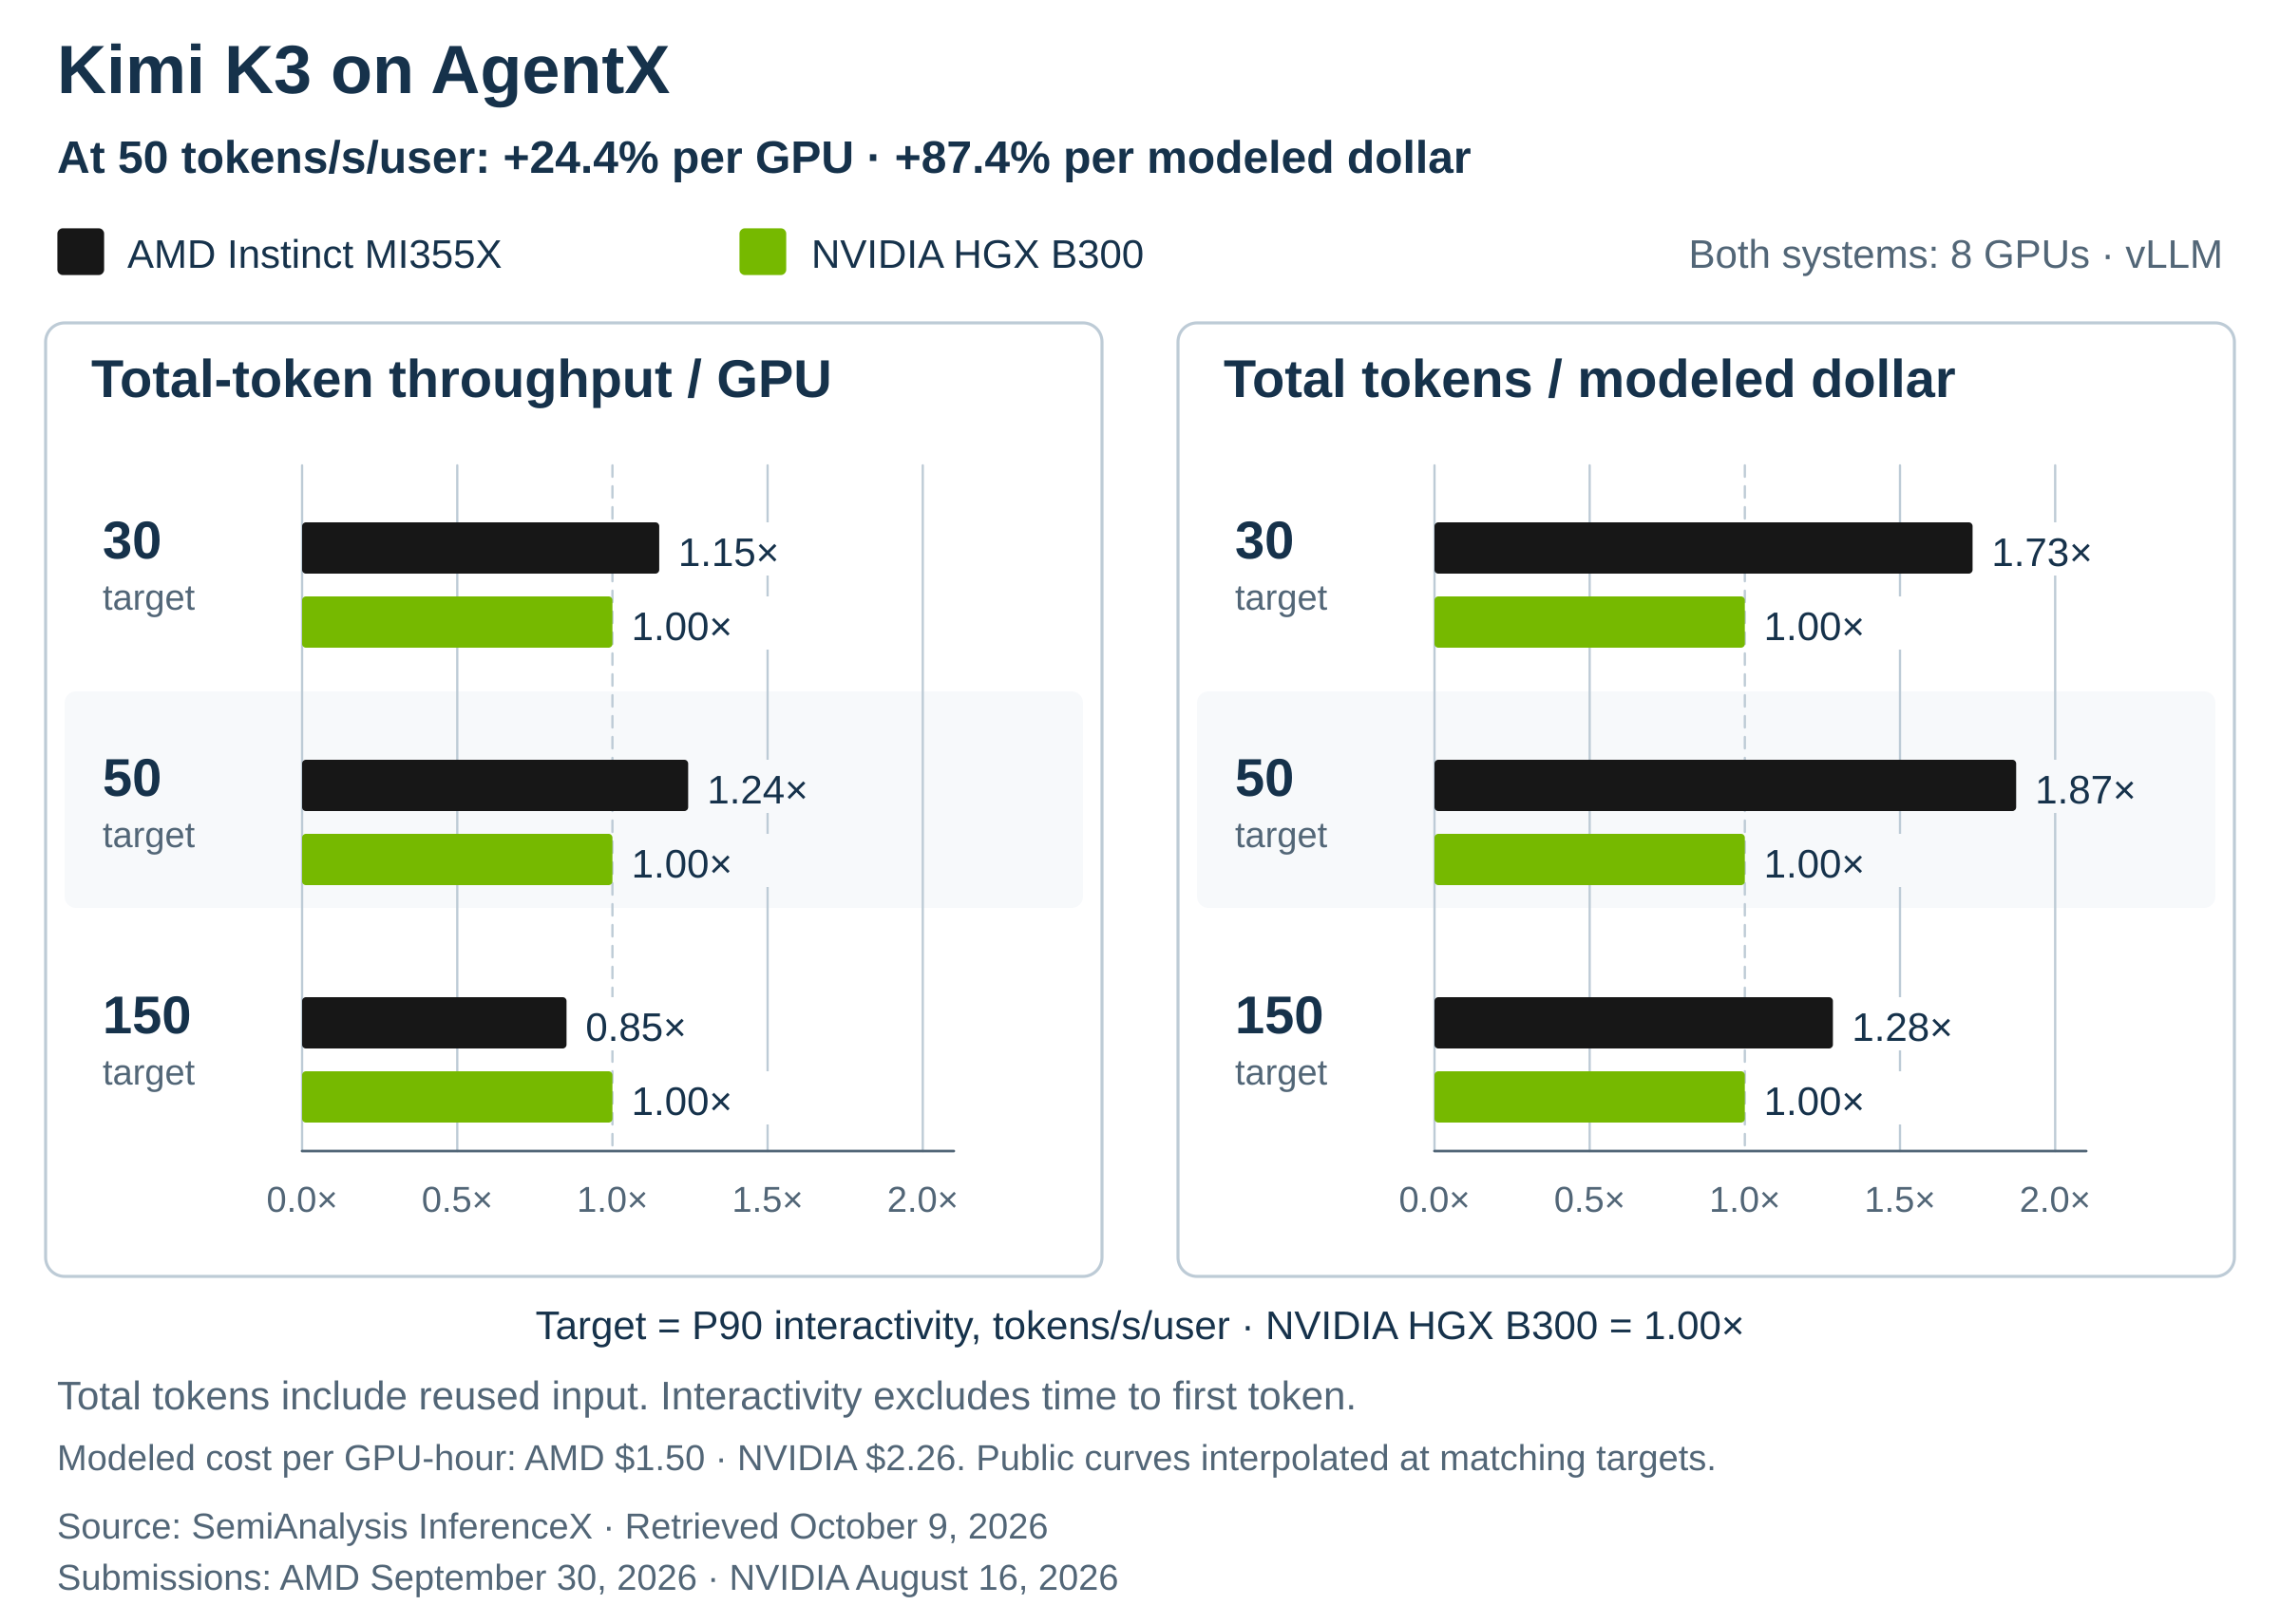
ToolsScaling Kimi K3 on AMD Instinct MI355X: Matching NVIDIA HGX B300 Throughput per GPU on AgentX vLLM Blog
ToolsScaling Multi-GPU Video Captioning with PyNvVideoCodec and vLLM vLLM Blog
LabsBuilding trust in AI agents: A production-ready evaluation framework with Amazon Bedrock AgentCore AWS Machine Learning
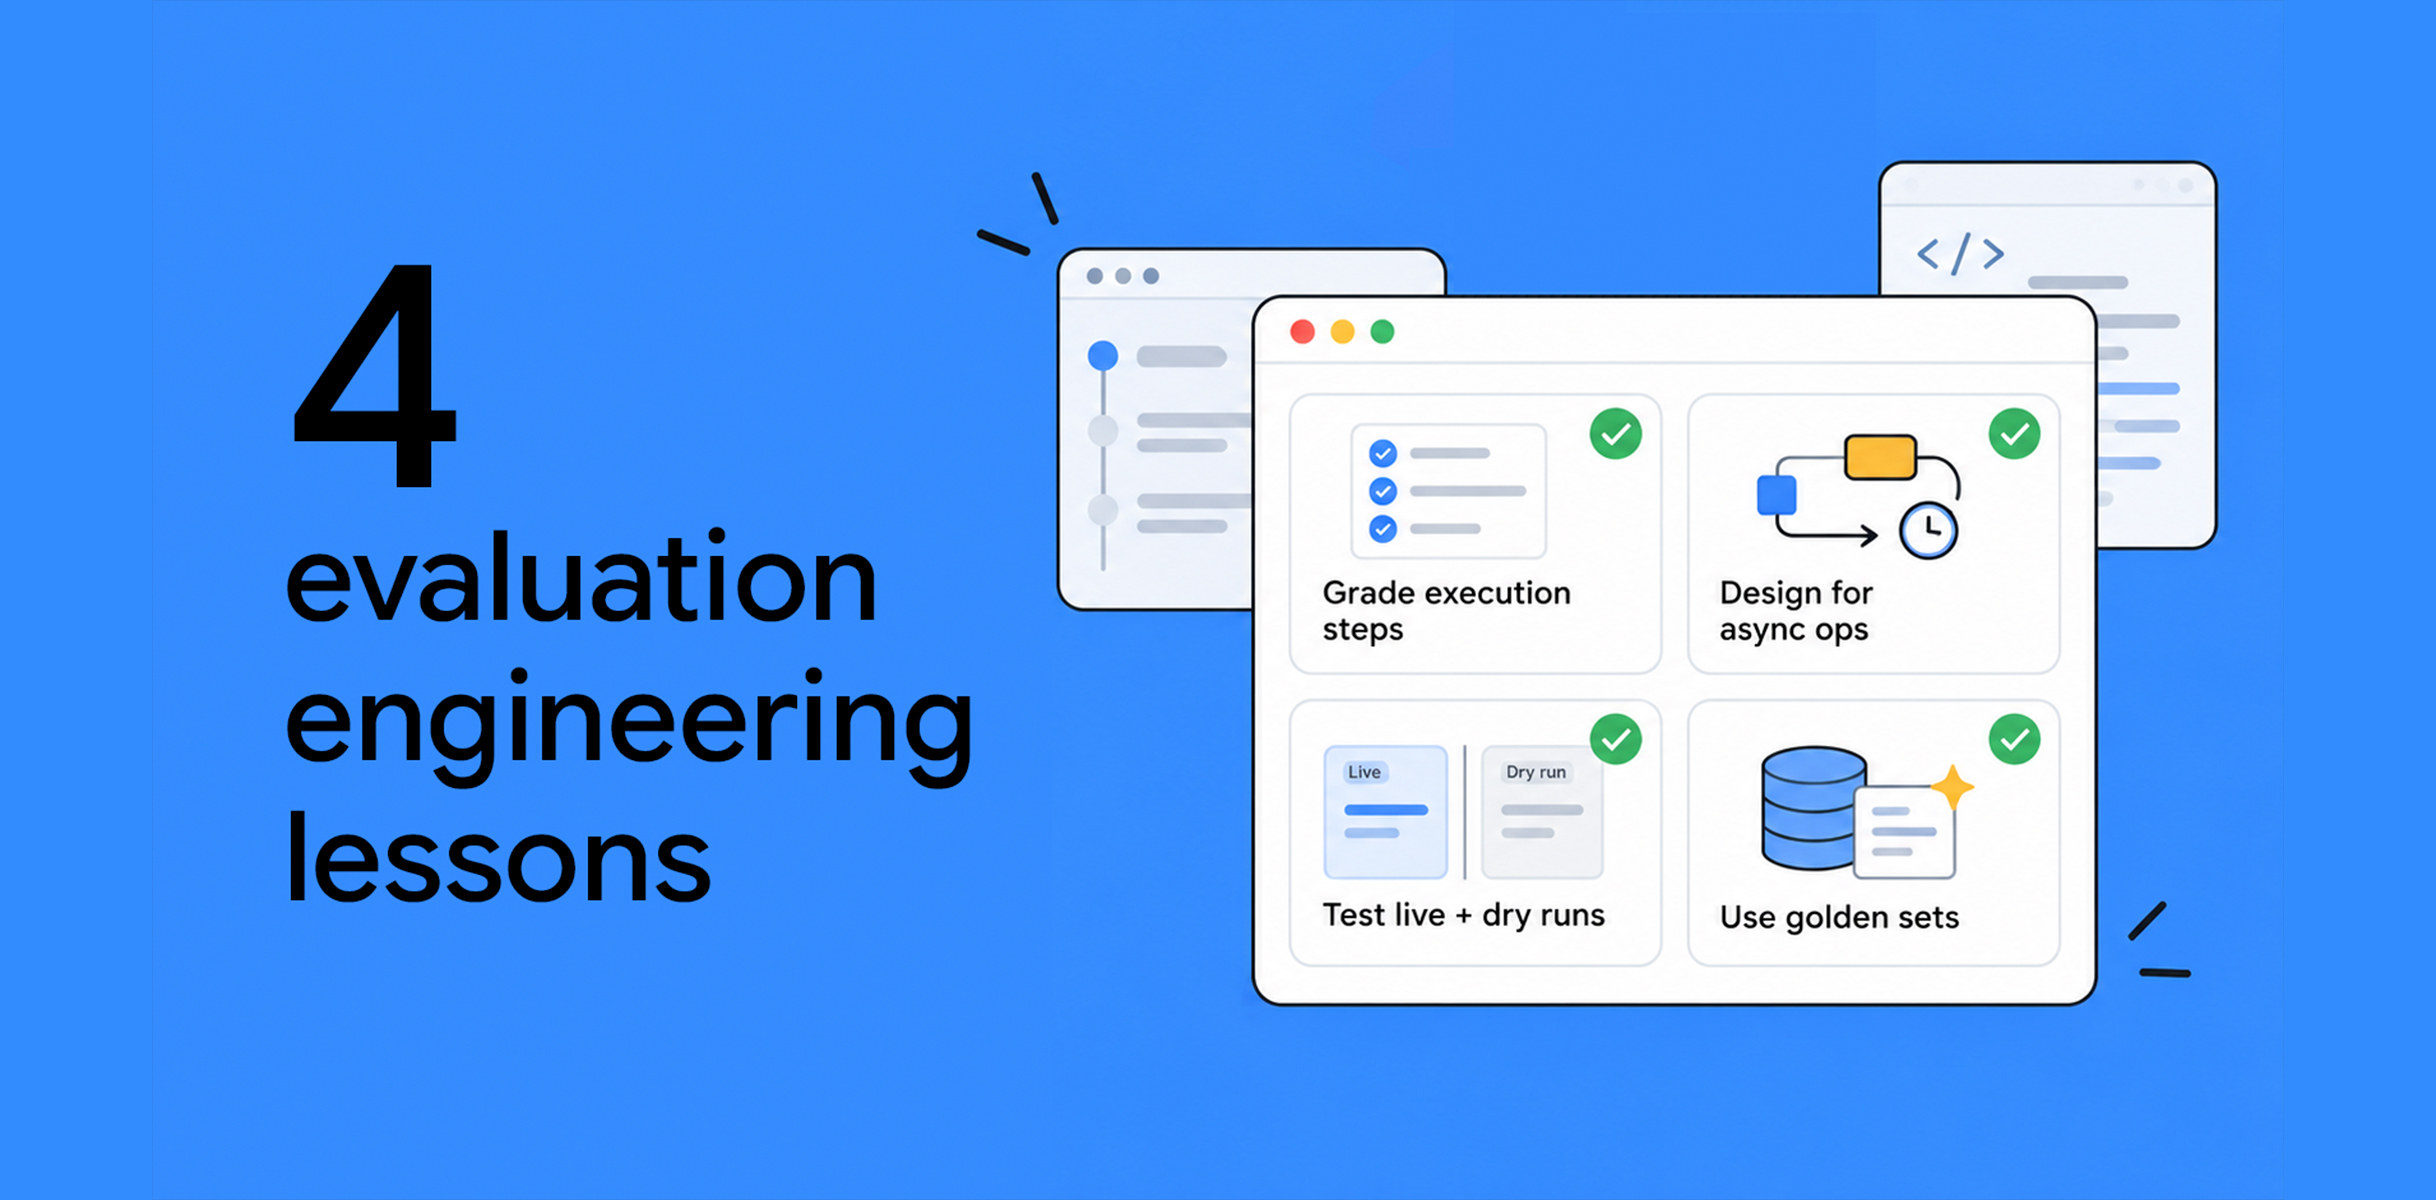
LabsFour evaluation engineering lessons learned from building agent plugins Google Cloud AI
ResearchHe Wants AI Benchmarking To Be a Science, Not a Dark Art Quanta Magazine