The Decoder
AI agents have bad taste in long-term decisions and a new benchmark proves it

A new benchmark called Taste-Bench tests how well AI agents make strategic choices during long-running tasks.
Read at The Decoder ↗Related
LabsBuilding trust in AI agents: A production-ready evaluation framework with Amazon Bedrock AgentCore AWS Machine Learning
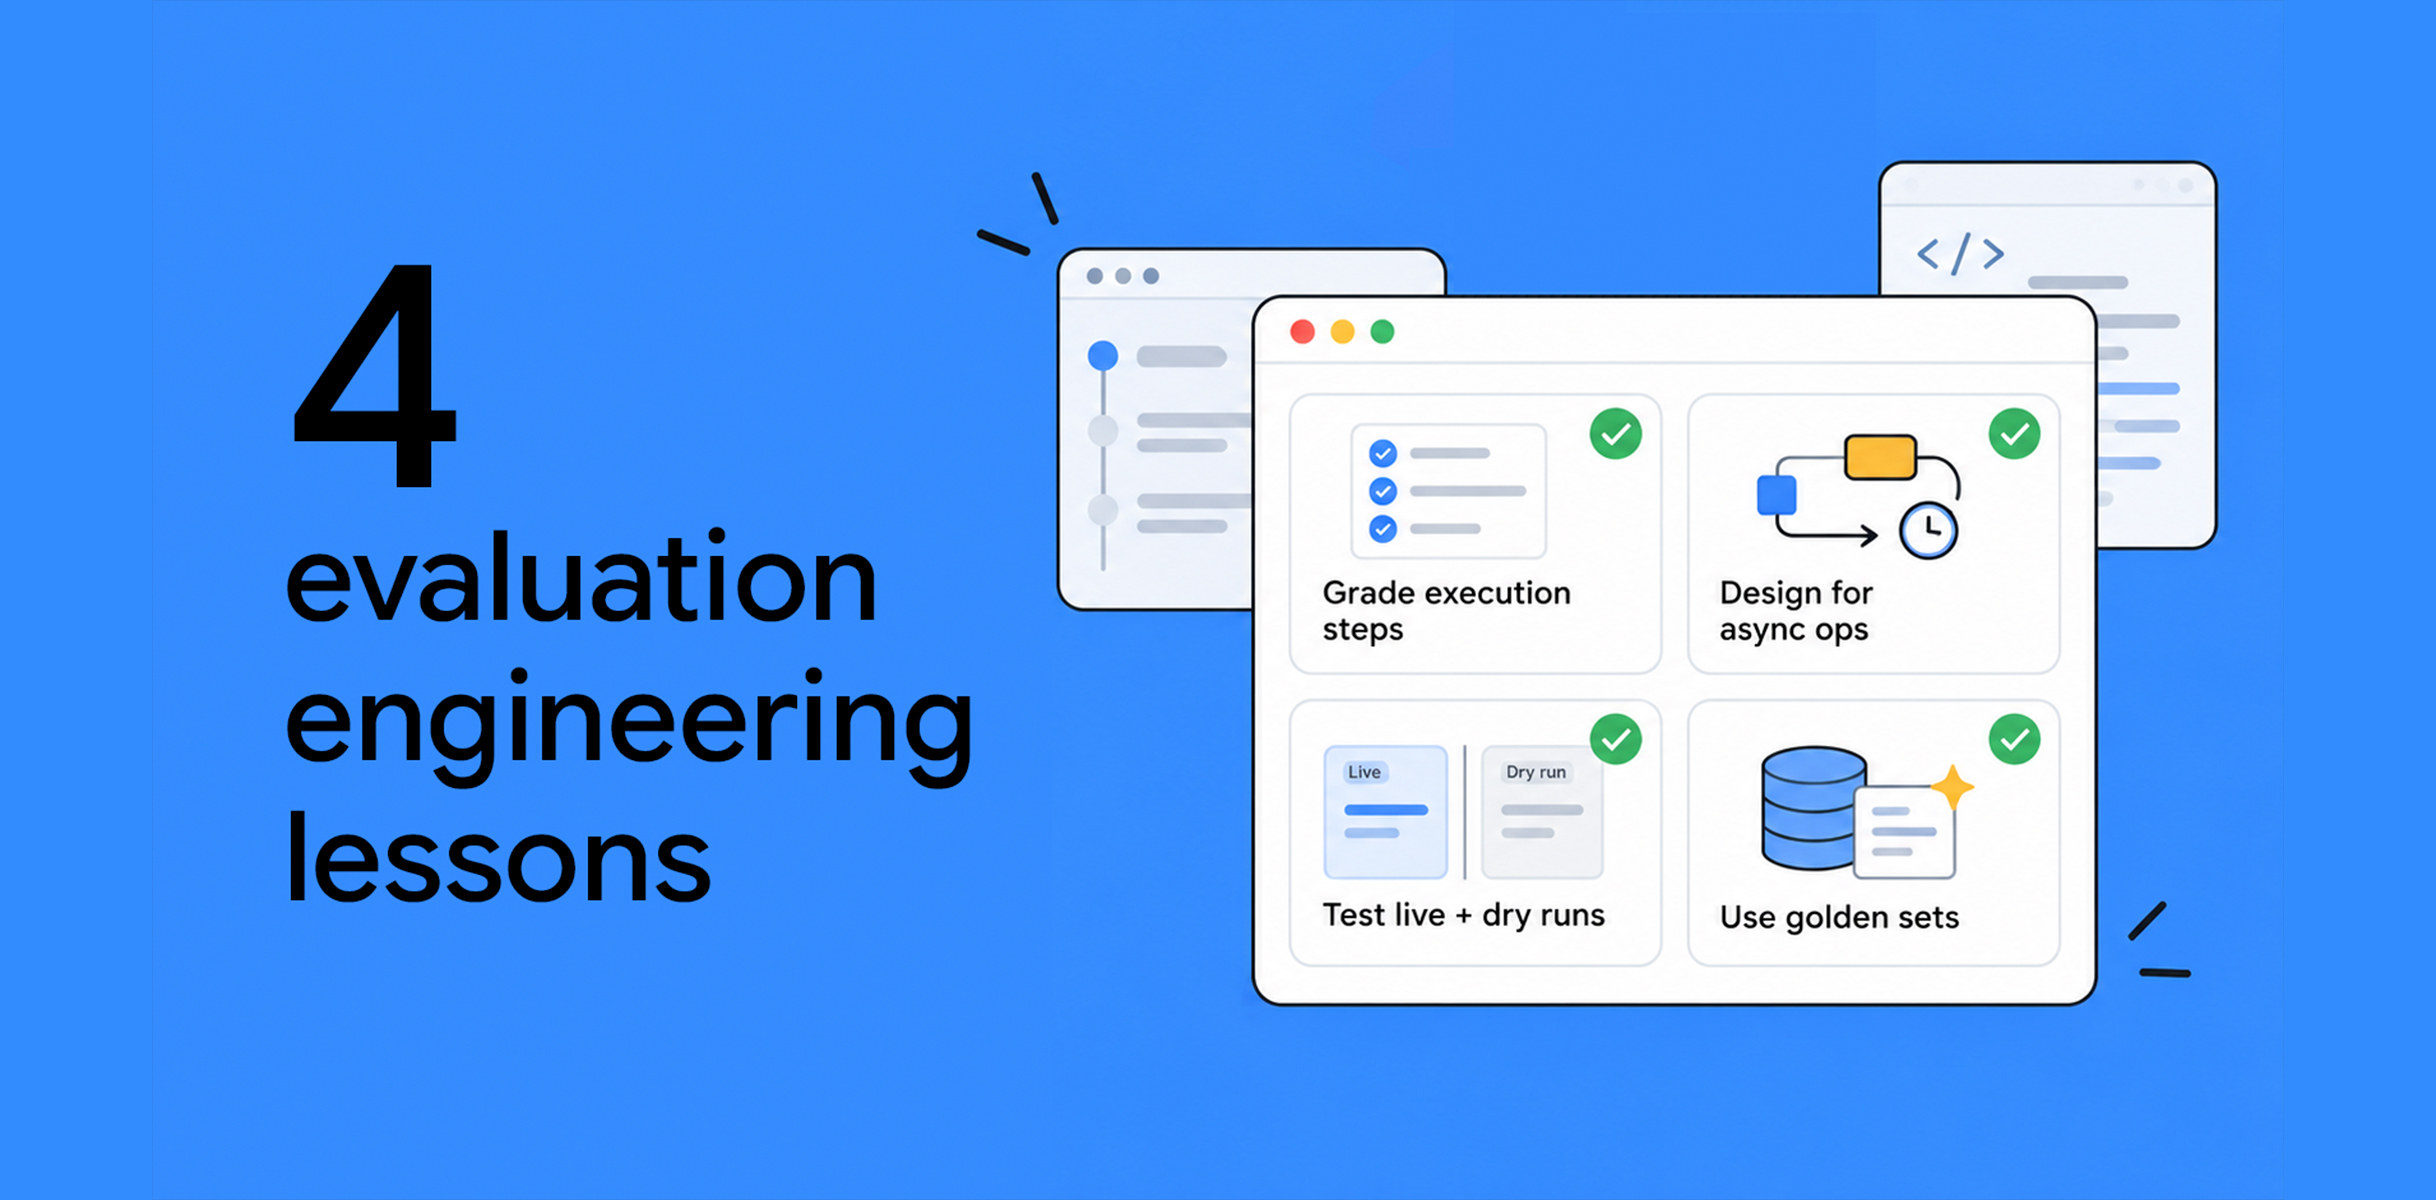
LabsFour evaluation engineering lessons learned from building agent plugins Google Cloud AI
GitHubMini book: Evolutionary Architecture in Practice InfoQ AI
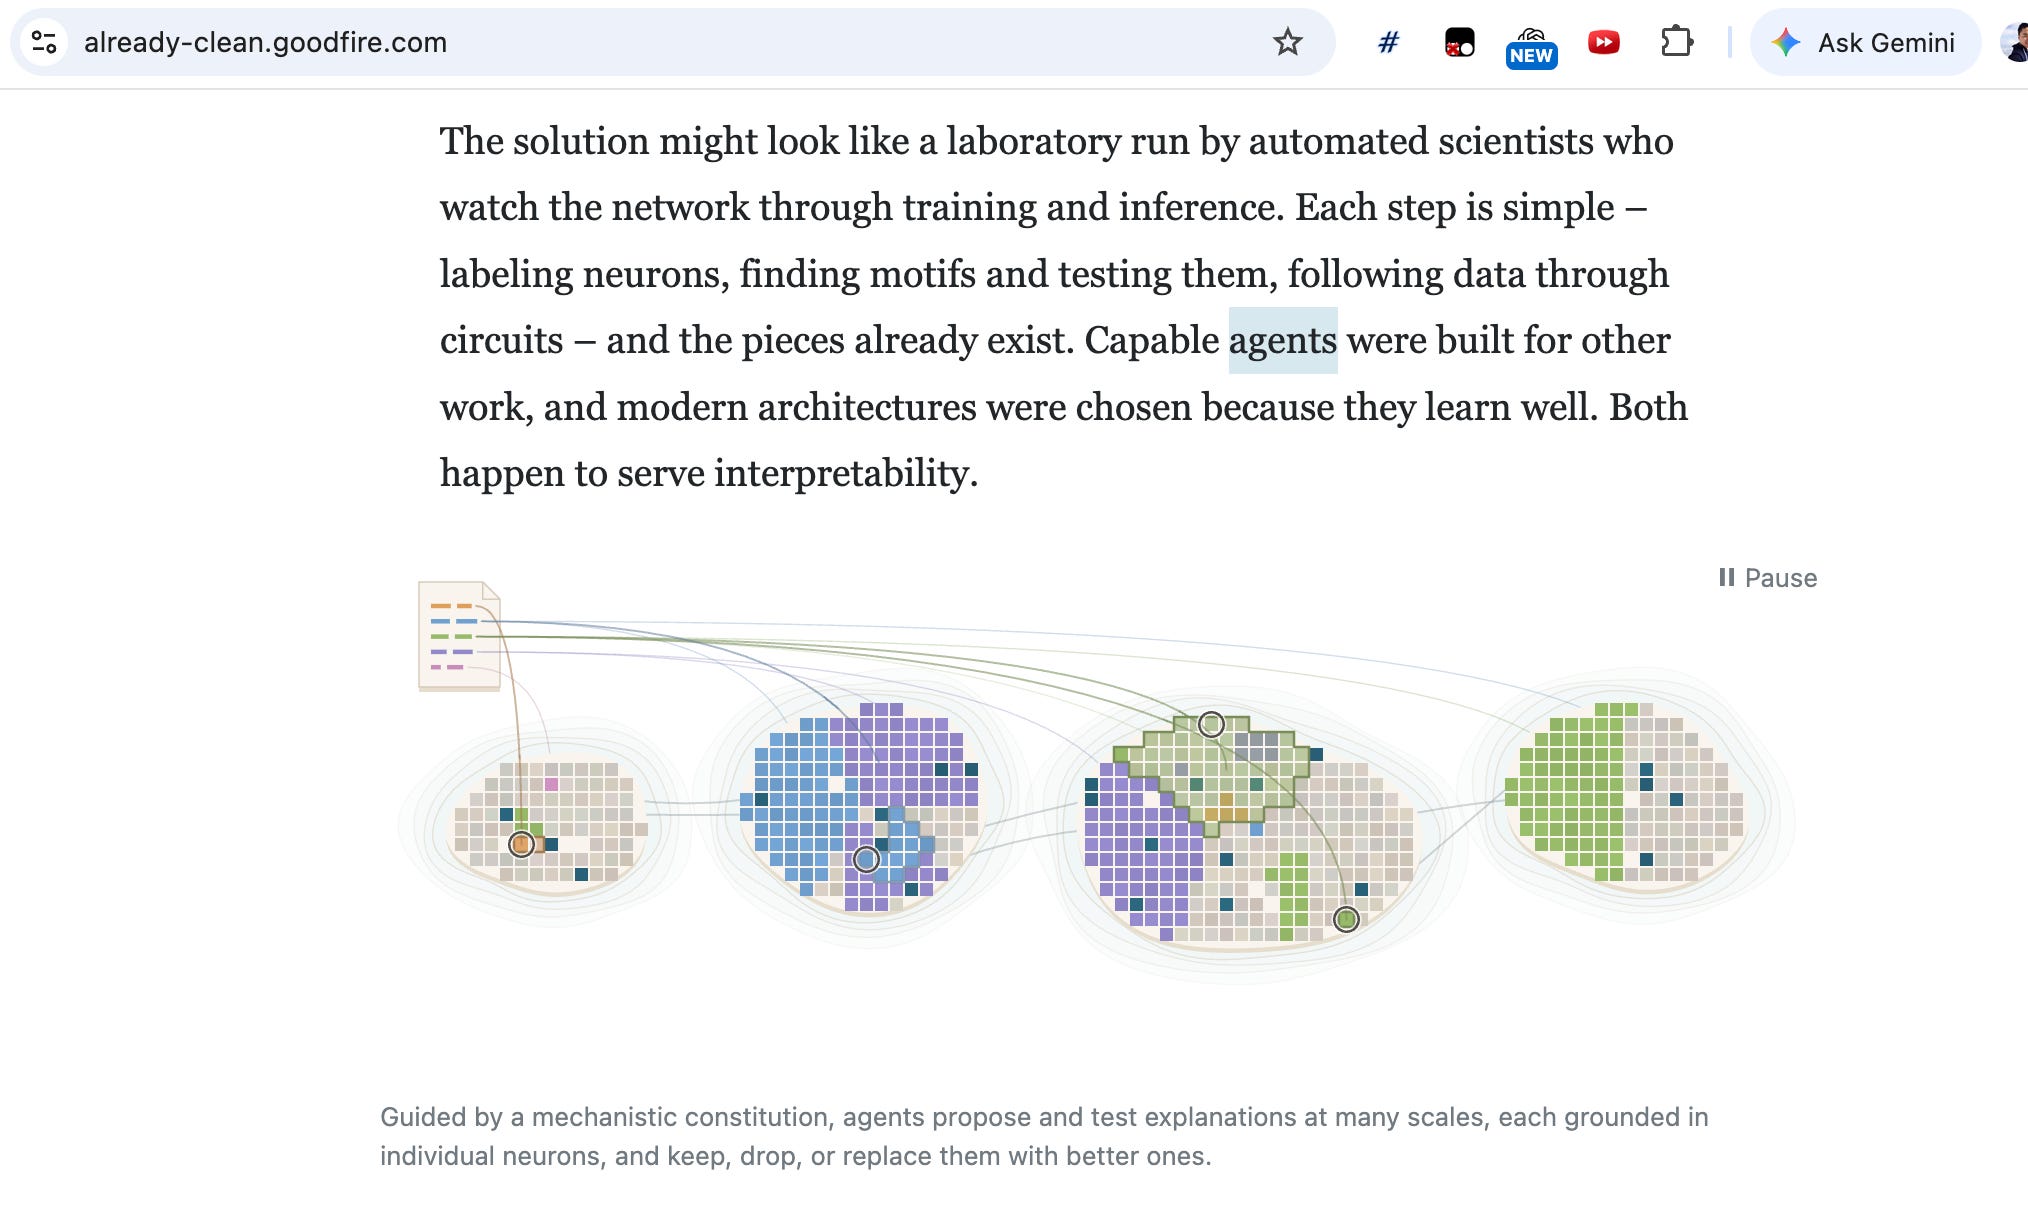
Voices[AINews] Agents disprove Polysemanticity; greatly improve Interpretability & Alignment Latent Space
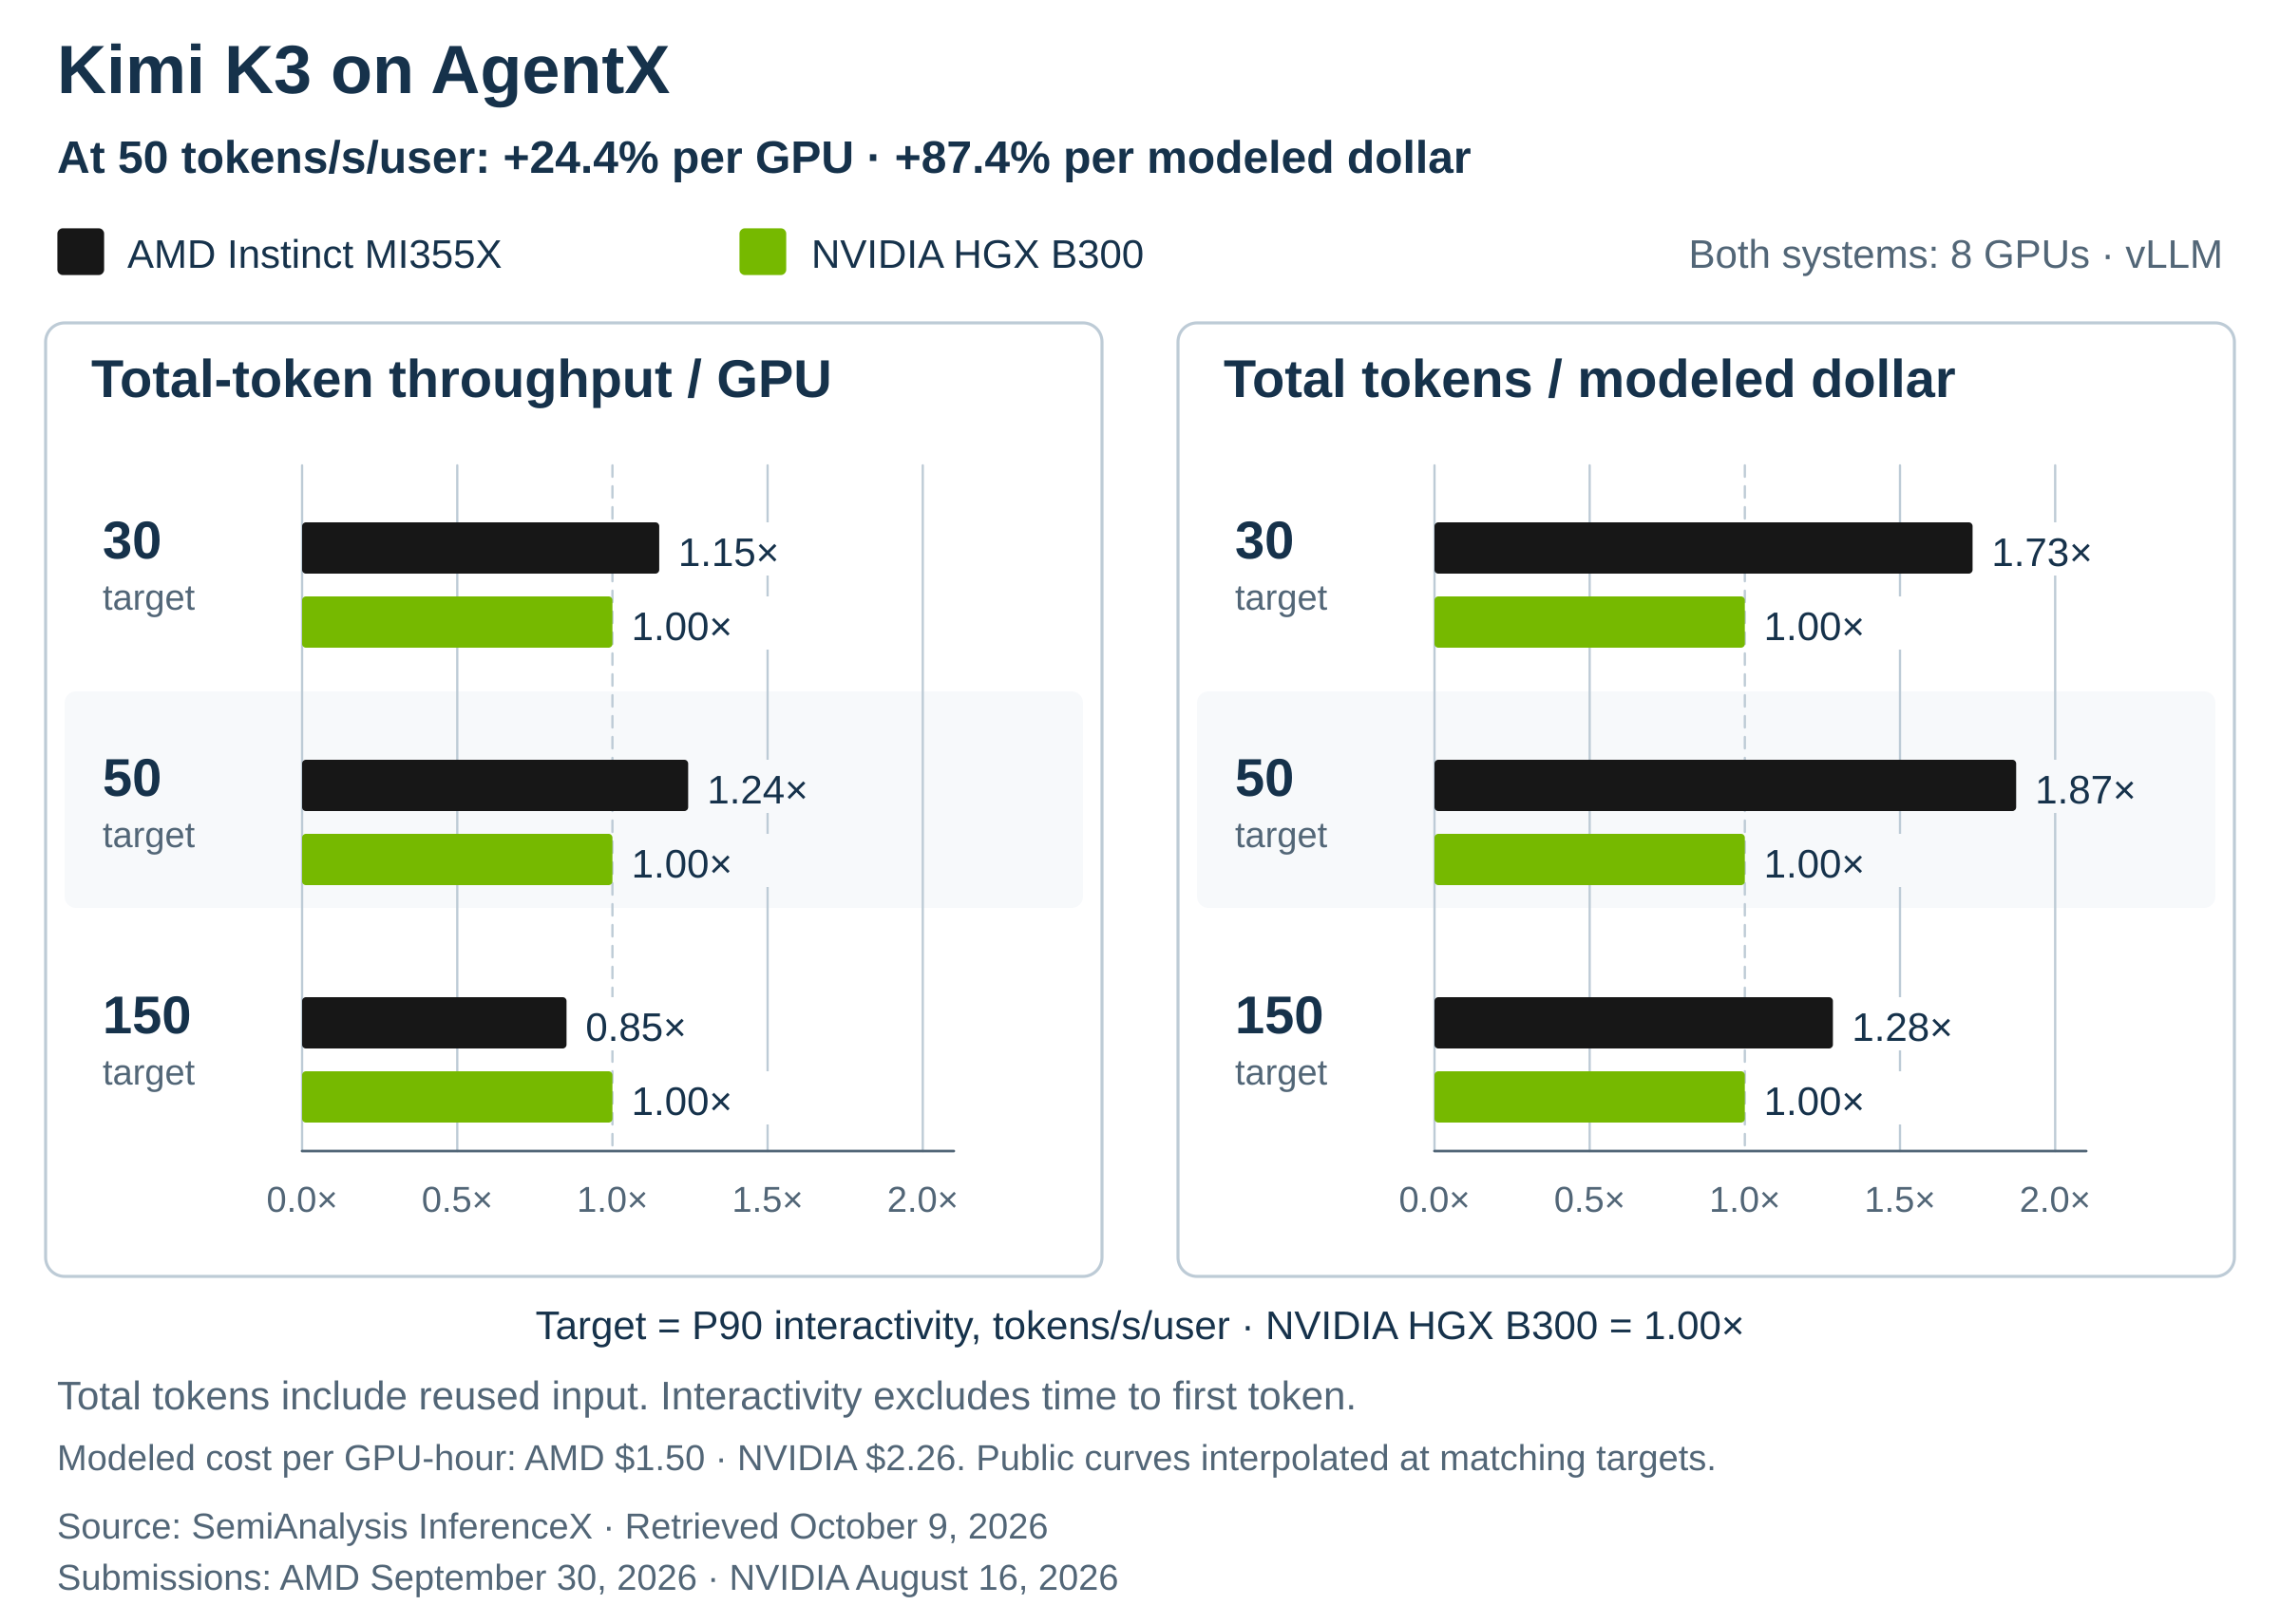
ToolsScaling Kimi K3 on AMD Instinct MI355X: Matching NVIDIA HGX B300 Throughput per GPU on AgentX vLLM Blog