The New StackGitHub
AI’s best coding agent fails 60% of the time — and the data backs it up

Claude Fable 5.1 just won a new coding benchmark despite failing more than six out of 10 times. Its 38.8% score comes from Real-SWE, a benchmark from Y Combinator-backed Specific Labs that takes a…
Read at The New Stack ↗Related
GitHubPresentation: Decision Models in Agentic Architectures: From Production to Agent Skills InfoQ AI
GitHubPresentation: From Retrieval to Reasoning: Building Production-Ready Agentic AI Systems with Knowledge Graphs InfoQ AI

LabsMonitoring production agent lifecycle with AWS DevOps Agent and AgentCore Evaluations AWS Machine Learning

SiliconFrontier Reasoning Reaches the Edge: How to Deploy and Optimize Models on NVIDIA Jetson NVIDIA Technical Blog
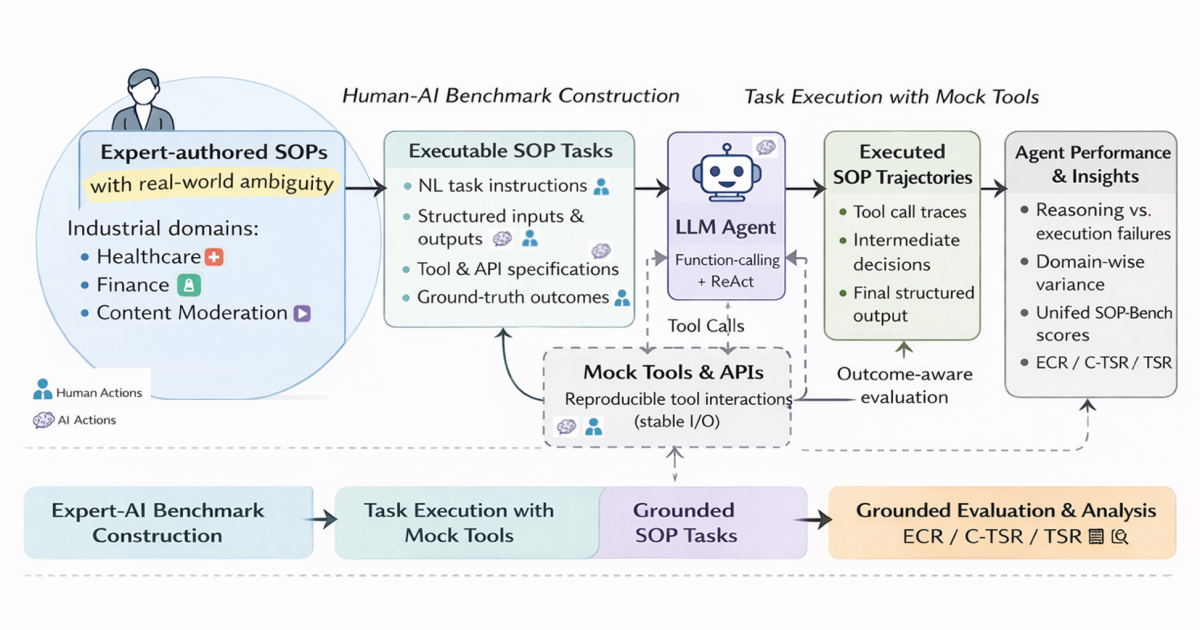
ResearchSOP-Bench: A new benchmark for evaluating AI agents on real business procedures Amazon Science