llama.cpp releasesTools
b11390
CUDA: fix MMQ memory fault if n_expert >> n_ubatch ( #29941 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/52581427 macOS/iOS: macOS Apple Silicon…
Read at llama.cpp releases ↗Related
AsiaAmazon to invest $1b in US data center communities Tech in Asia
ValleyAmazon’s $1B plan to combat data center backlash draws more backlash Ars Technica AI
ValleyReport: Amazon to offload $8B worth of AI chips, lease them back SiliconANGLE
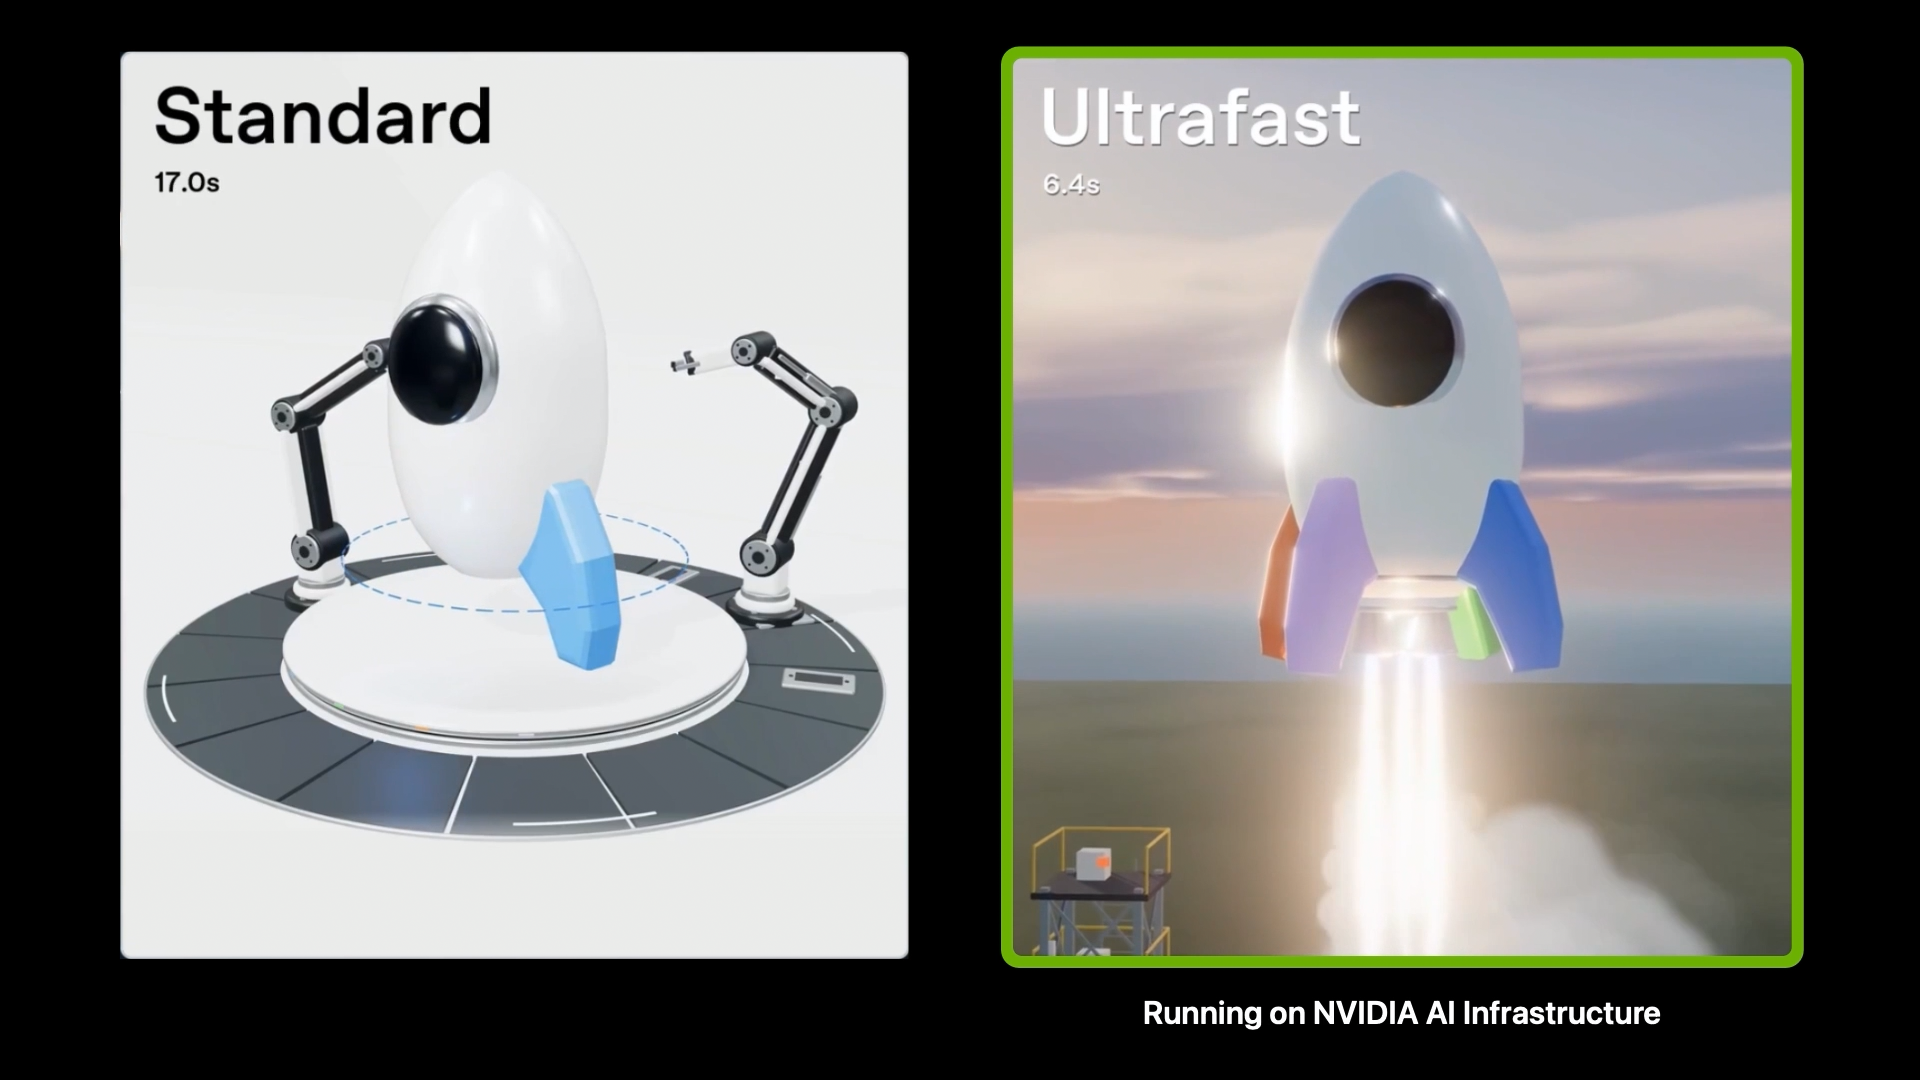
SiliconHow NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast NVIDIA Blog

SiliconDeepSeek and Huawei release open-source Ascend AI programming tools to reduce reliance on Nvidia ecosystem Tom's Hardware AI