llama.cpp releasesTools
b11448
cuda: BF16/FP16 conversion to f32 chunking ( #29442 ) ggml-cuda: chunk large BF16/FP16 to F32 conversions Update ggml/src/ggml-cuda/ggml-cuda.cu Co-authored-by: Johannes Gäßler [email protected]…
Read at llama.cpp releases ↗Related
Toolsb11447 llama.cpp releases

SiliconNVIDIA Releases GeForce 617.42 WHQL Game Ready Drivers TechPowerUp

SiliconAxelera AI: Data Center Inference Performance in the Power Envelope of Embedded Systems EE Times
ResearchSovereign AI, same landlord — thoughts on the physical AI race The Robot Report
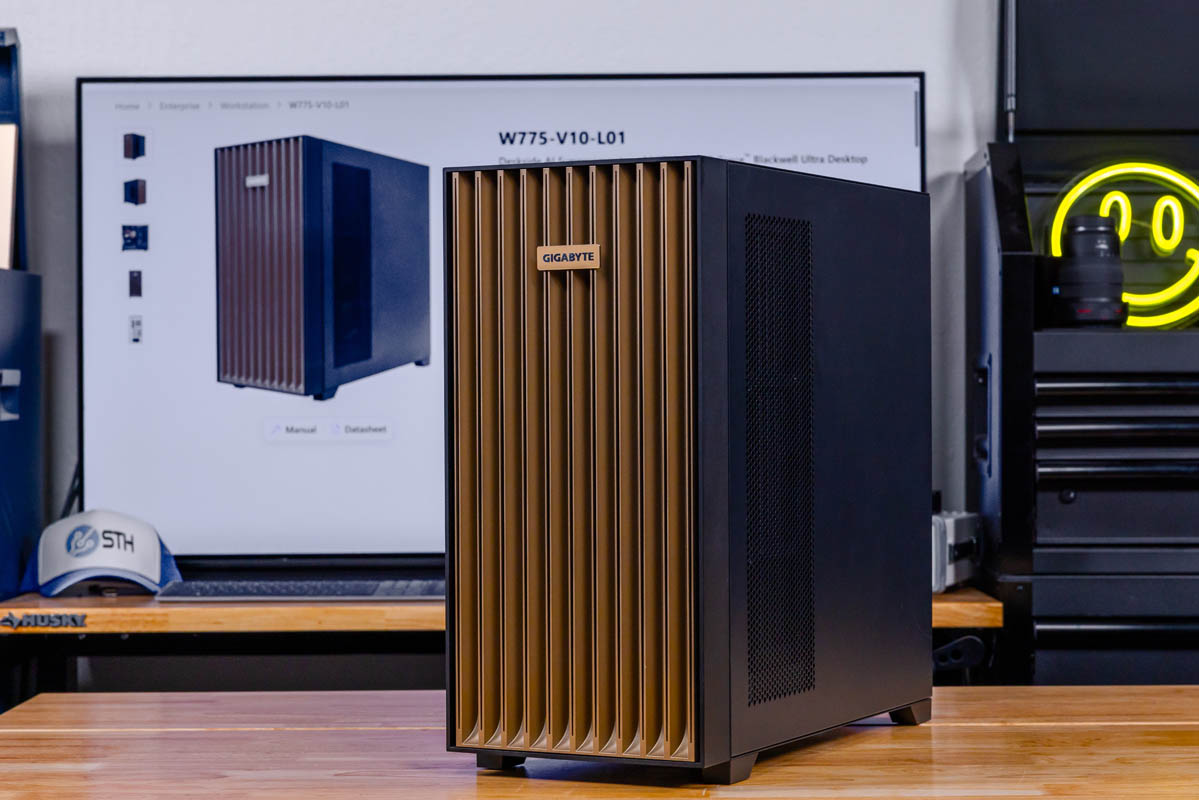
SiliconGigabyte W775-V10-L01 Hands-on Bringing NVIDIA GB300 Deskside ServeTheHome
