llama.cpp releasesTools
b11453: llama: remove the gather path of the glm5-next sparse attention (#30042)
The gather path attended over the selected latents with a plain matmul and softmax. It only ran with n_ubatch <= 16, and the flash attention backends now skip the masked rows through n_kv_max, so…
Read at llama.cpp releases ↗Related

GitHubEmbeddingGemma 2: An open, lightweight multimodal embedding model Hacker News (front)

ValleyAnthropic is giving startups a free year of Claude Team and $1,000 in credits TechCrunch AI
EuropeDelivery Hero alumni have built 150 startups worth €7.5B, making it Europe’s biggest founder factory Tech.eu
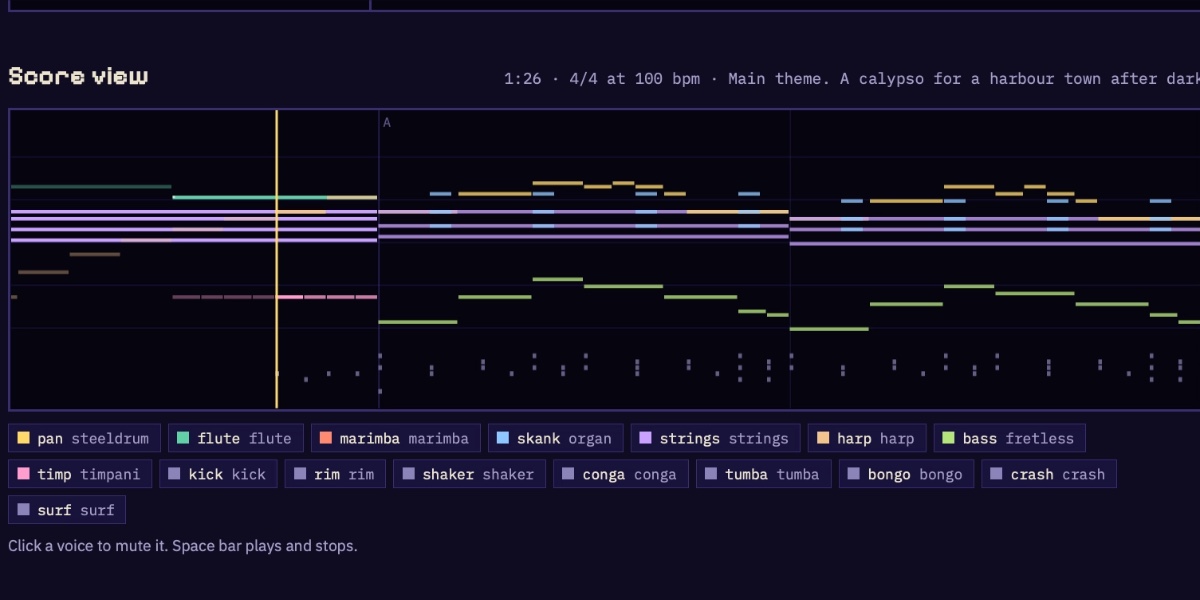
VoicesScrimshaw Jukebox Simon Willison

ValleyMistral’s new 1T model aims to leapfrog closed and open rivals TechCrunch AI