llama.cpp releasesTools
b11507
llama: support MoE cache over multiple GPUs ( #30112 ) Website: https://llama.app Attestations: https://github.com/ggml-org/llama.cpp/attestations/53988921 macOS/iOS: macOS Apple Silicon (arm64)…
Read at llama.cpp releases ↗Related

ChatGPT with GPT-6 ditches mostly text output for interactive UI with charts, buttons, and mini apps The Decoder
AsiaShanghai AI Lab Open-Sources Intern-Decision, Small Models That Output Decisions, Not Text Pandaily
SiliconOpenAI and Synopsys partner to build "GPT-Synopsys" for autonomous chip design Tom's Hardware AI
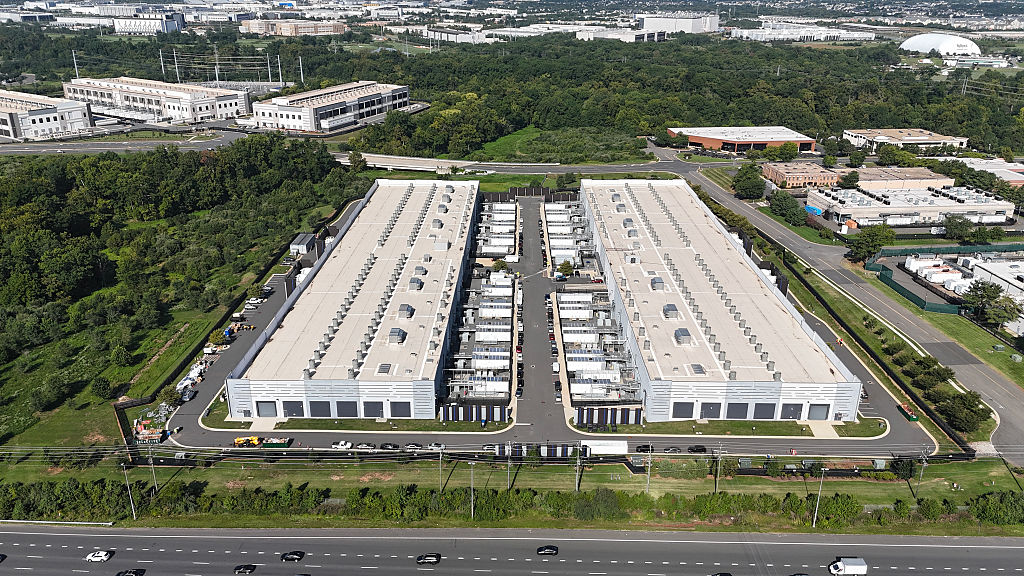
ValleyAmazon’s $1B plan to combat data center backlash draws more backlash Ars Technica AI
SiliconHow NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast NVIDIA Blog