llama.cpp releasesTools
b11530: llama: keep the backend sampling graph static across ubatches (#30223)
The reserve builds n_outputs_max_per_seq sampling chains per sampler, while a decode built one per output row, so the graph changed its topology after the reserve and GGML_SCHED_NO_REALLOC builds…
Read at llama.cpp releases ↗Related
SiliconOpenAI and Synopsys partner to build "GPT-Synopsys" for autonomous chip design Tom's Hardware AI
ValleyAmazon’s $1B plan to combat data center backlash draws more backlash Ars Technica AI
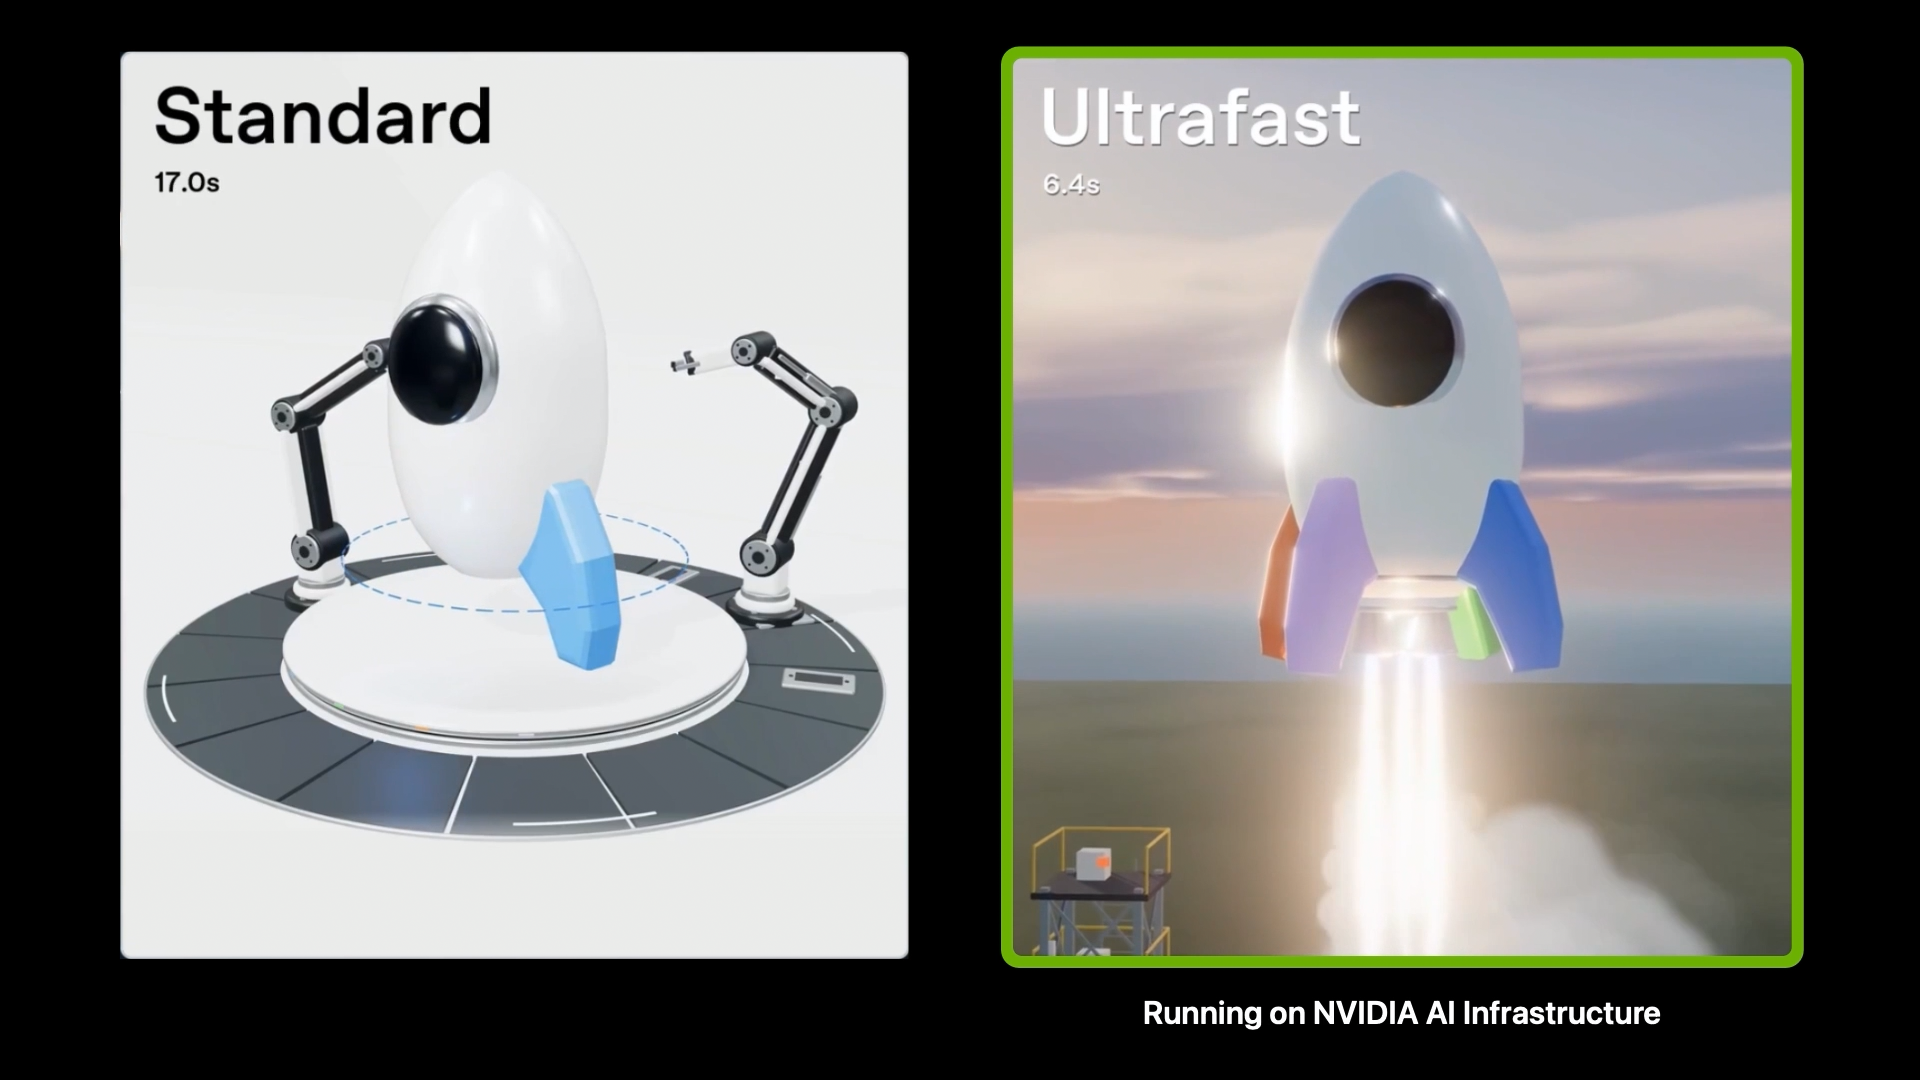
SiliconHow NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast NVIDIA Blog
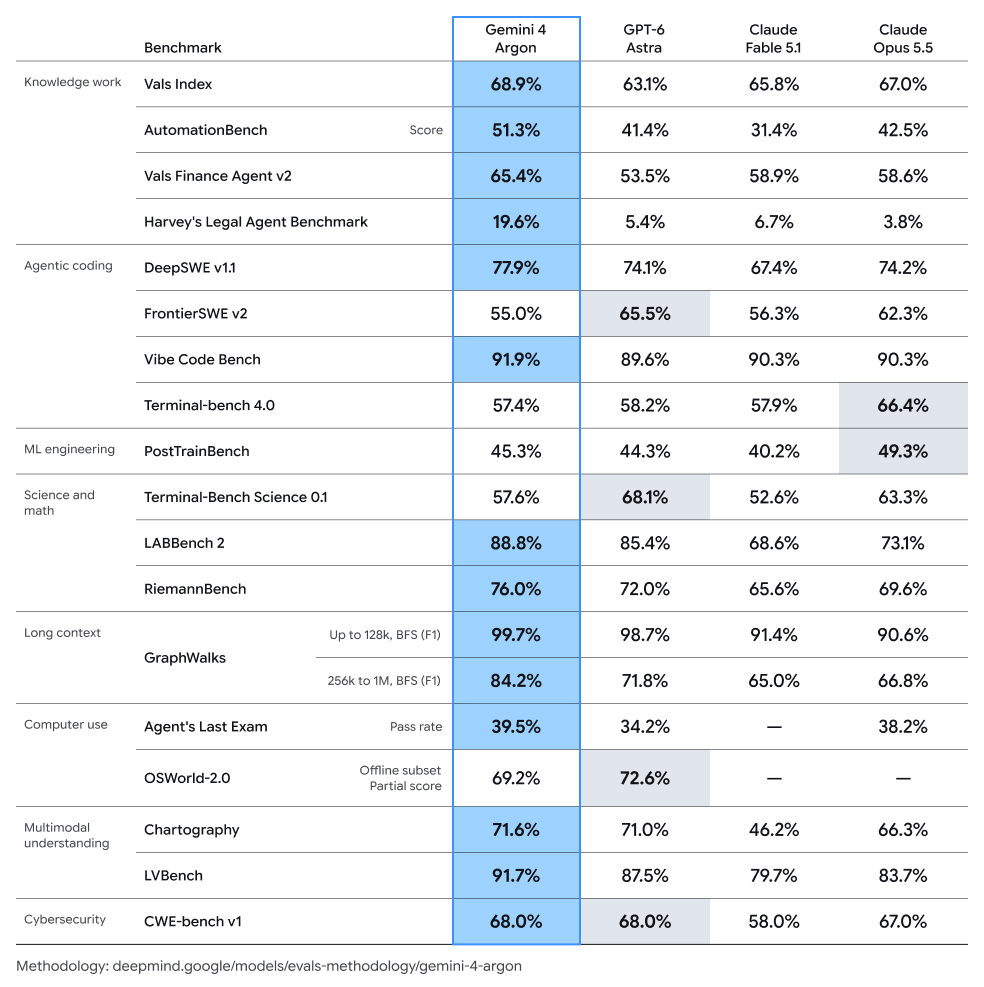
Voices[AINews] Gemini 4 Argon: GDM’s answer to Astra/Fable, with 1M output Latent Space
LabsIntroducing GPT-6.1 Sol OpenAI News