llama.cpp releasesTools
b11567: llama : report compute graph reallocations during inference (#30329)
Add an optional ggml_backend_sched_realloc_callback that user code registers with ggml_backend_sched_set_realloc_callback to be notified when the buffers reserved for a graph are not sufficient and…
Read at llama.cpp releases ↗Related
AsiaSequoia-backed chip startup Nuvacore seeks $2.5b valuation Tech in Asia
SiliconOpenAI and Synopsys partner to build "GPT-Synopsys" for autonomous chip design Tom's Hardware AI
ValleyAmazon’s $1B plan to combat data center backlash draws more backlash Ars Technica AI
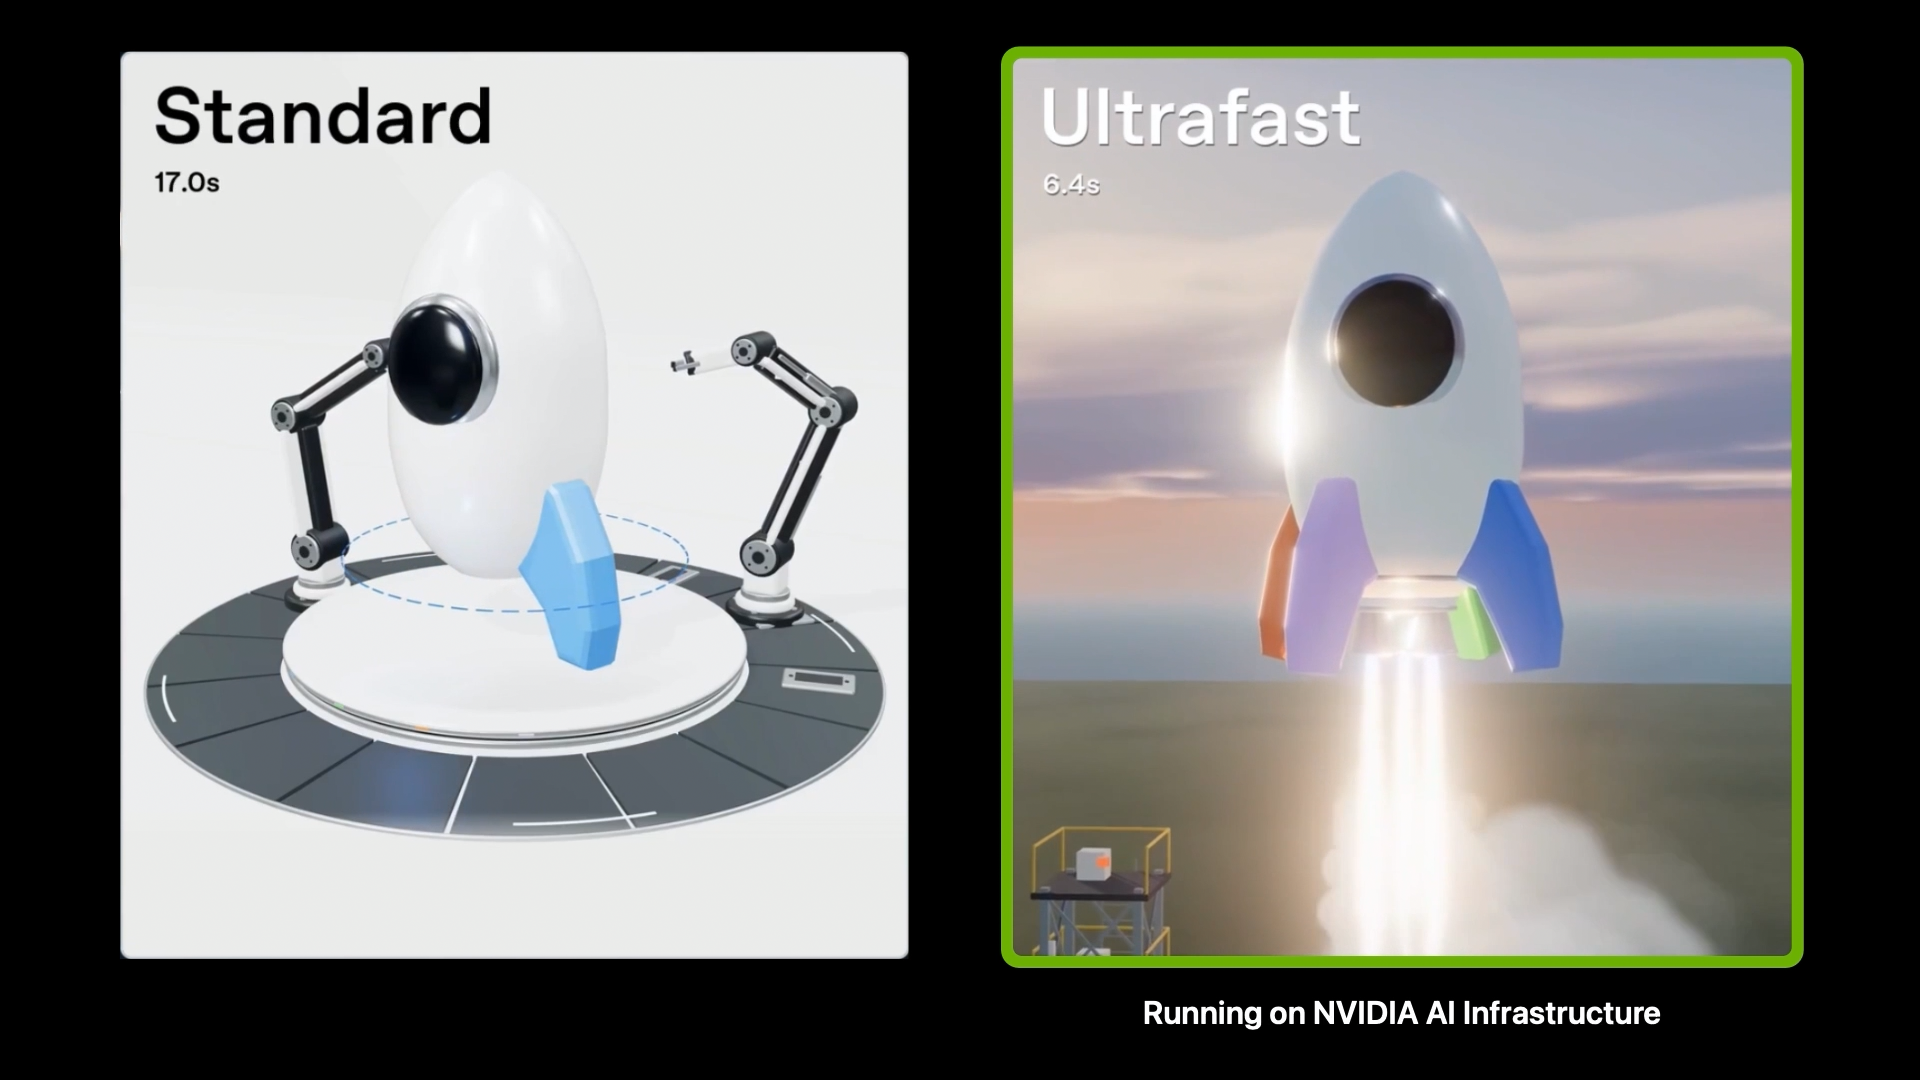
SiliconHow NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast NVIDIA Blog
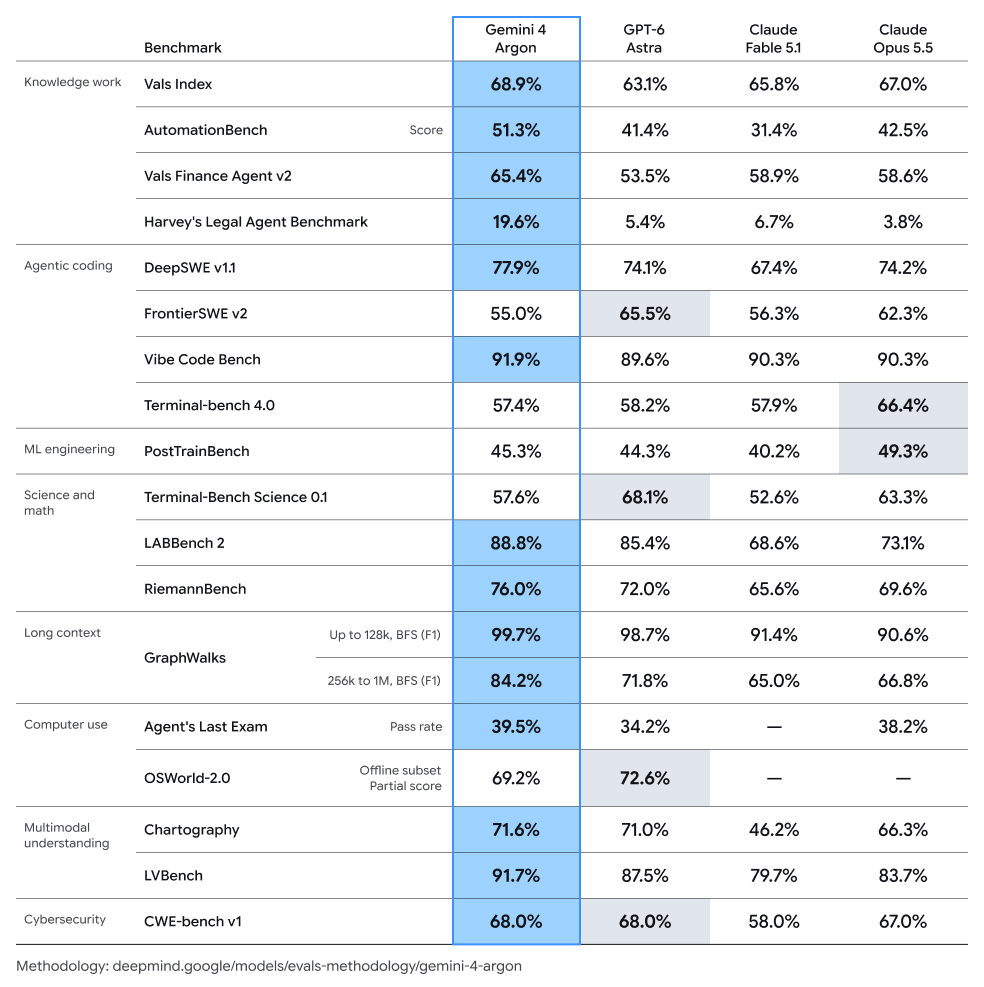
Voices[AINews] Gemini 4 Argon: GDM’s answer to Astra/Fable, with 1M output Latent Space