llama.cpp releasesTools
b11623
cuda : use SIMT implicit GEMM conv2d on AMD without WMMA ( #30325 ) cuda : use SIMT implicit GEMM conv2d on AMD without WMMA Assisted-by: Claude Opus cuda : update conv2d SIMT comment cuda : skip…
Read at llama.cpp releases ↗Related
AsiaChina chip exports jump 136% to US$45b as AI frenzy jacks up prices SCMP Tech

GitHubGemini 4 Argon debuts with a unified 1M input/output token limit The New Stack
SiliconOpenAI and Synopsys partner to build "GPT-Synopsys" for autonomous chip design Tom's Hardware AI
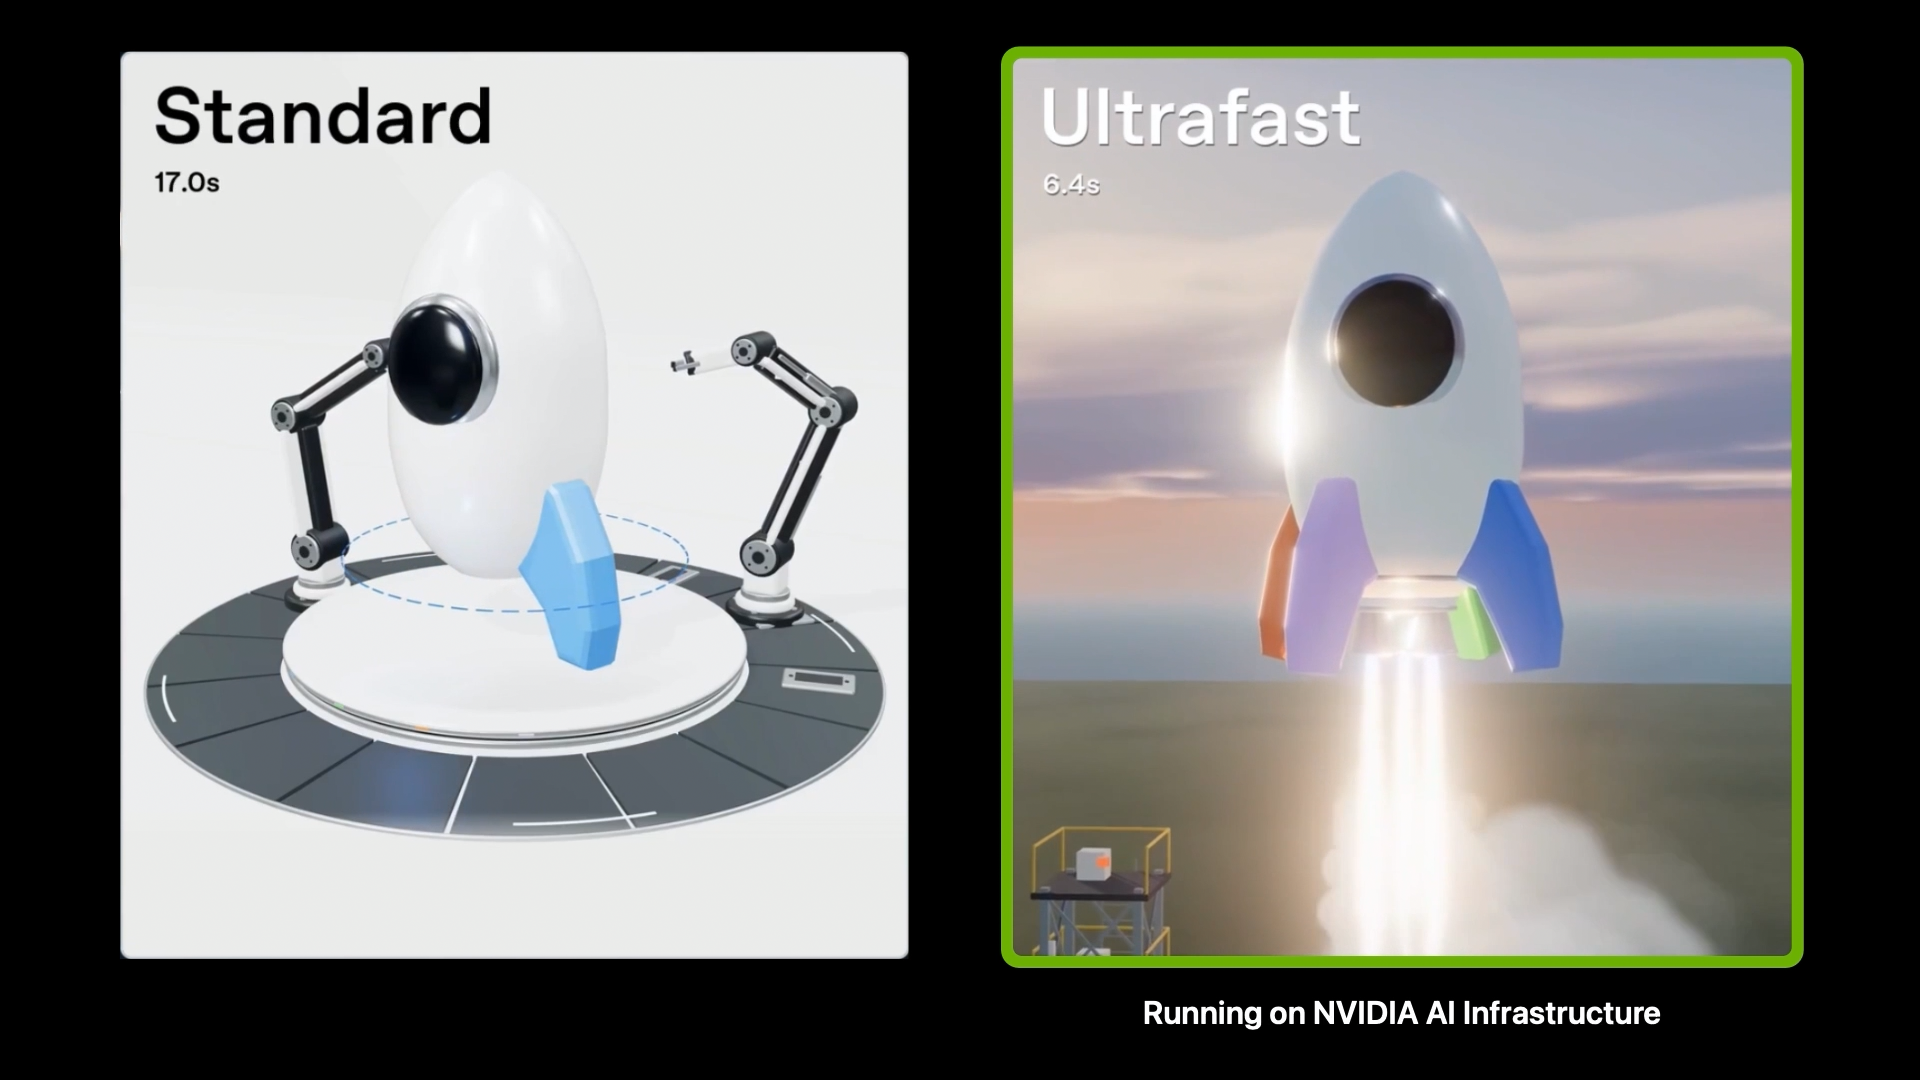
SiliconHow NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast NVIDIA Blog

ToolsNvidia reportedly agrees to purchase Hugging Face for $13B Weights & Biases