NVIDIA Technical BlogSilicon
Benchmarking LLM Inference at Scale with AIPerf

You’re deploying a model on a system. It starts up, prompts are getting responses. Now the hard question: Is this fast? Your instincts might lead you to send... You’re deploying a model on a system.
Agents & vibe codingResearchAgentic AI / Generative AIDeveloper Tools & TechniquesAI AgentAI Inference
Read at NVIDIA Technical Blog ↗Related

SiliconTensorRT Edge-LLM Completes the MLPerf Edge Agentic Benchmark 6.4x Faster on Jetson AGX Thor NVIDIA Technical Blog

SiliconFrontier Reasoning Reaches the Edge: How to Deploy and Optimize Models on NVIDIA Jetson NVIDIA Technical Blog
VoicesNoam Brown – Agent swarms, alignment, & recursive self-improvement Dwarkesh Podcast
LabsImproving HCLS AI reasoning with open-source agent skills AWS Machine Learning
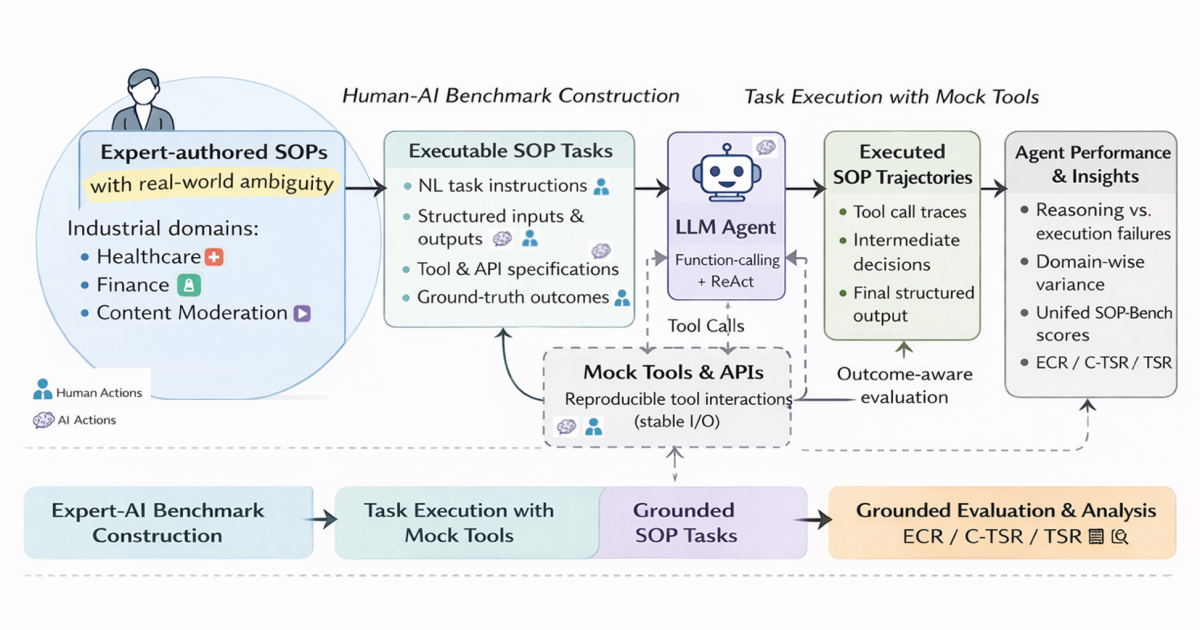
ResearchSOP-Bench: A new benchmark for evaluating AI agents on real business procedures Amazon Science