AWS Machine LearningLabs
Beyond the KV cache: Training and serving i14’s Laplace 3B linear attention model on AWS Trainium2 with native PyTorch
Most large language models (LLMs) use transformer architectures with softmax attention. During inference, their key-value (KV) cache grows with the conversation or document context.
Read at AWS Machine Learning ↗Related
LabsFine-tuning GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod AWS Machine Learning

SiliconNVIDIA Nemotron 3.5 Super VL Powers Specialized Agents with Multimodal Reasoning NVIDIA Technical Blog
Voices[AINews] AI Engineer NYC: Gemini 4 Argon, Vals AI Benchmarks Latent Space
LabsGemini 4 Argon for Robotics Google DeepMind
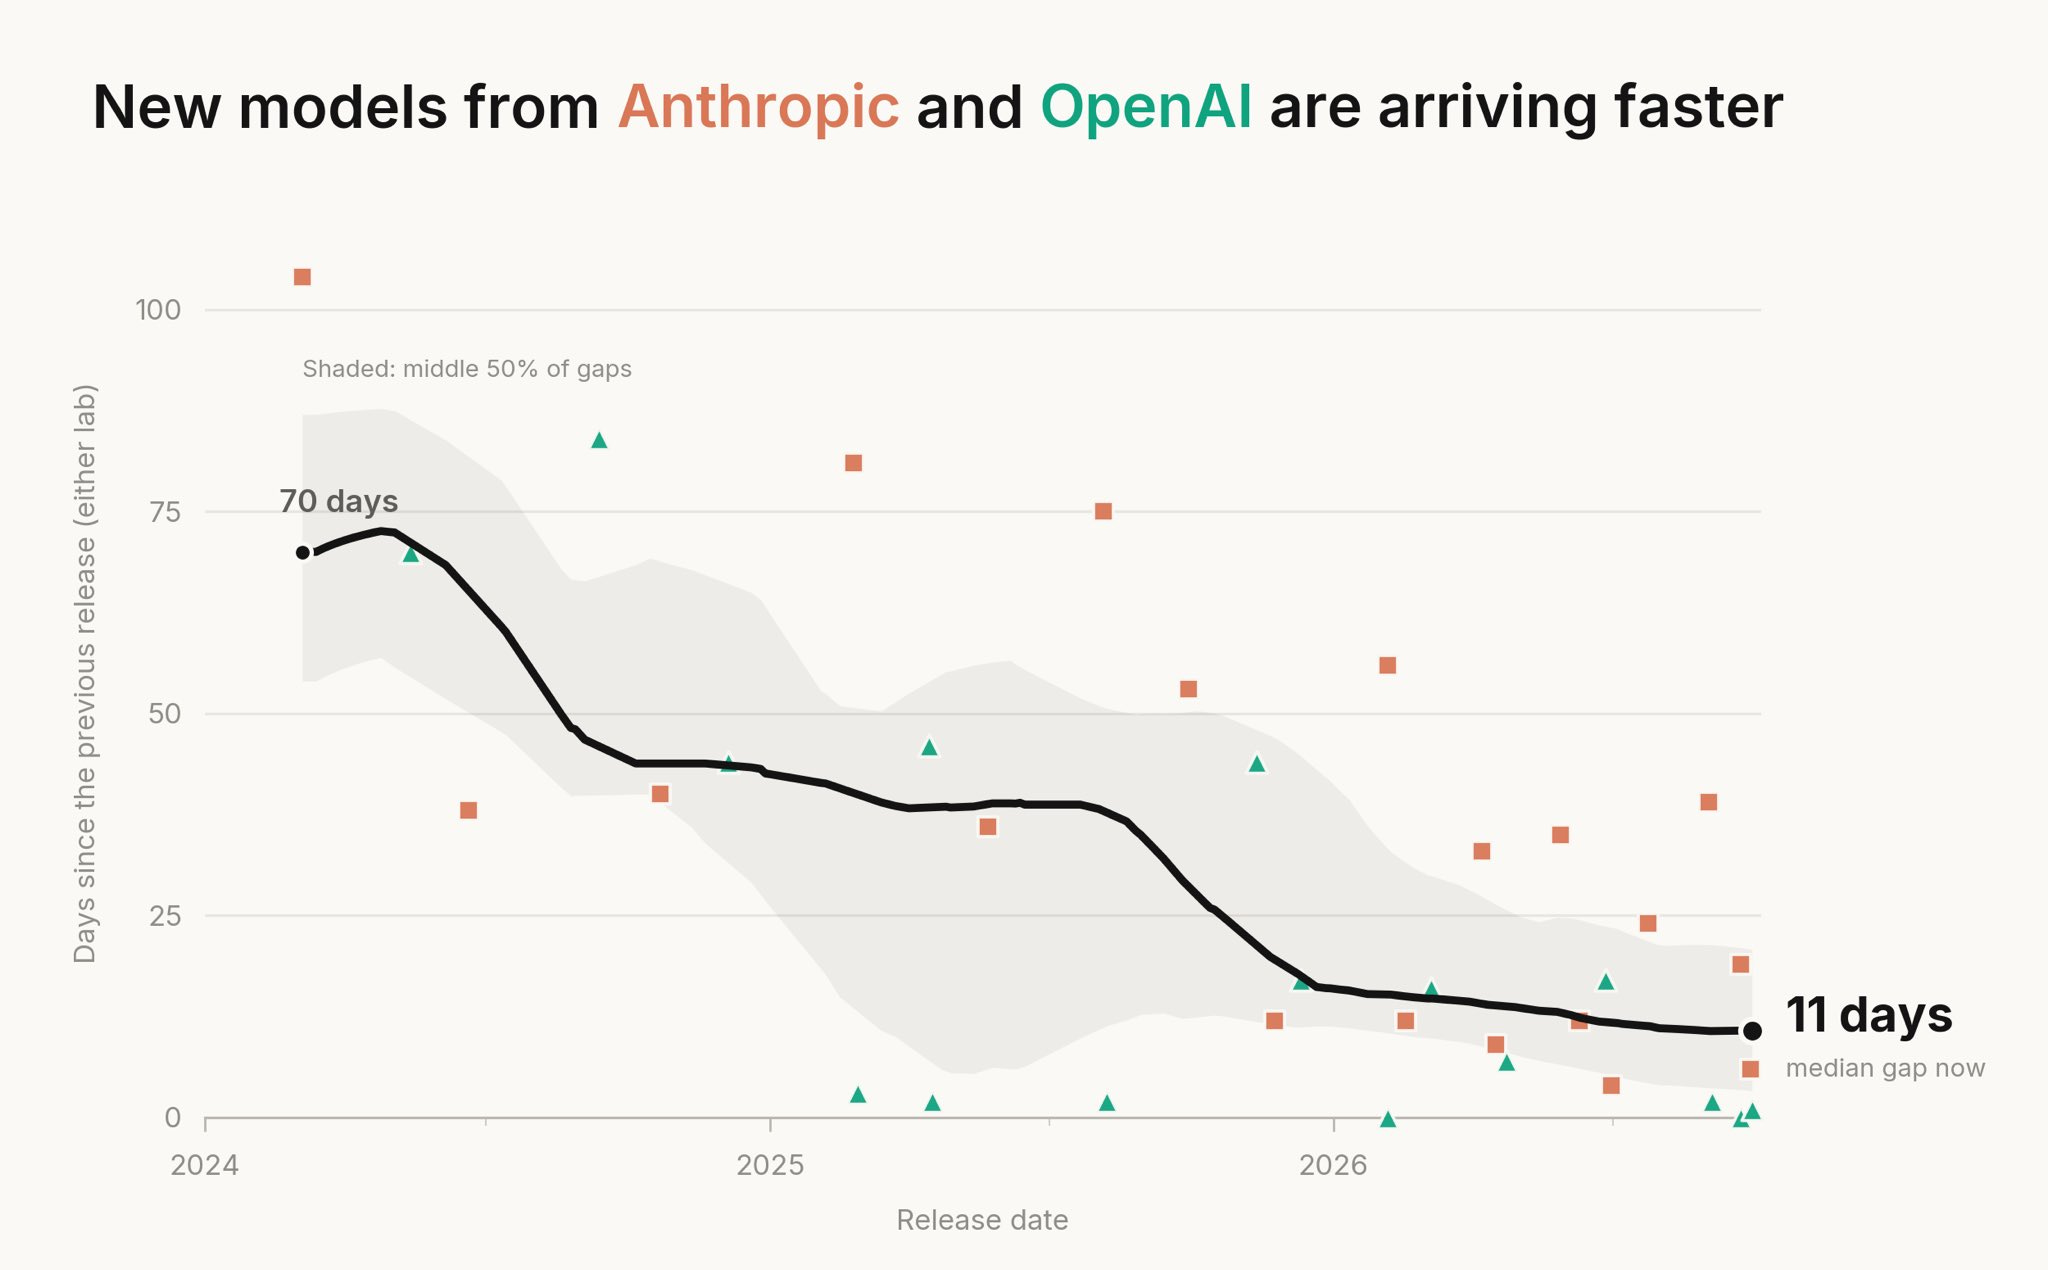
VoicesLast Week in AI #345 - 5 new models, 9 misalignment incidents, some Dots Last Week in AI