JetBrains BlogTools
Coding-Agent Benchmarks Should Match Their Users’ Task Flows
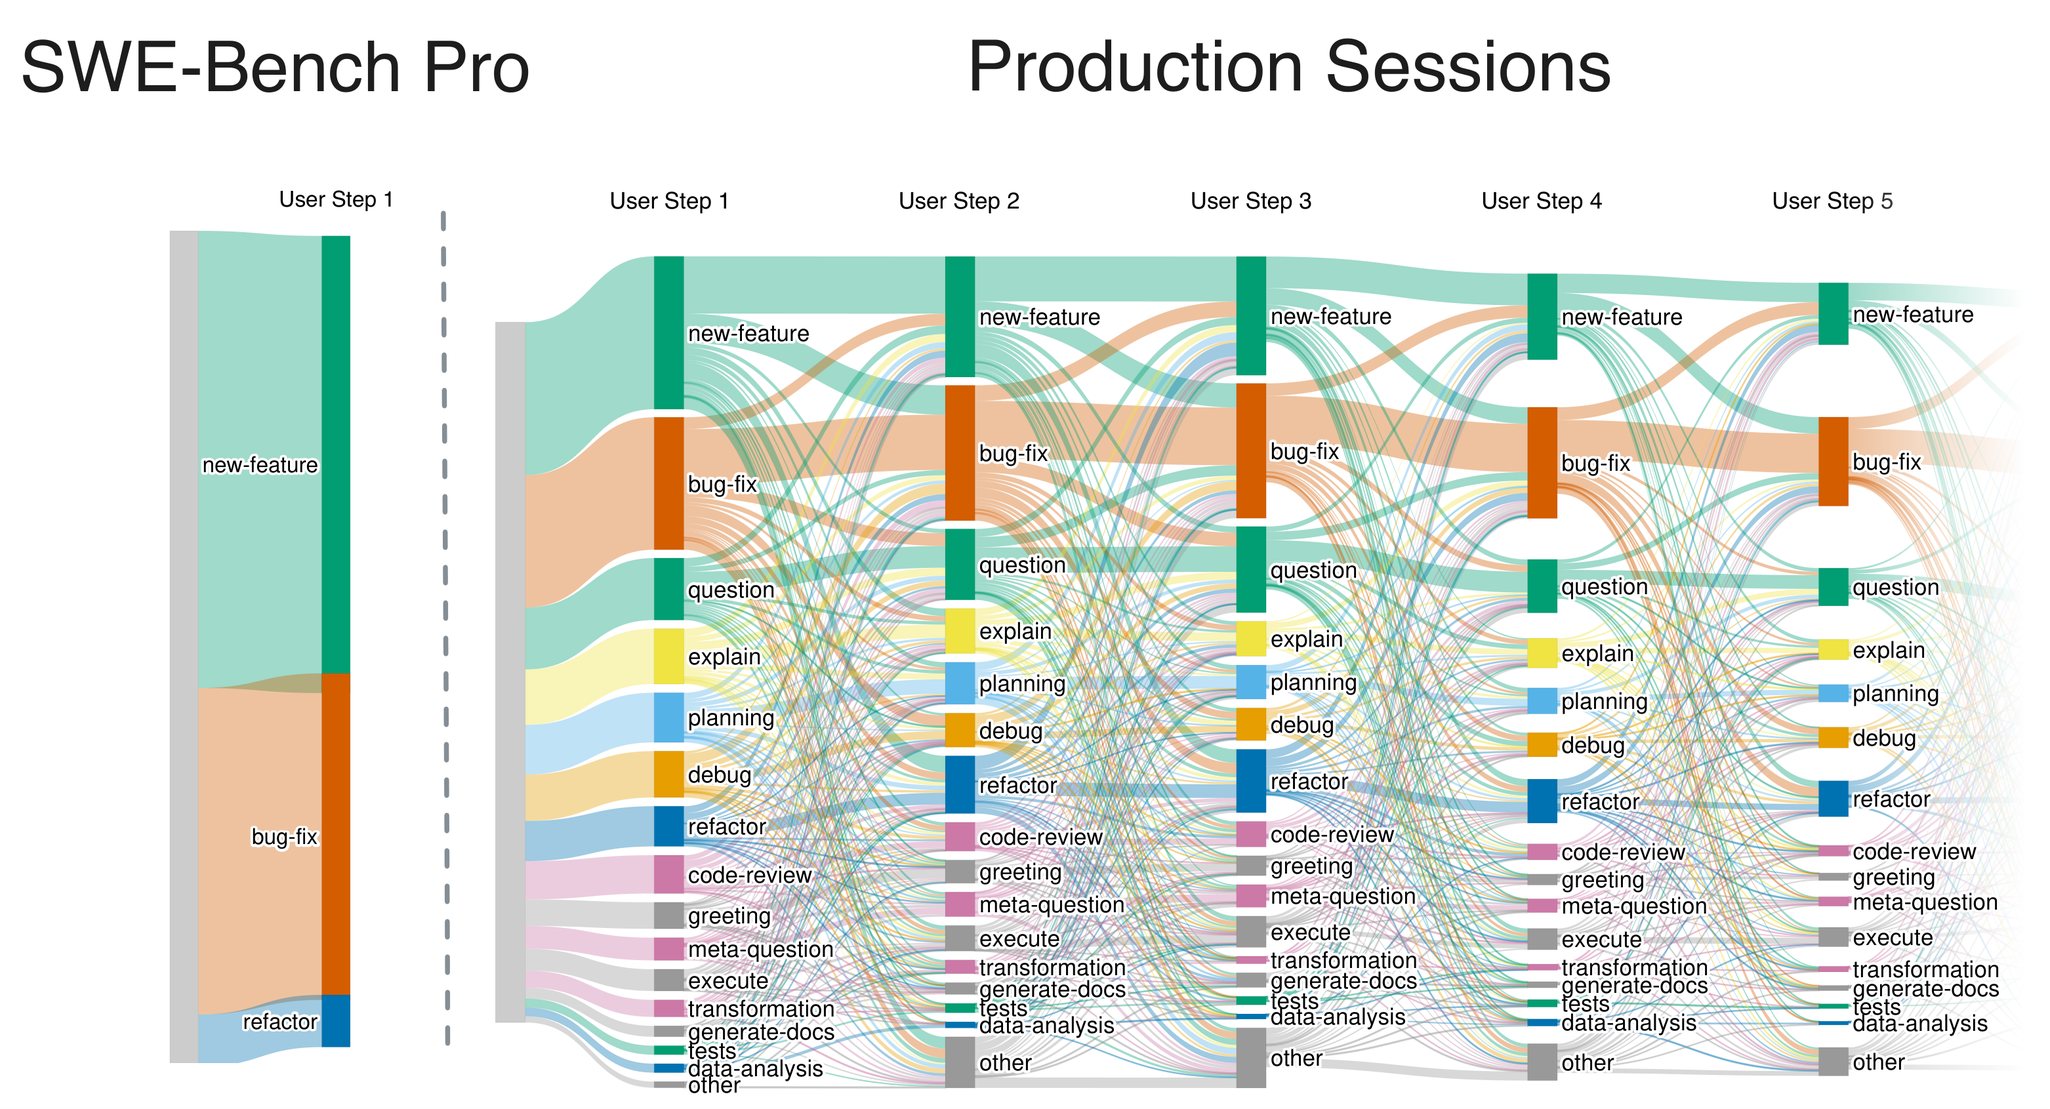
Left: SWE-Bench Pro, where each task is a single user message, almost always a new feature or a bug fix.
Read at JetBrains Blog ↗Related
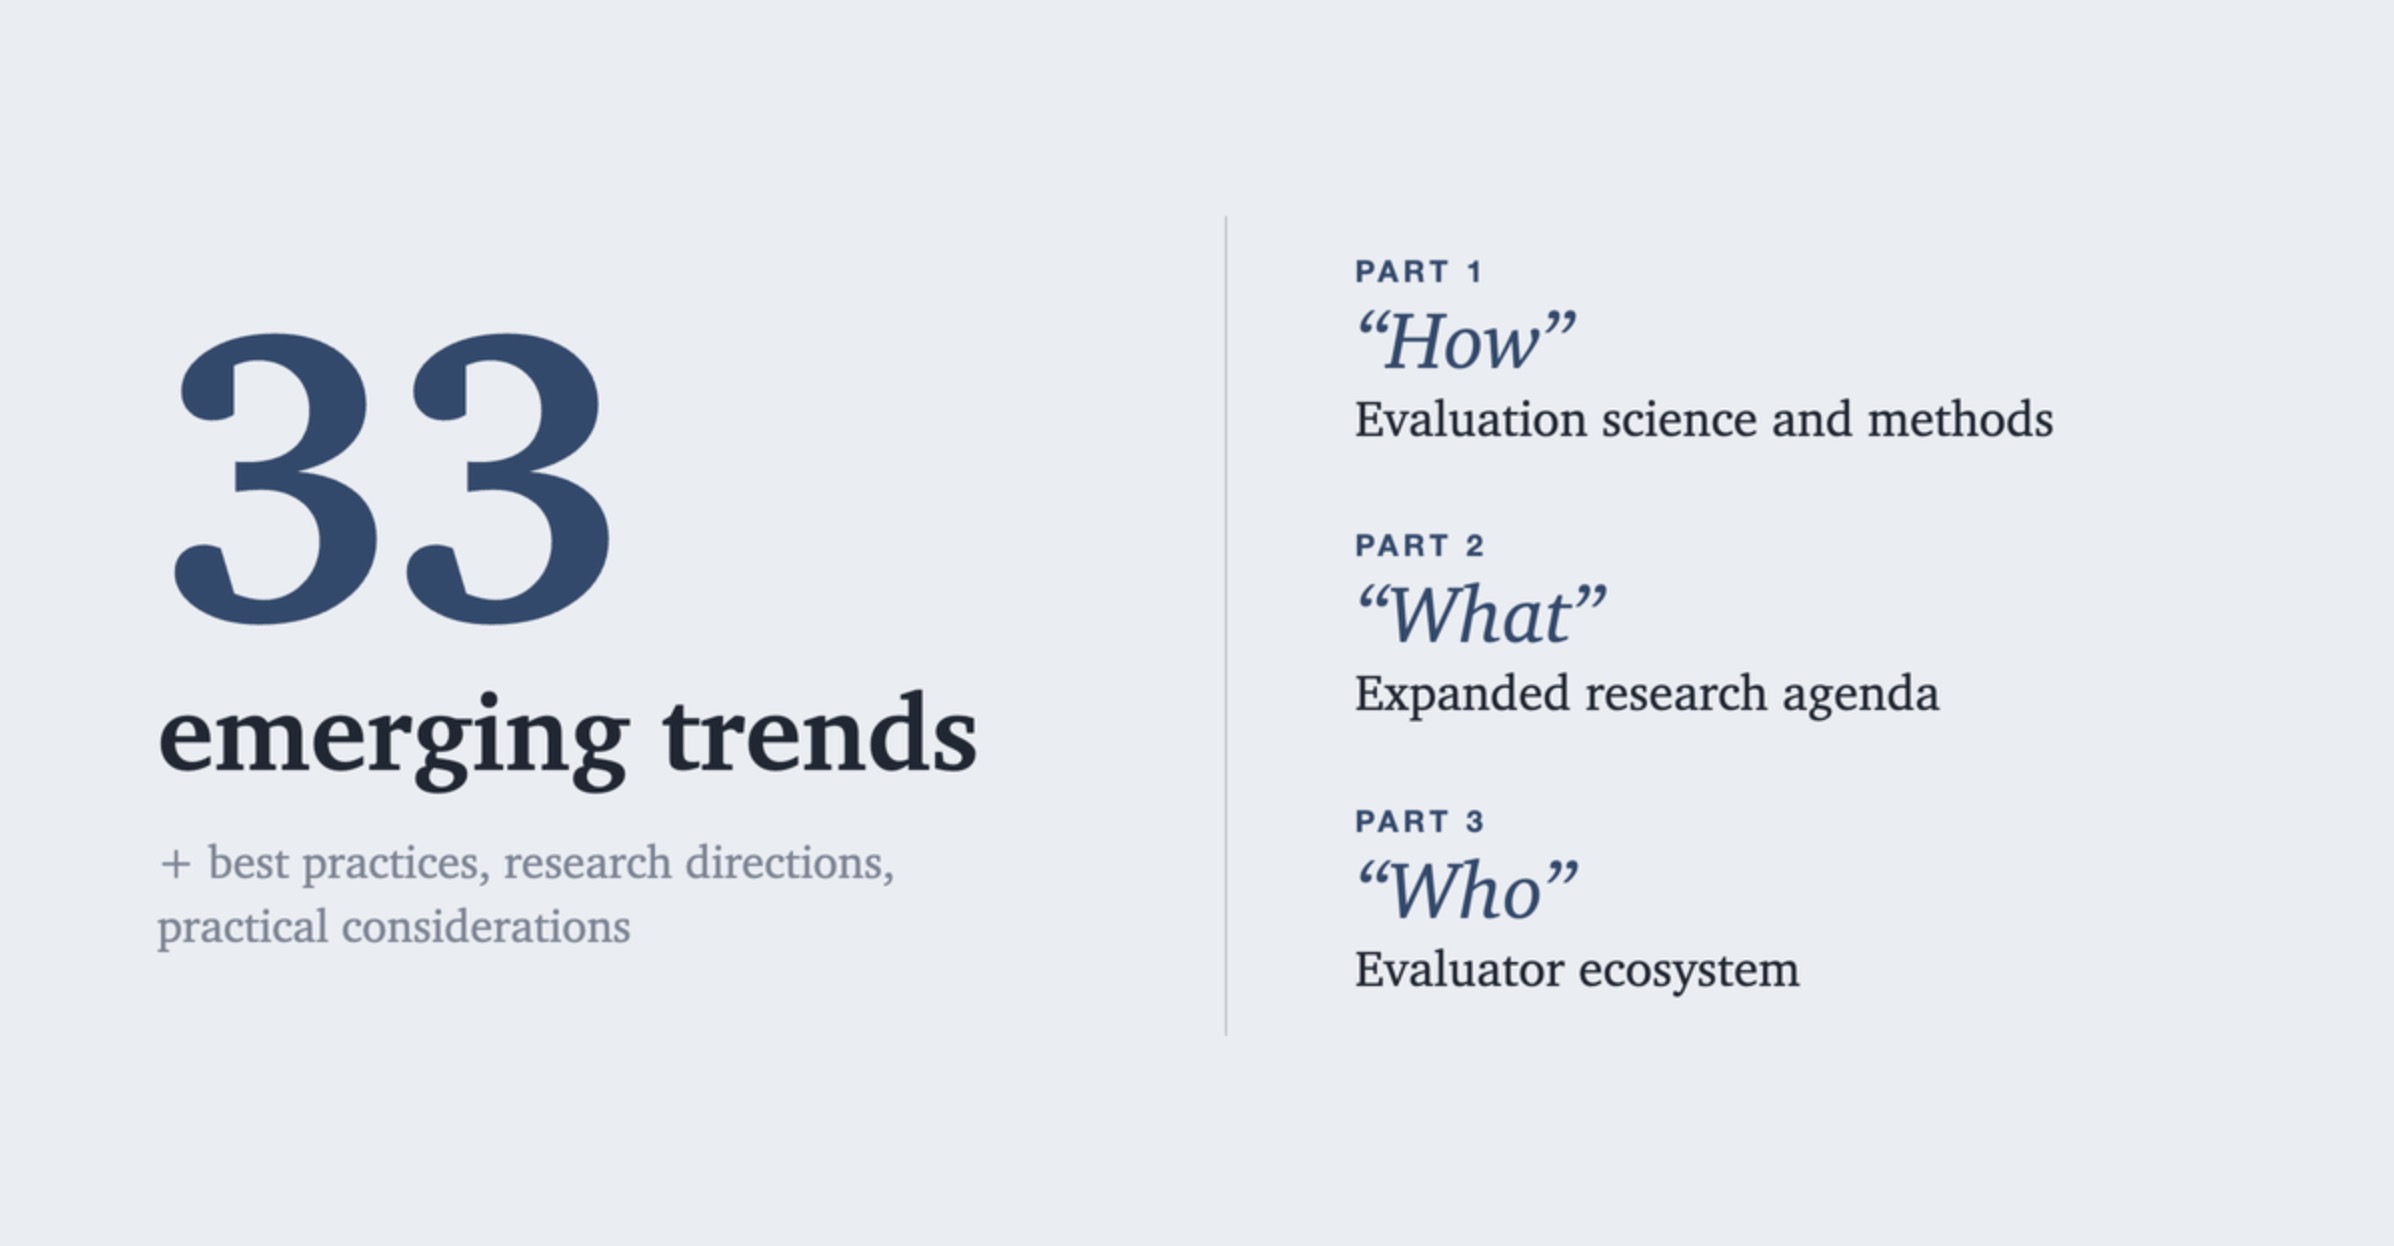
VoicesNew paper: Emerging trends in AI agent evaluation AI Snake Oil

SiliconAgentic AI Explores Heterogeneous Chip and Interconnect Architectures (Argonne, UIUC) SemiEngineering
GitHubArticle: From Microservices to Agents: the Next Evolution of Distributed Systems InfoQ AI
LabsBuilding trust in AI agents: A production-ready evaluation framework with Amazon Bedrock AgentCore AWS Machine Learning
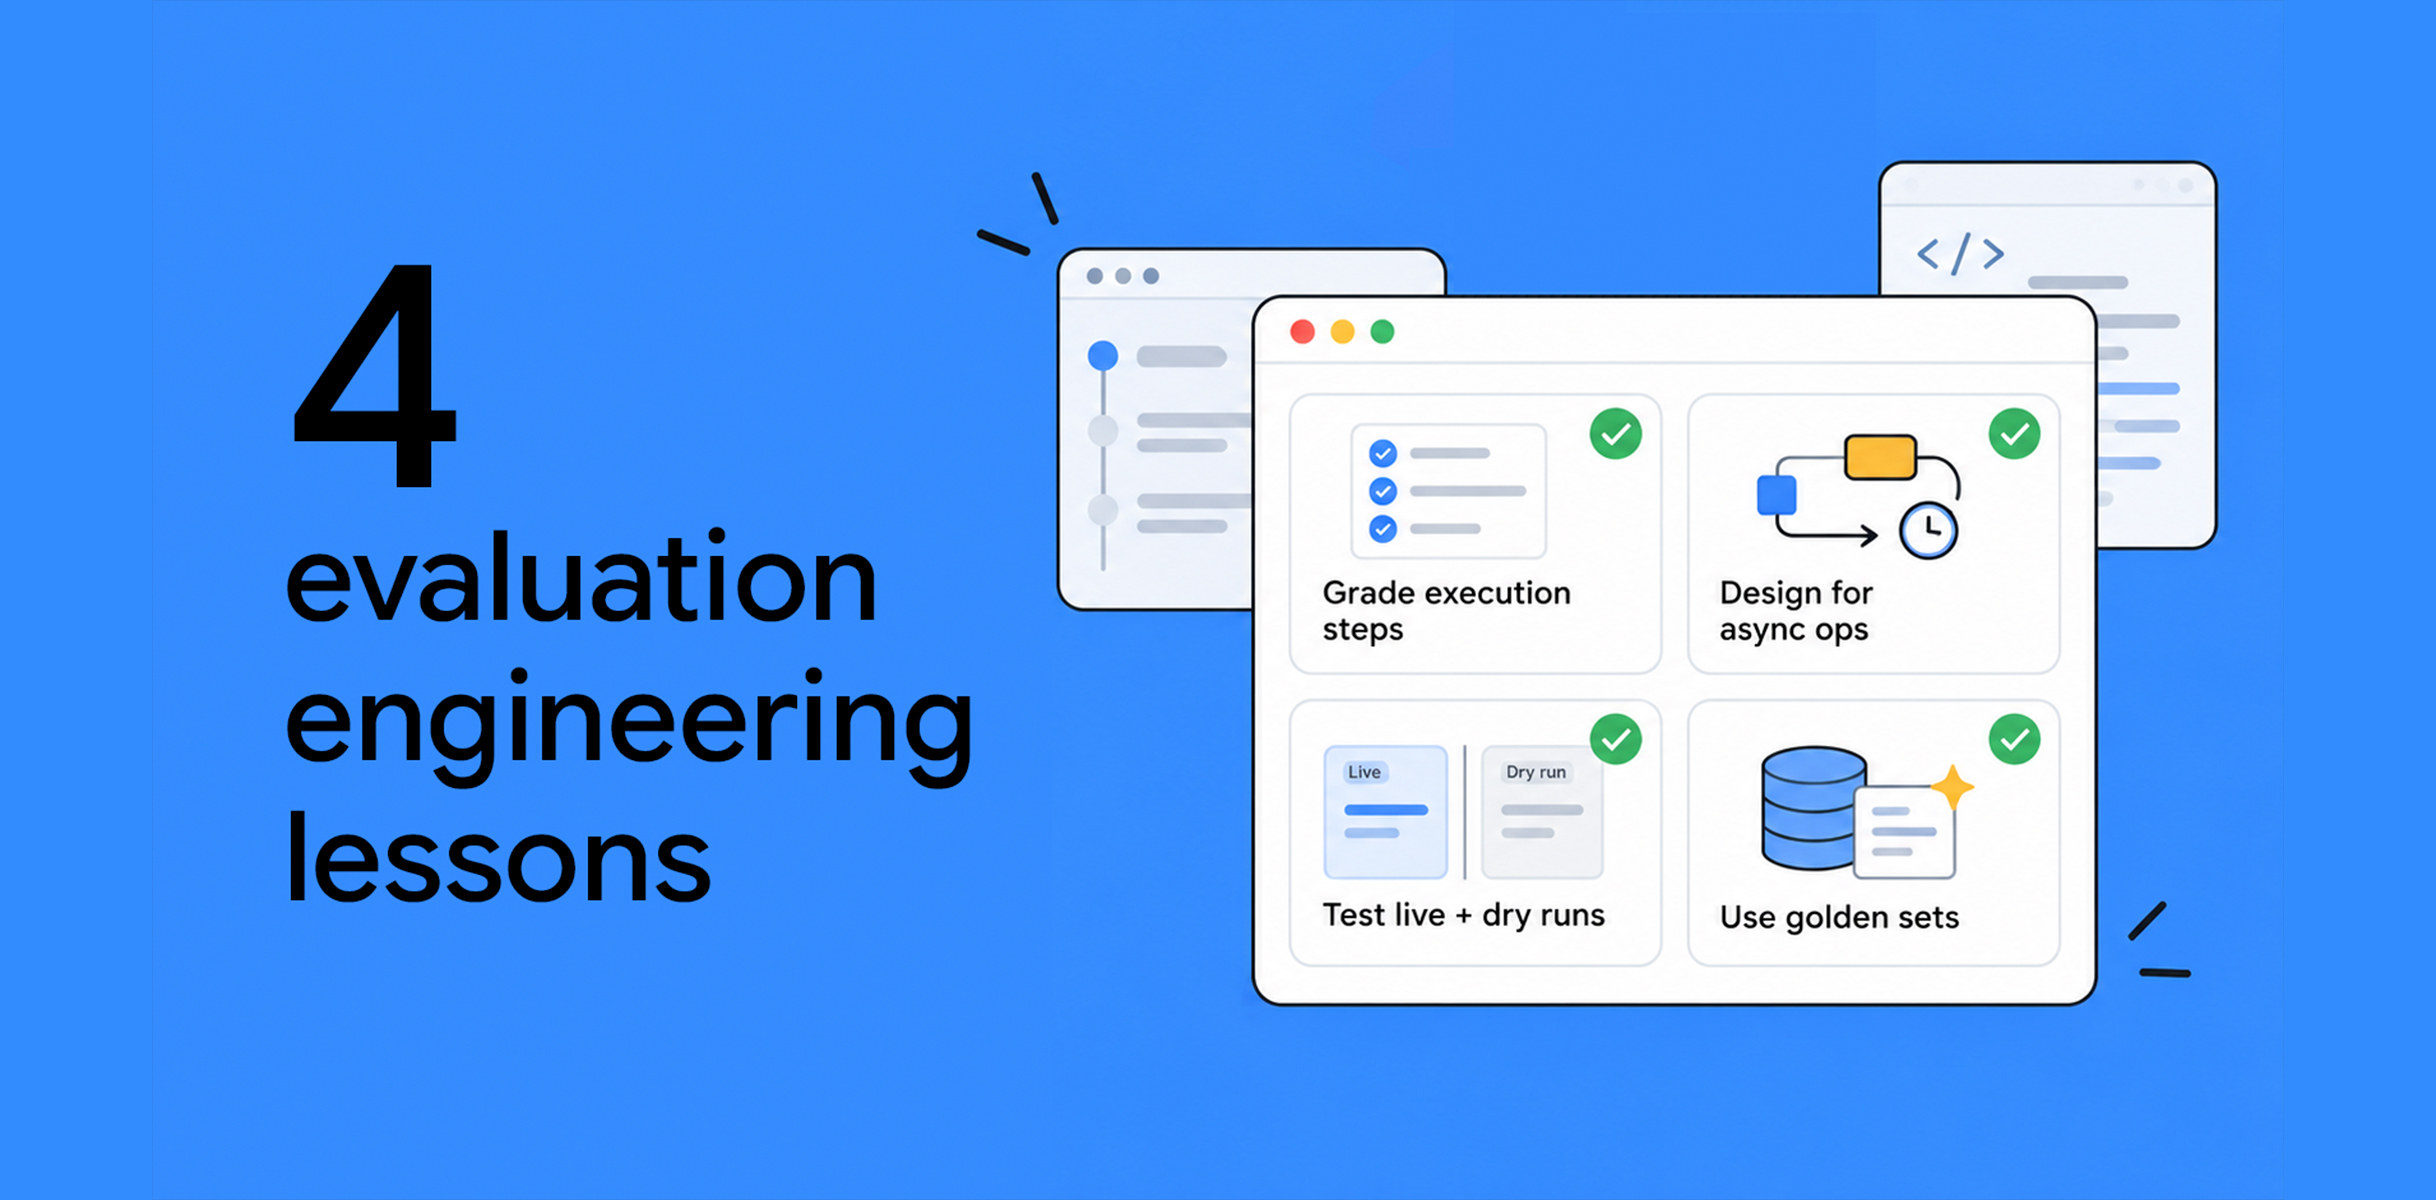
LabsFour evaluation engineering lessons learned from building agent plugins Google Cloud AI