vLLM BlogTools
DeepSeek-V4.1-Flash on Vera Rubin NVL72: 58x Throughput vs. GB300 NVL72 at 387 tokens/s
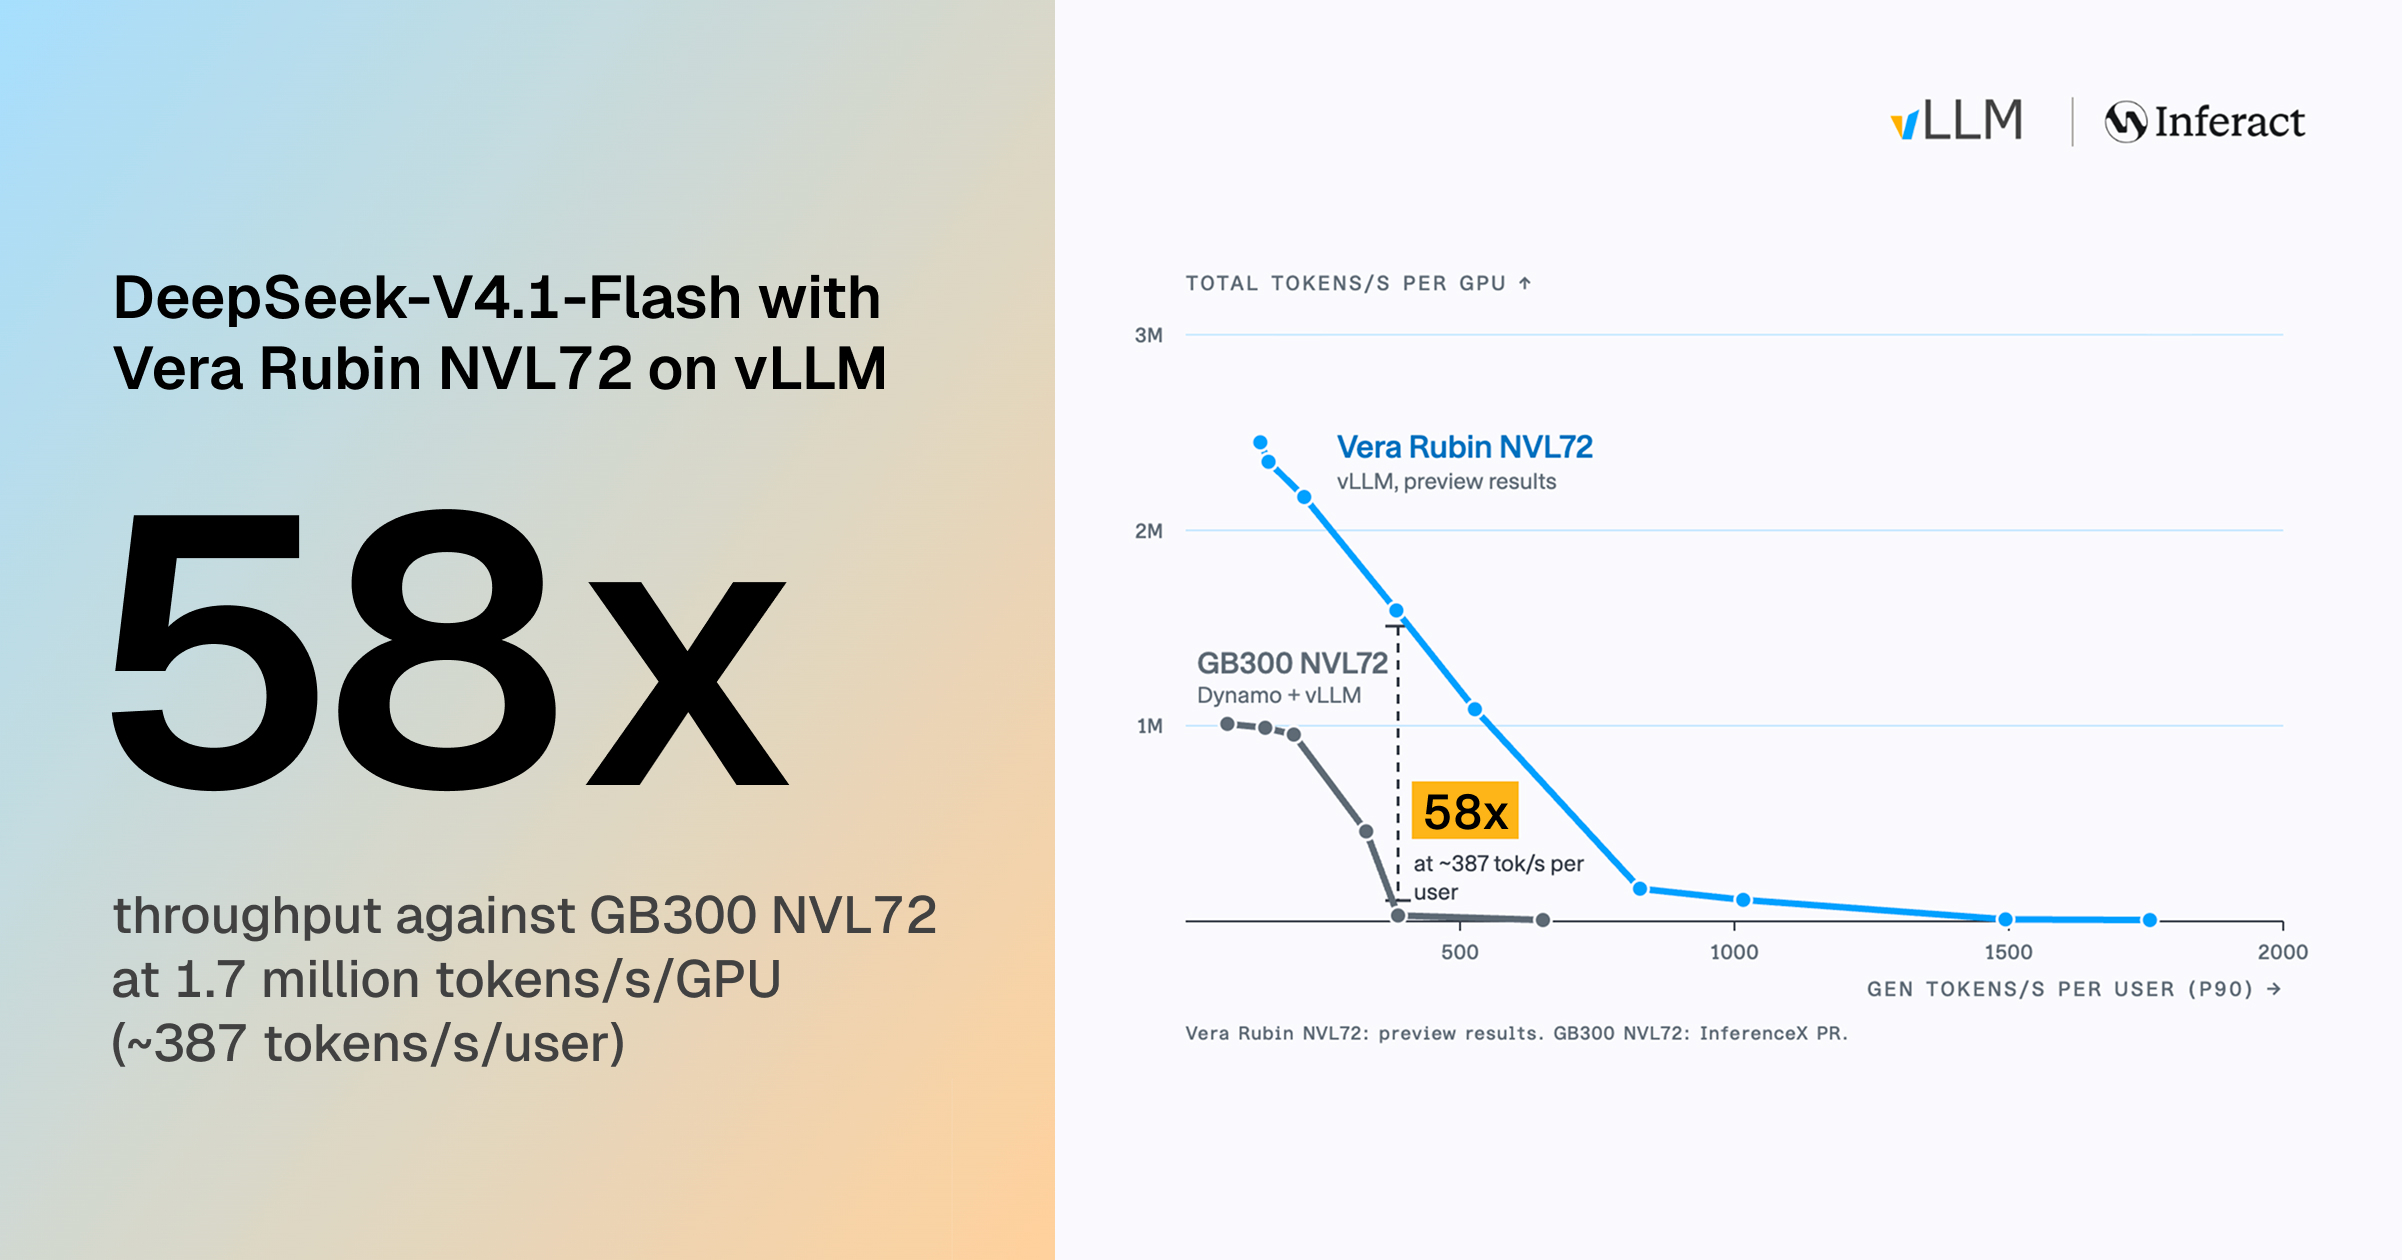
On one NVIDIA Vera Rubin NVL72 rack, vLLM serves DeepSeek-V4.1-Flash on SemiAnalysis AgentX at 1.7M tokens/s per GPU at a P90 of 387 tokens/s per user, 58x GB300 NVL72 at the same interactivity.
Read at vLLM Blog ↗Related
ToolsDay 0 support for Mistral Large 4 on vLLM vLLM Blog
ToolsDay 0 support for Muse Spark Open on vLLM vLLM Blog
ValleyTaiwan’s chipmaking giant TSMC to invest $1B in Anthropic, OpenAI Ars Technica AI

SiliconRunning AV Reasoning Models Within Onboard Compute and Latency Limits NVIDIA Technical Blog
Asia🗞️Apple AI Taps Qwen, Tencent’s Hy4, and China’s AI Chip Squeeze Recode China AI