Apple Machine Learning ResearchResearch
Evaluating the Evaluators: Investigating LLM Judges for Personalized Writing Style Assessment
This paper was accepted at the Can We Trust AI Evaluation? Workshop at NeurIPS 2026. We evaluate how good large language model (LLM) judges are for personalized writing tasks.
Read at Apple Machine Learning Research ↗Related

ToolsIterating Towards LLM Reliability with Evaluation Driven Development LangChain

ResearchCan Agentic Robotics Solve Robotics’ Data-Scaling Problem? IEEE Spectrum Robotics
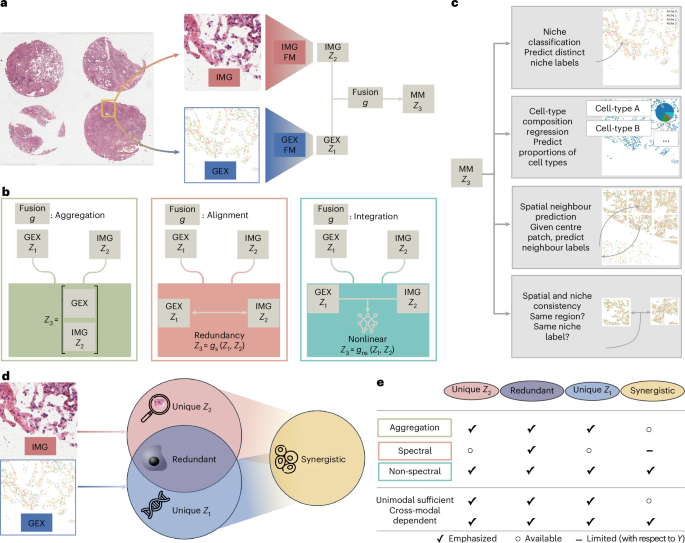
ResearchMultimodal cell foundation models require synergistic integration beyond alignment Nature Machine Intelligence
GitHubShow HN: We compressed a 31B video+audio diffusion model to 14B, 6 steps, INT8 Hacker News Show

SiliconSpeed Up Image Generation with FLUX 3 Image Klein on NVIDIA Blackwell GPUs NVIDIA Technical Blog
