Meta EngineeringLabs
Intelligent Delivery: Making Every Unit of Compute Serve Better Ads
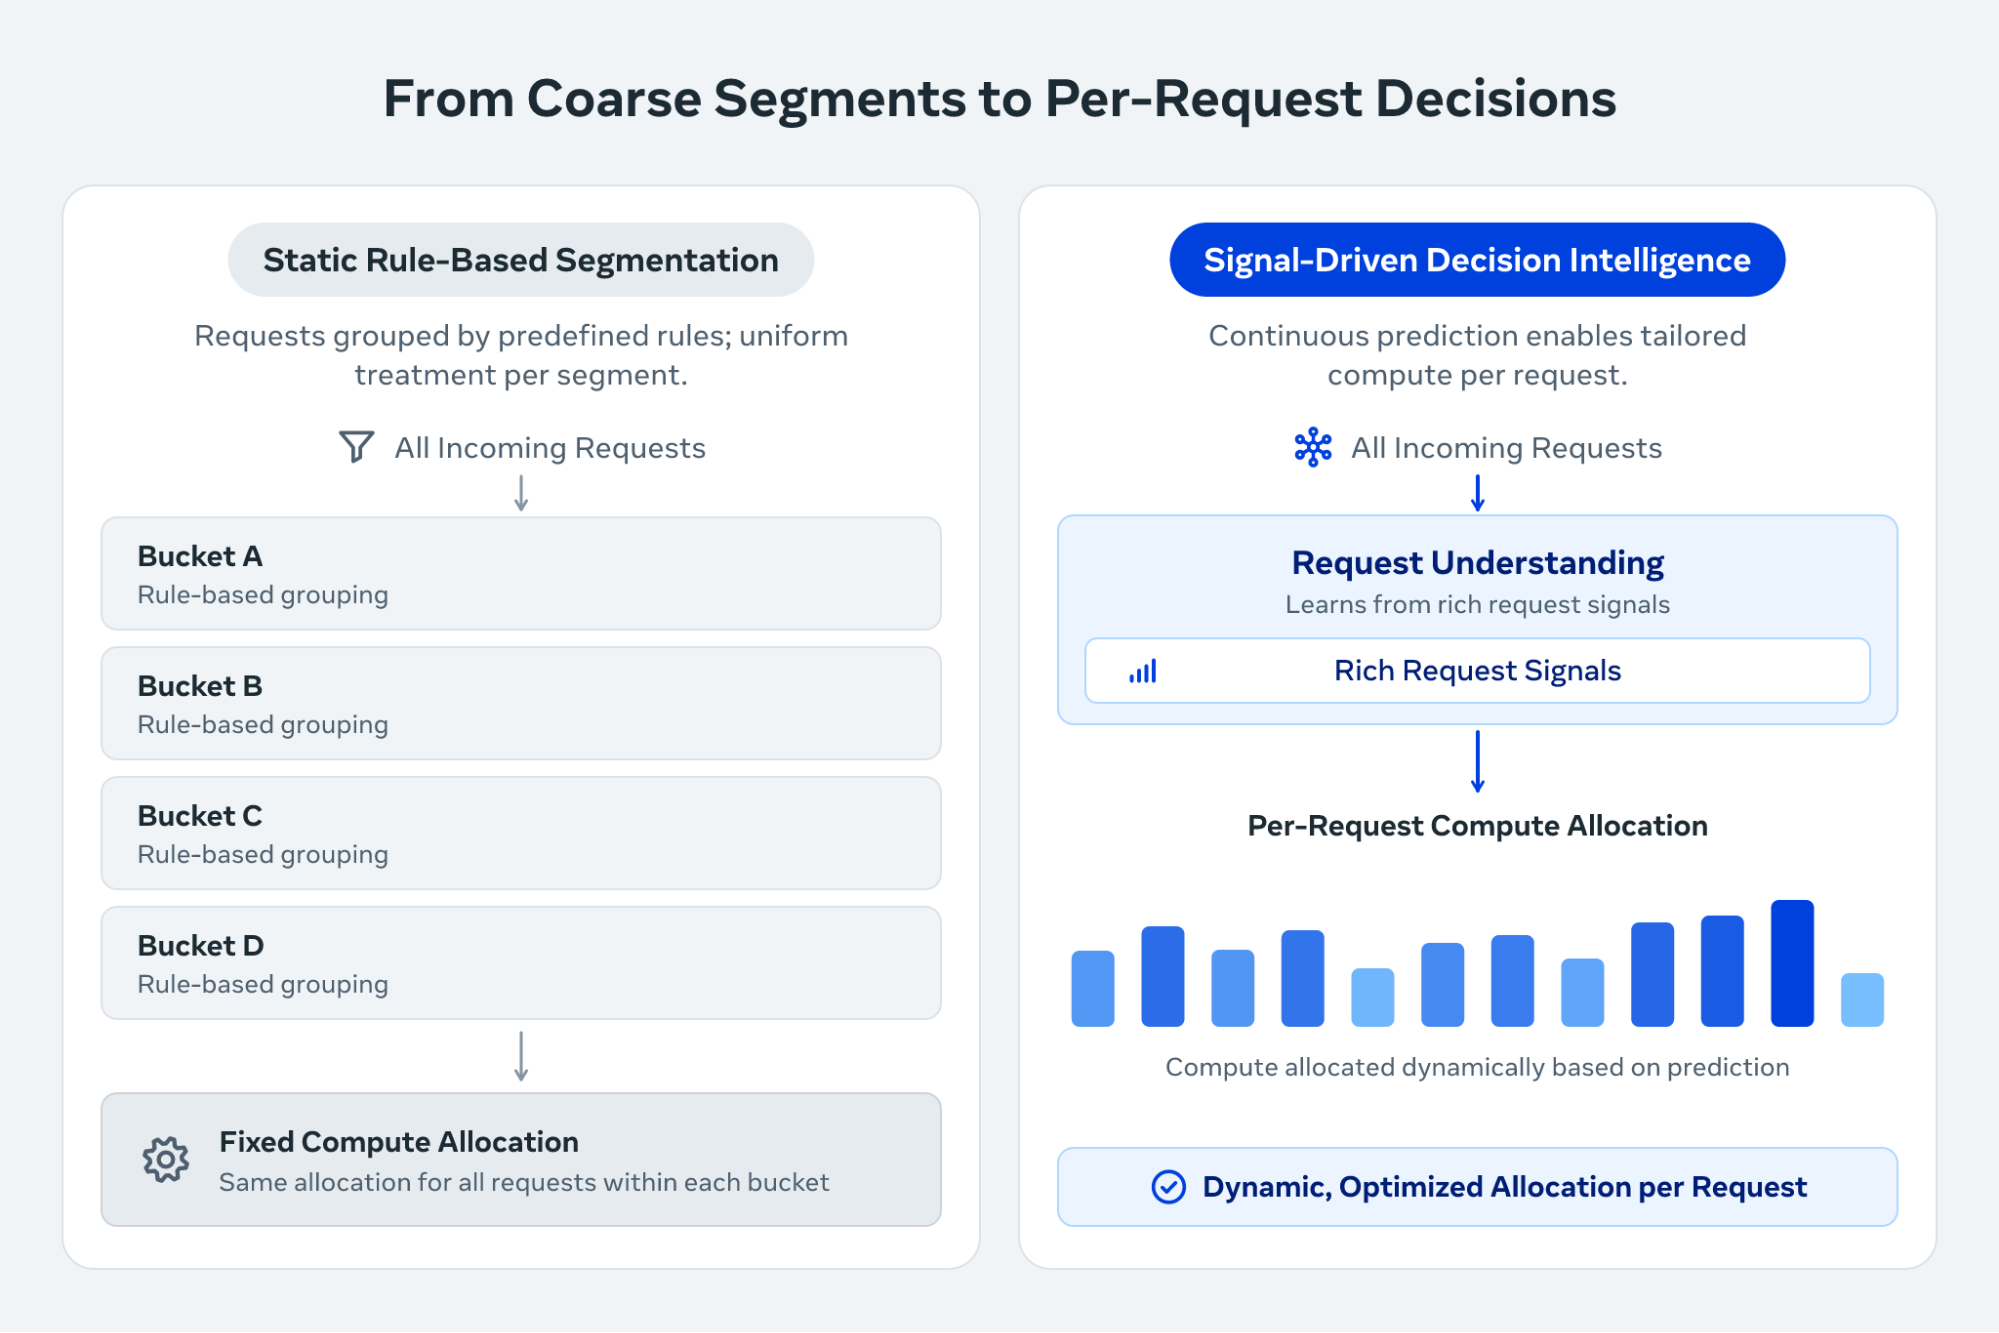
Ads ranking models are growing toward LLM scale faster than the hardware to run them can keep up. An extra unit of compute has more impact on some ad requests, models, and chips than on others.
Read at Meta Engineering ↗Related
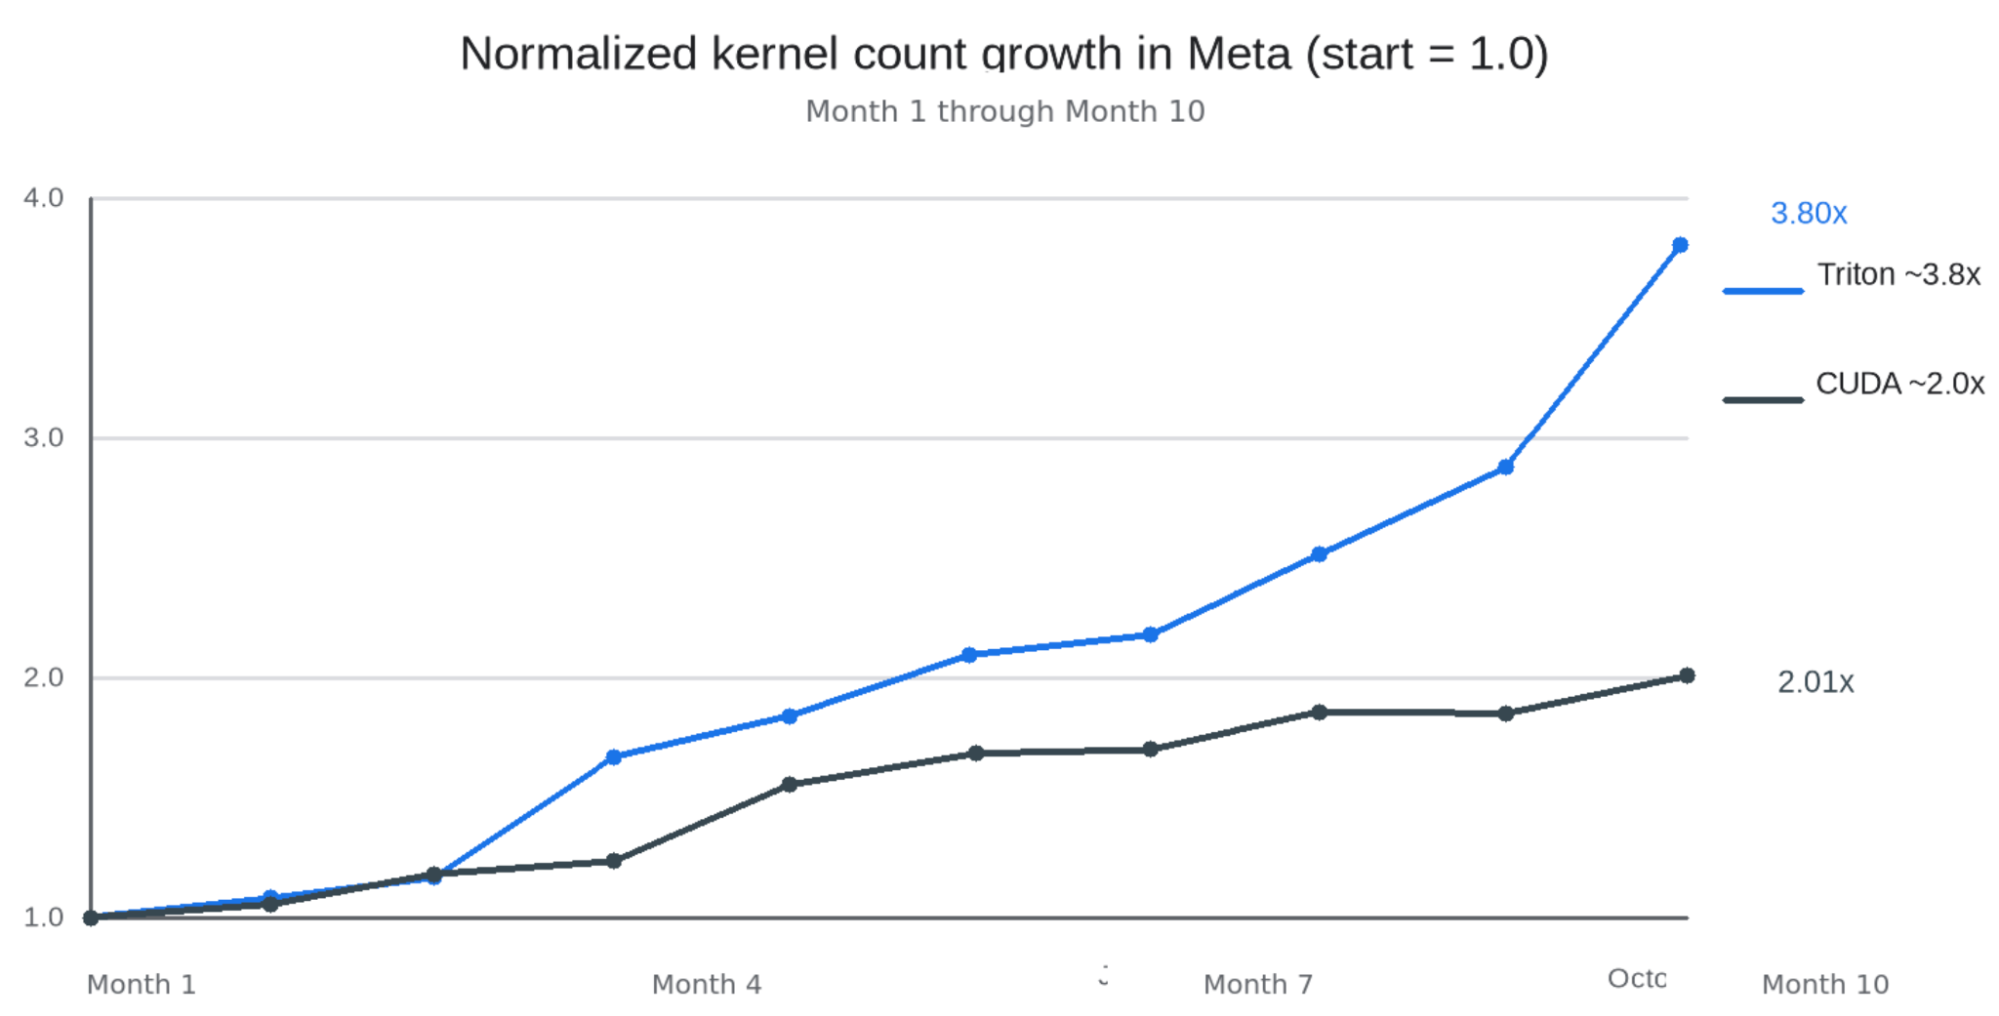
LabsHow We Built TLX: A Hardware-Native GPU Compiler for Production ML at Scale Meta Engineering
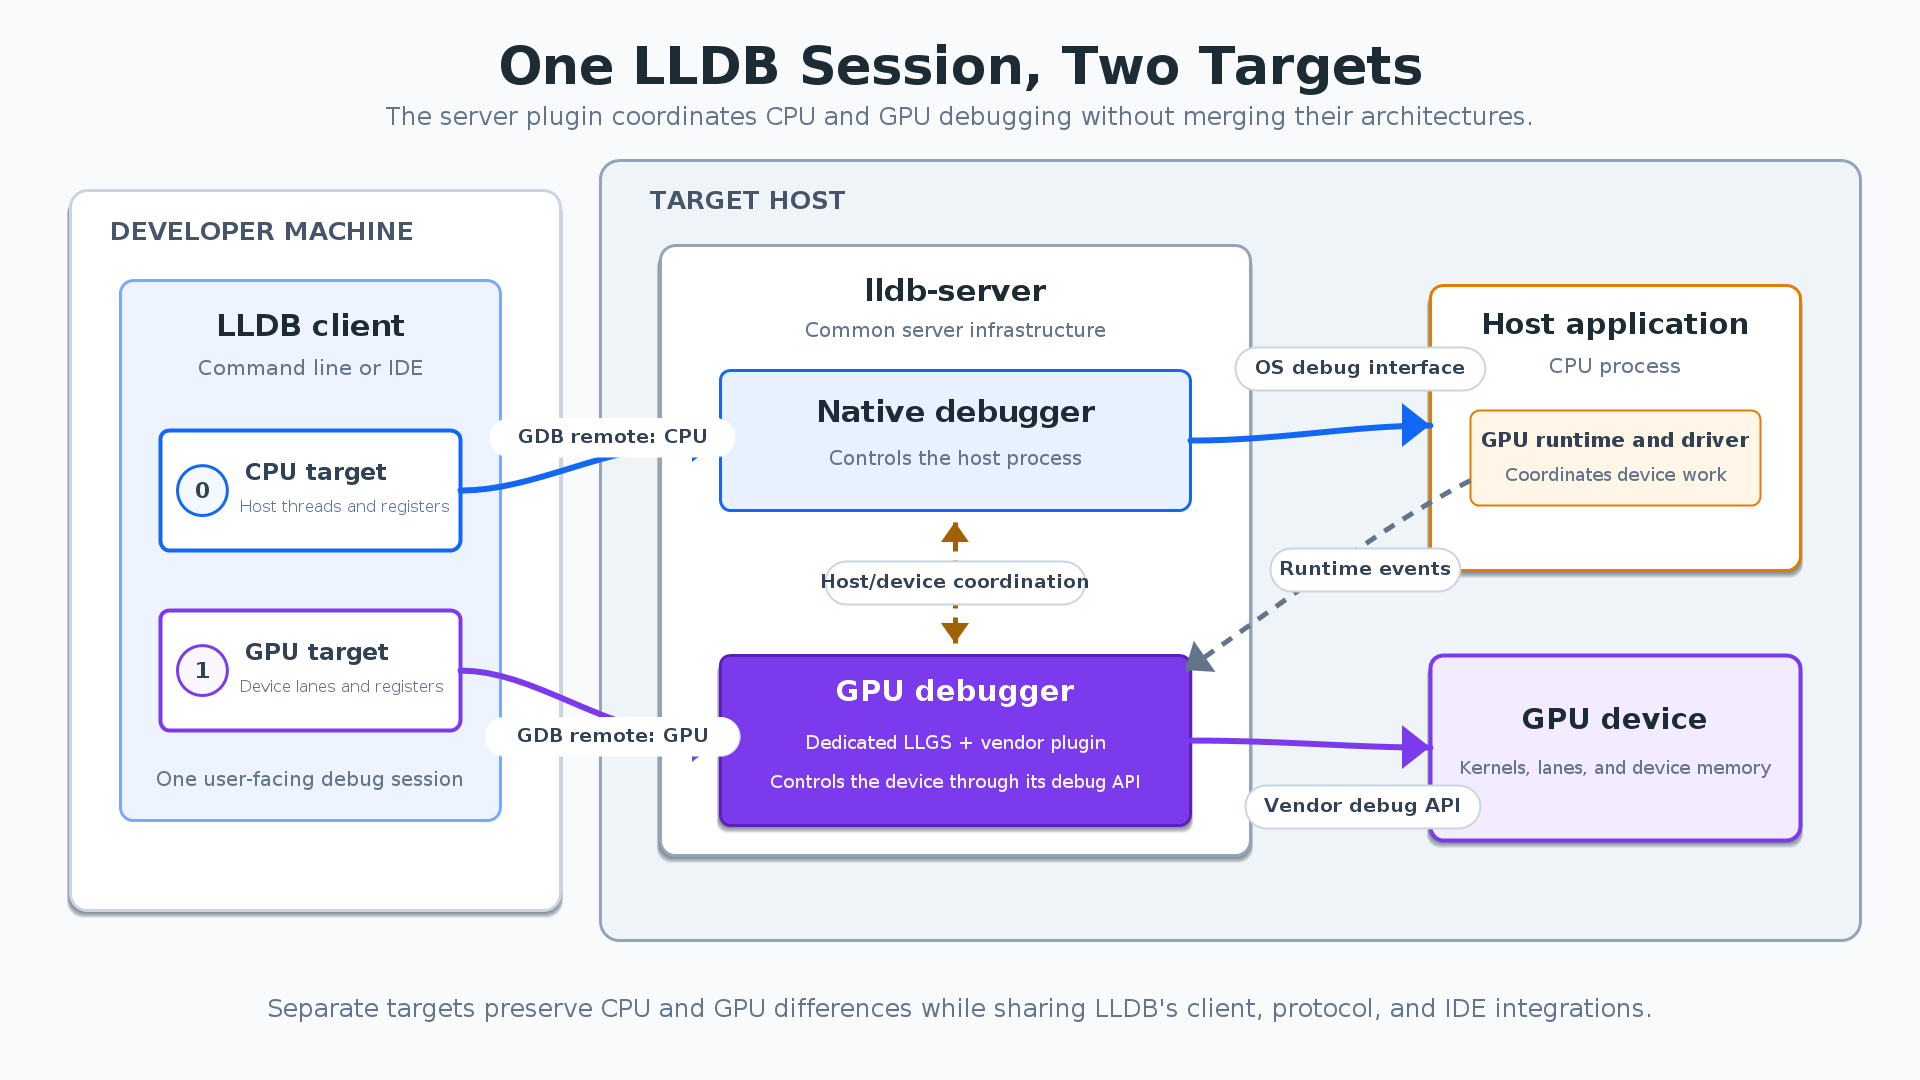
LabsExtending LLDB to Debug Applications That Span CPUs and GPUs Meta Engineering

SiliconValidating GPU Platforms with Runtime AI Inventory via the NVIDIA DSX AI Factory NVIDIA Technical Blog
SiliconOpenAI and Georgia county leaders hit with Mafia-style RICO racketeering lawsuit over $30 billion AI data center Tom's Hardware