vLLM BlogTools
Kimi K3 Performance Optimizations in vLLM: The Road to 2.8× Throughput
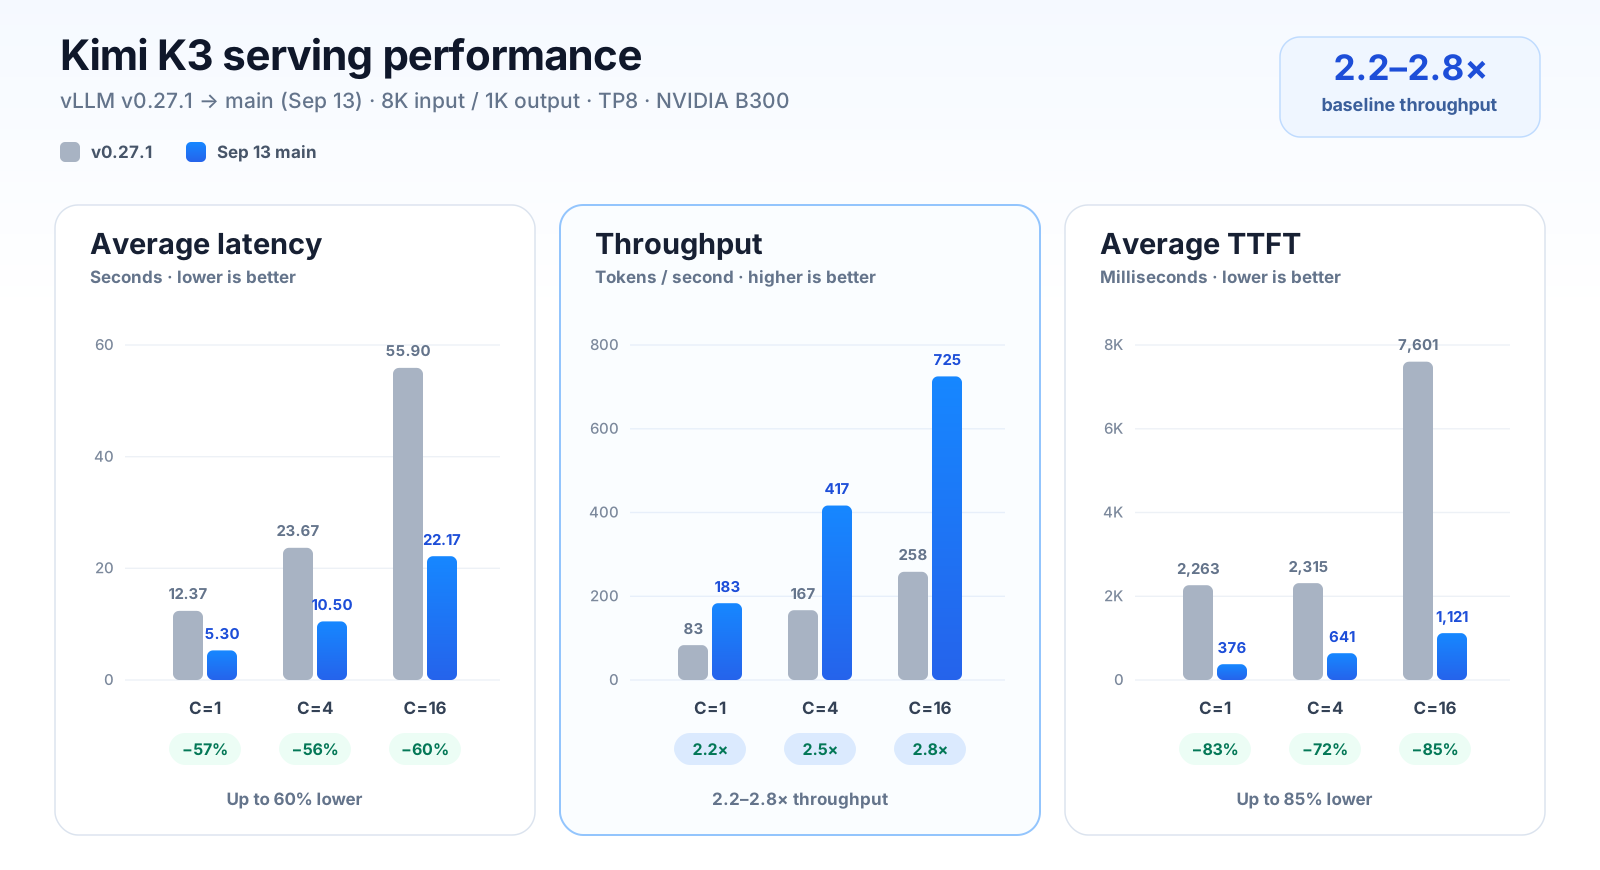
Kimi K3 serving optimizations across scheduling, KDA prefix caching, ReplaySSM state recovery, PD disaggregation and state offload, parallelism, MoE, and GPU kernels.
Read at vLLM Blog ↗Related
ToolsTiered KV Cache Offloading in vLLM vLLM Blog
ToolsGLM 5.3 Optimizations, Part 1: Hybrid HiSparse Offloading in vLLM vLLM Blog

VoicesOpen-Source AI & Open Models Reading List Interconnects

ToolsThe Open Source AI Stack Together AI
EuropeMistral raises €3B to make sovereign, open-weight AI the technology frontier Mistral AI