vLLM BlogTools
PD Serving of Qwen3.8-2.4T
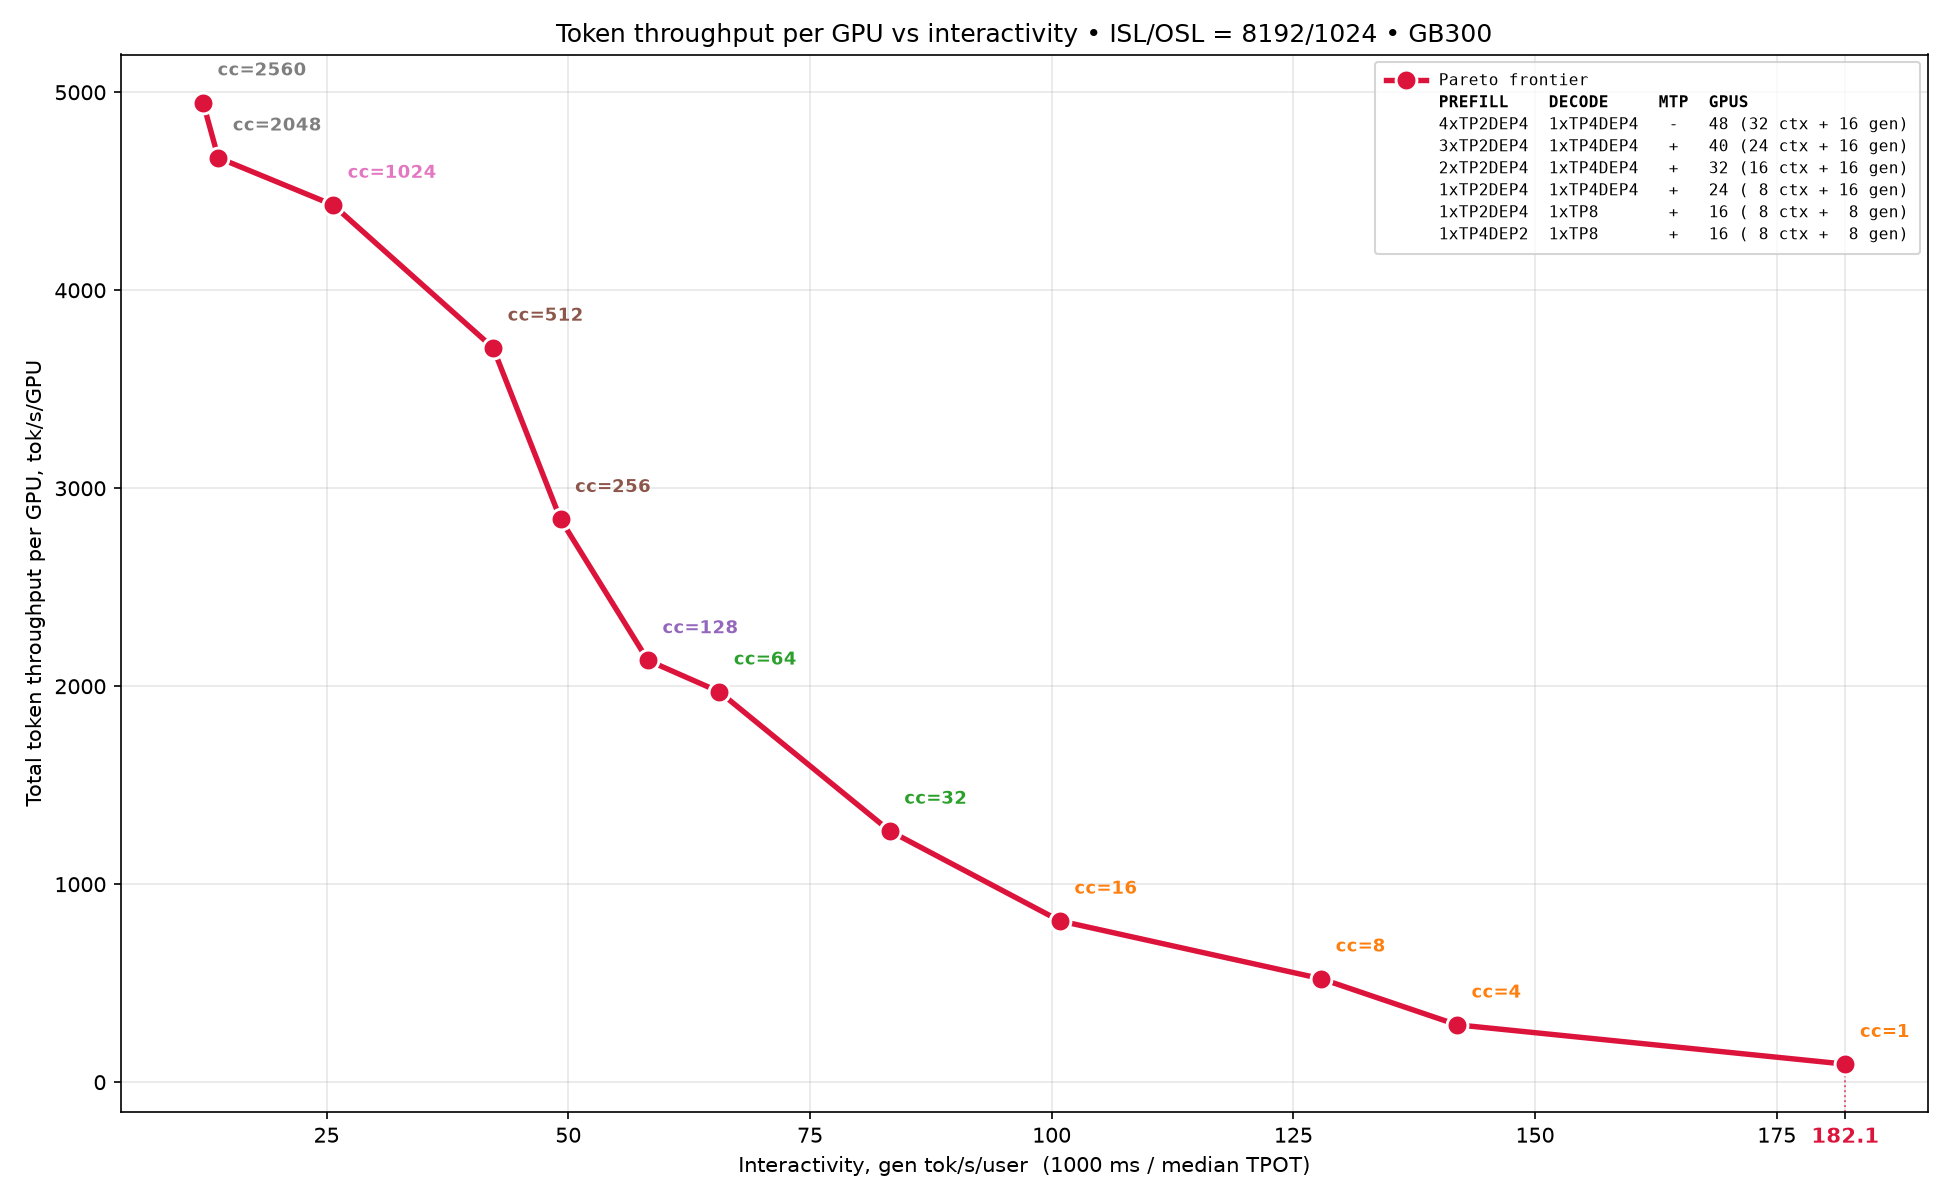
How vLLM reaches 5K throughput and 180 interactivity on Qwen3.8-2.4T with GB300 NVL72 PD serving and how to reproduce results yourself.
Read at vLLM Blog ↗Related
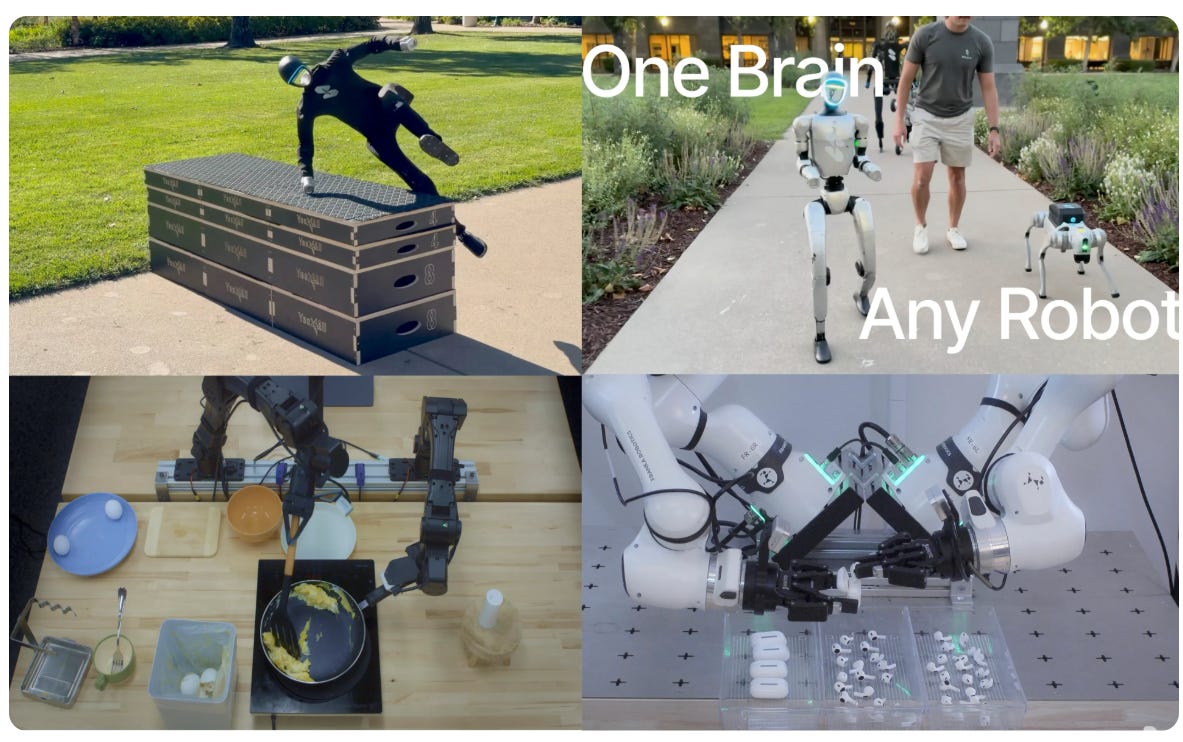
VoicesVisions of AI: GPT-3 Moment for Physical AI AI Supremacy
ToolsSplash Engine - the fastest local Qwen3.8 on Apple Silicon LM Studio Blog
EuropeMistral and Mozilla are bringing open, private and multilingual AI to your web browser Mistral AI
VoicesA Guide to Grok Bot 2026 AI Supremacy

LabsIntroducing Gemini 3.8 Live and 3.8 Live Extended Thinking Google DeepMind