No PriorsVoices
Really Big Test-Time Compute in AI Changes Benchmarks, Safety and Research with OpenAI Research Scientist Noam Brown
When a new AI model drops, it’s judged based on a static benchmark grid that doesn’t account for how long the model is allowed to think. How then should we measure a model’s true capability?
Read at No Priors ↗Related
Voices#490 – State of AI in 2026: LLMs, Coding, Scaling Laws, China, Agents, GPUs, AGI Lex Fridman Podcast
JapanFlava DBaaS deep dive: From architecture to migration and beyond LINE Yahoo / LY Tech

SiliconThe Secret Life of Computers The Chip Letter
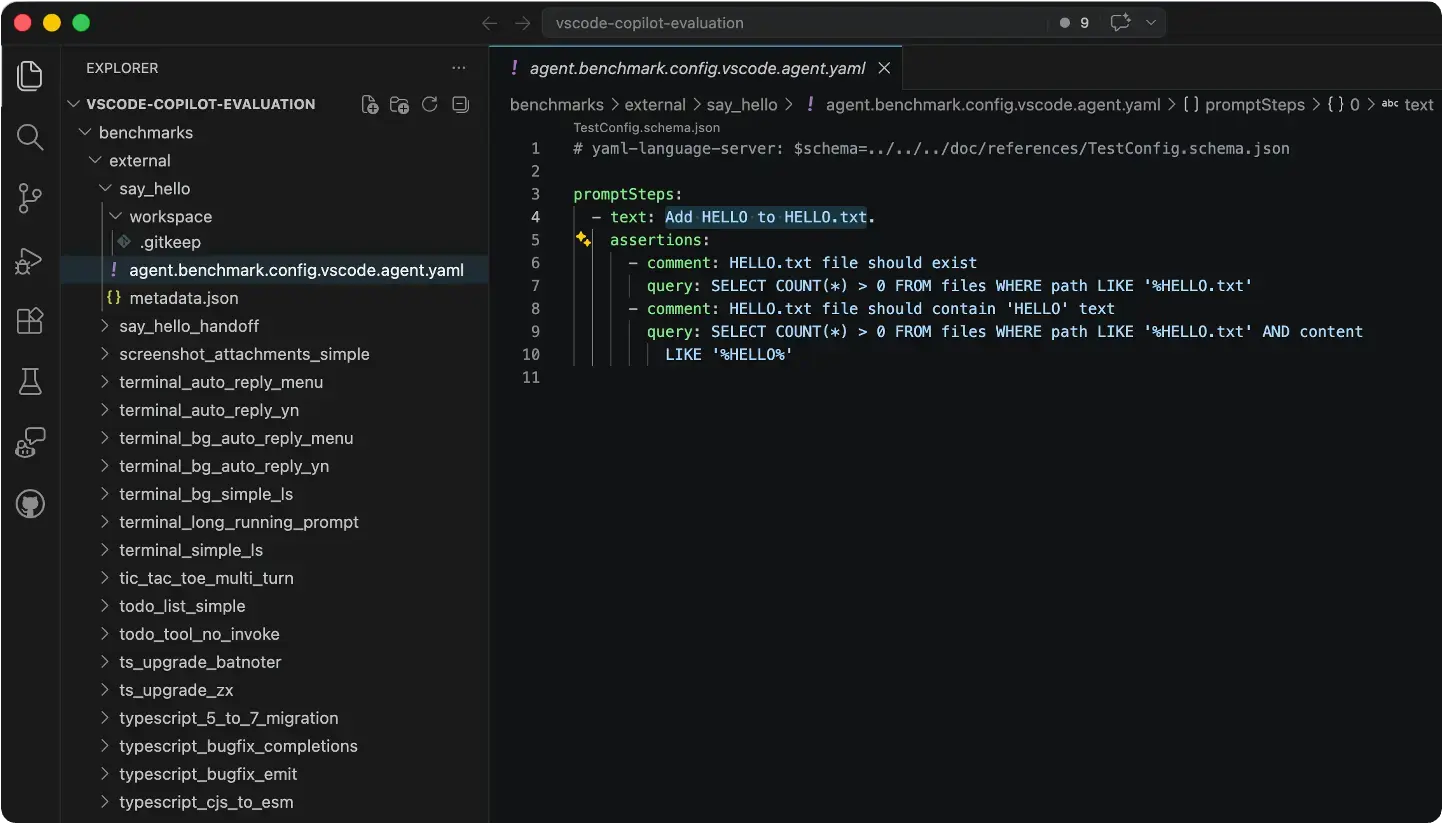
ToolsWhat 50,000 Runs of a 5-Line Eval Taught Us VS Code Updates
LanguagesModular: Modular 26.4: SOTA MoE Serving, Model Bringup via Agent Skills, Mojo 1.0 Beta 2 and More Mojo Blog