Hugging Face BlogLabs
Scaling Indic Pretraining: 2.8 Trillion Tokens and an Open Data Generation Pipeline

Native-script data for 22 languages, romanized data for twelve, and a reusable GPU-accelerated pipeline for translation, quality assessment, and repair.
Read at Hugging Face Blog ↗Related

LabsOpen TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning Hugging Face Blog

LabsHow UK AISI and EvalEval Are Making Benchmark Results Reproducible Hugging Face Blog

LabsTransformers now runs llama.cpp quants Hugging Face Blog

Labstokenizers v1: encode, decode and scaling, measured Hugging Face Blog
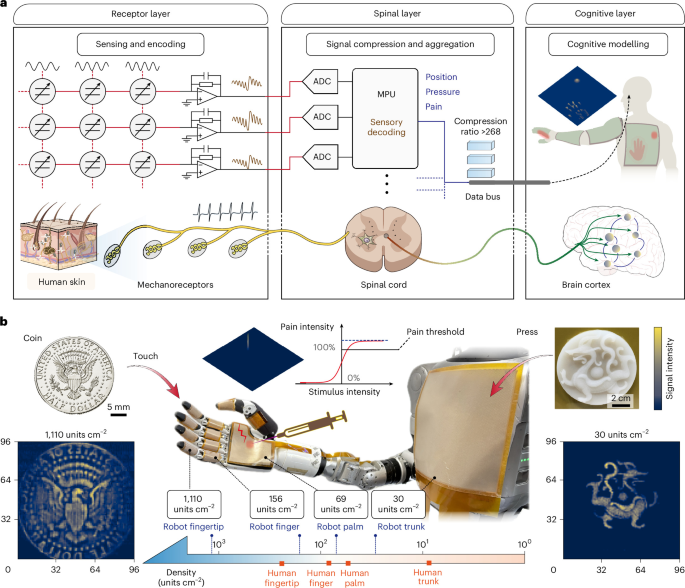
ResearchLarge-scale iontronic skins with neural-hierarchical processing architecture Nature Machine Intelligence