vLLM BlogTools
Serving Reflection Beam on vLLM from Day 0
vLLM supports Reflection's Beam-1.0 (501B total, 23B active) from day 0, with agent-driven optimization that cut decode latency 2.71× and DFlash2 speculative decoding with adaptive verification.
Read at vLLM Blog ↗Related
ToolsDay 0 support for Muse Spark Open on vLLM vLLM Blog
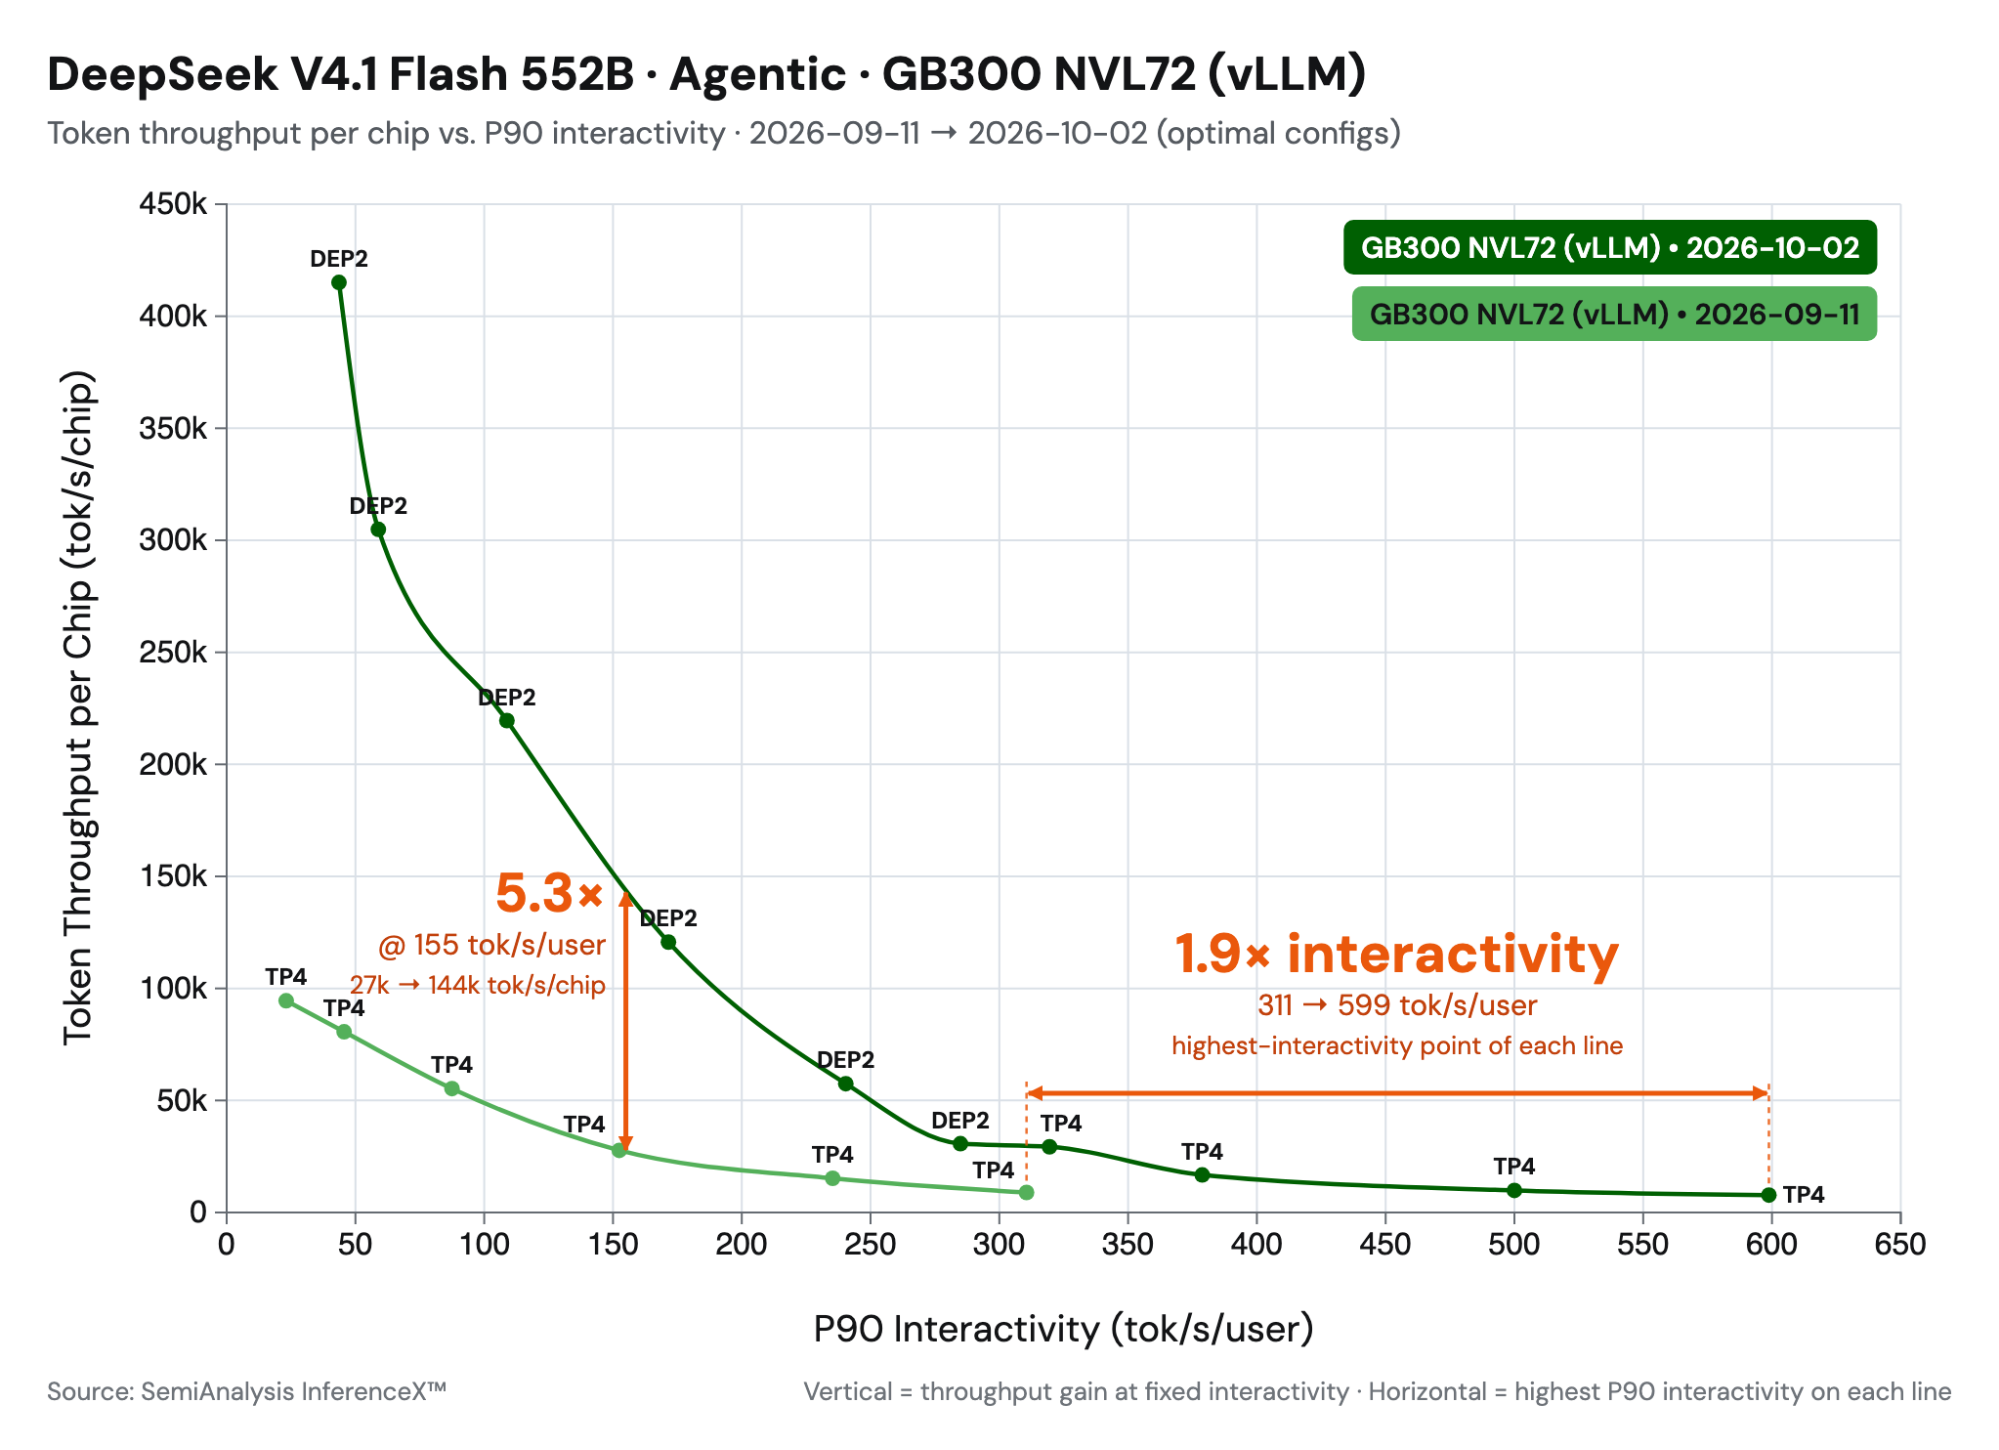
ToolsDeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 vLLM Blog

ToolsMuse Spark Is Now an Open-Weights Model PyTorch Blog

GitHubMeta ships Muse Spark Open, its answer to China’s best open-weight models The New Stack

LabsWelcome Muse Spark Open: open-weight frontier multimodal mixture-of-experts model from Meta Hugging Face Blog
