PandailyAsia
UniPat AI's SPU Benchmark Asks AI Agents to Predict Real Wet-Lab Results, and None Score Above 0.5
UniPat AI has released Science Prediction Universe, or SPU, a benchmark that asks AI agents to predict how real laboratory experiments turn out before seeing the results.
Read at Pandaily ↗Related
LabsArchitecture patterns for fast session startup on Amazon Bedrock AgentCore runtime AWS Machine Learning

LabsHow Agent Anomaly Detection scores on benchmarks we didn't write Google Developers Blog
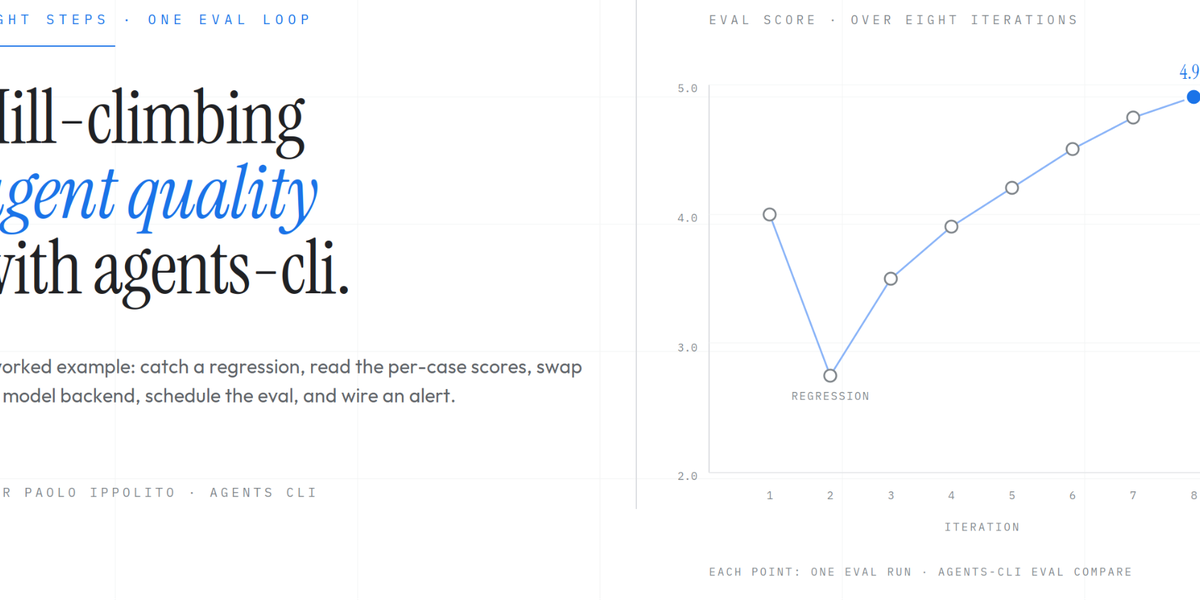
LabsHill-Climbing Agent Quality with Agents CLI Evaluation Google Developers Blog
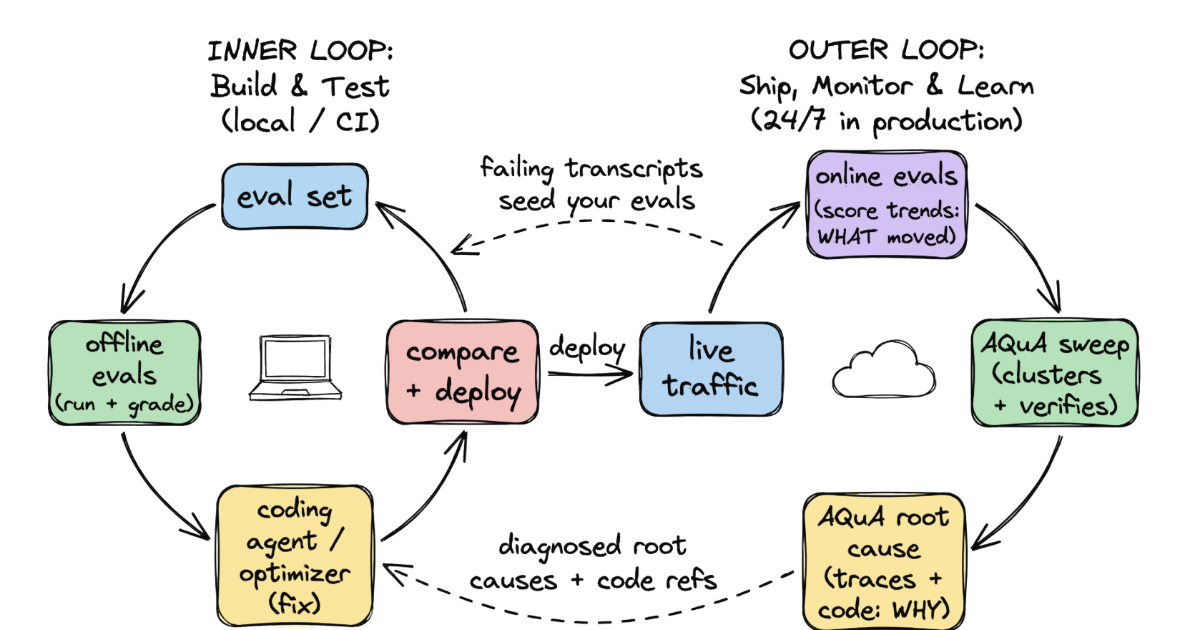
GitHubGoogle Open Sources Ambient Quality Agent (AQuA) to Diagnose Production AI Agent Failures InfoQ AI
ToolsScaling AI Agents: What We Learned From 9 Real-World Cases JetBrains Blog