NVIDIA Technical BlogSilicon
When One GPU Isn’t Enough: Serving GLM-5.3 Across Two NVIDIA DGX Stations with vLLM

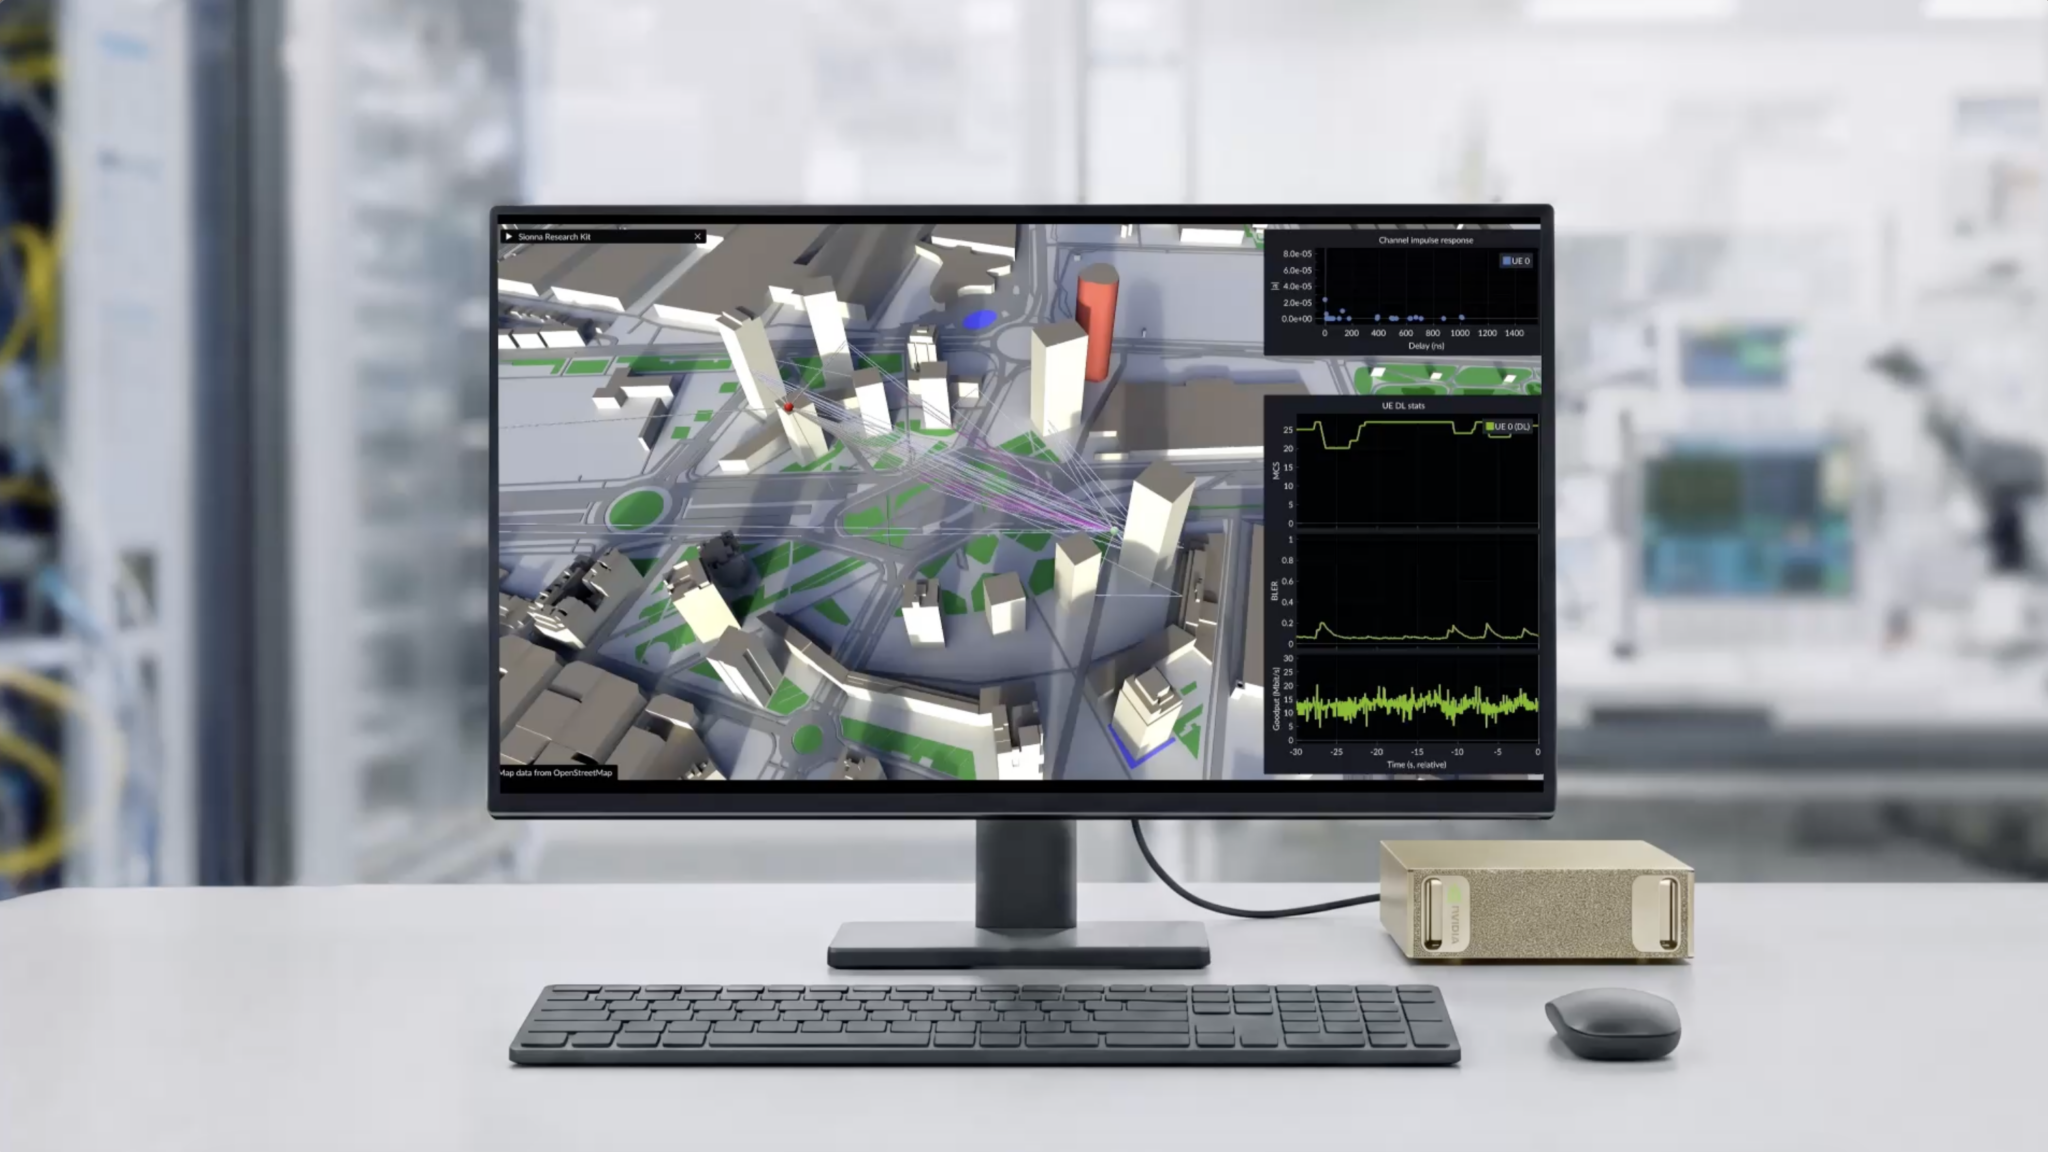
Running a frontier-scale model locally means keeping all its weights in GPU memory; the largest models no longer fit on one machine. Two NVIDIA DGX Stations...
Open weightsChips & computeAgentic AI / Generative AIEdge ComputingNetworking / CommunicationsDGX Station
Read at NVIDIA Technical Blog ↗Related
AsiaWill Jensen Huang’s downfall tip the scales against open-source AI? SCMP Tech
SiliconNVIDIA Highlights Their Open-Source vGPU Upstreaming Work Built Atop Nova Phoronix

ValleyJensen Huang’s exit puts Nvidia’s support for open source in question TechCrunch AI
GitHubGoogle Open-Sources TPU Sync for KV Cache and Weight Transfer on TPUs InfoQ AI
SiliconNVIDIA Expands Open Source Commitment With OpenShell Contribution and New AI Infrastructure NVIDIA Blog