SemiAnalysis
20 stories
SemiAnalysisSiliconDatacenters 2027: The Year of Acceleration, +50GW in a Single Year Not a week goes without another piece of datacenter FUD. We’ve already debunked in depth why moratoriums aren’t as impactful as one may think .
SemiAnalysisSiliconASML Is Building a Hybrid Bonding Tool! ASML has not announced anything yet, but its patent filings, a news report and its own roadmap all suggest so. We believe it will start with a die-to-wafer (D2W) hybrid bonding (HB) tool.
SemiAnalysisSiliconBeijing Will Not Pace the Frontier: China’s Speed-First AI Safety Regime AI safety is on fire. On 12 September 2026, Dario Amodei published an essay arguing that frontier labs must deliberately slow the pace at which they improve model capabilities.
SemiAnalysisSiliconAnthropic Subscriptions Offer 5x+ More Value Than OpenAI Subscription plans are still the primary way consumers and small businesses pay for AI. These plans are highly subsidized—as we previously explained in June —but can still make economic sense as…
SemiAnalysisSiliconHow GLM5.3 Sparse Attention Affects HBM Memory Usage How Sparse Attention Affects DRAM/NAND Memory How does sparse attention affect the TAM of memory, including HBM and NAND?
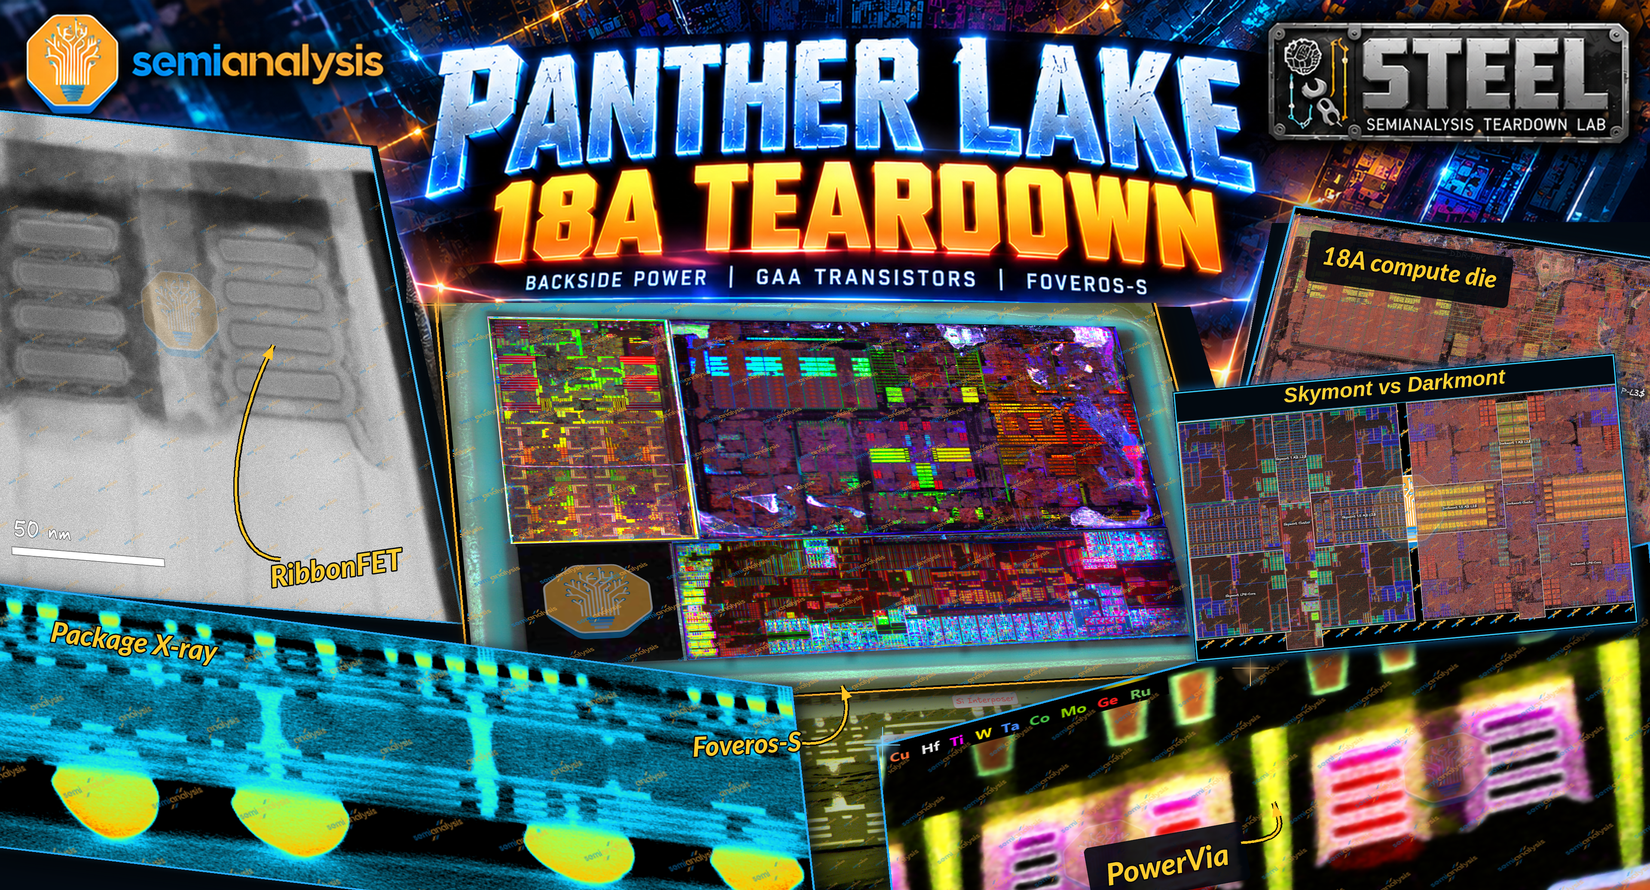
SemiAnalysisSiliconIntel Panther Lake Teardown Panther Lake debuts the first commercial implementation of a backside power delivery network (BSPDN), introduces Intel’s first iteration of gate-all-around (GAA) transistors, and showcases their…
SemiAnalysisSiliconThe Chinese AI Infrastructure Boom: Introducing the SemiAnalysis China Datacenter Model China sits at the frontier of the global model race. GLM 5.3 and Kimi K3 are the latest in a run of striking open-weights releases.
SemiAnalysisSiliconClusterMAX 3.0: The Industry Standard GPU Cloud Rating System Returns This post has bonus content for paid subscribers. Upgrade to get full access. In 8 months since our last major release of ClusterMAX, slavering investors have just about run out of pockets to stuff…
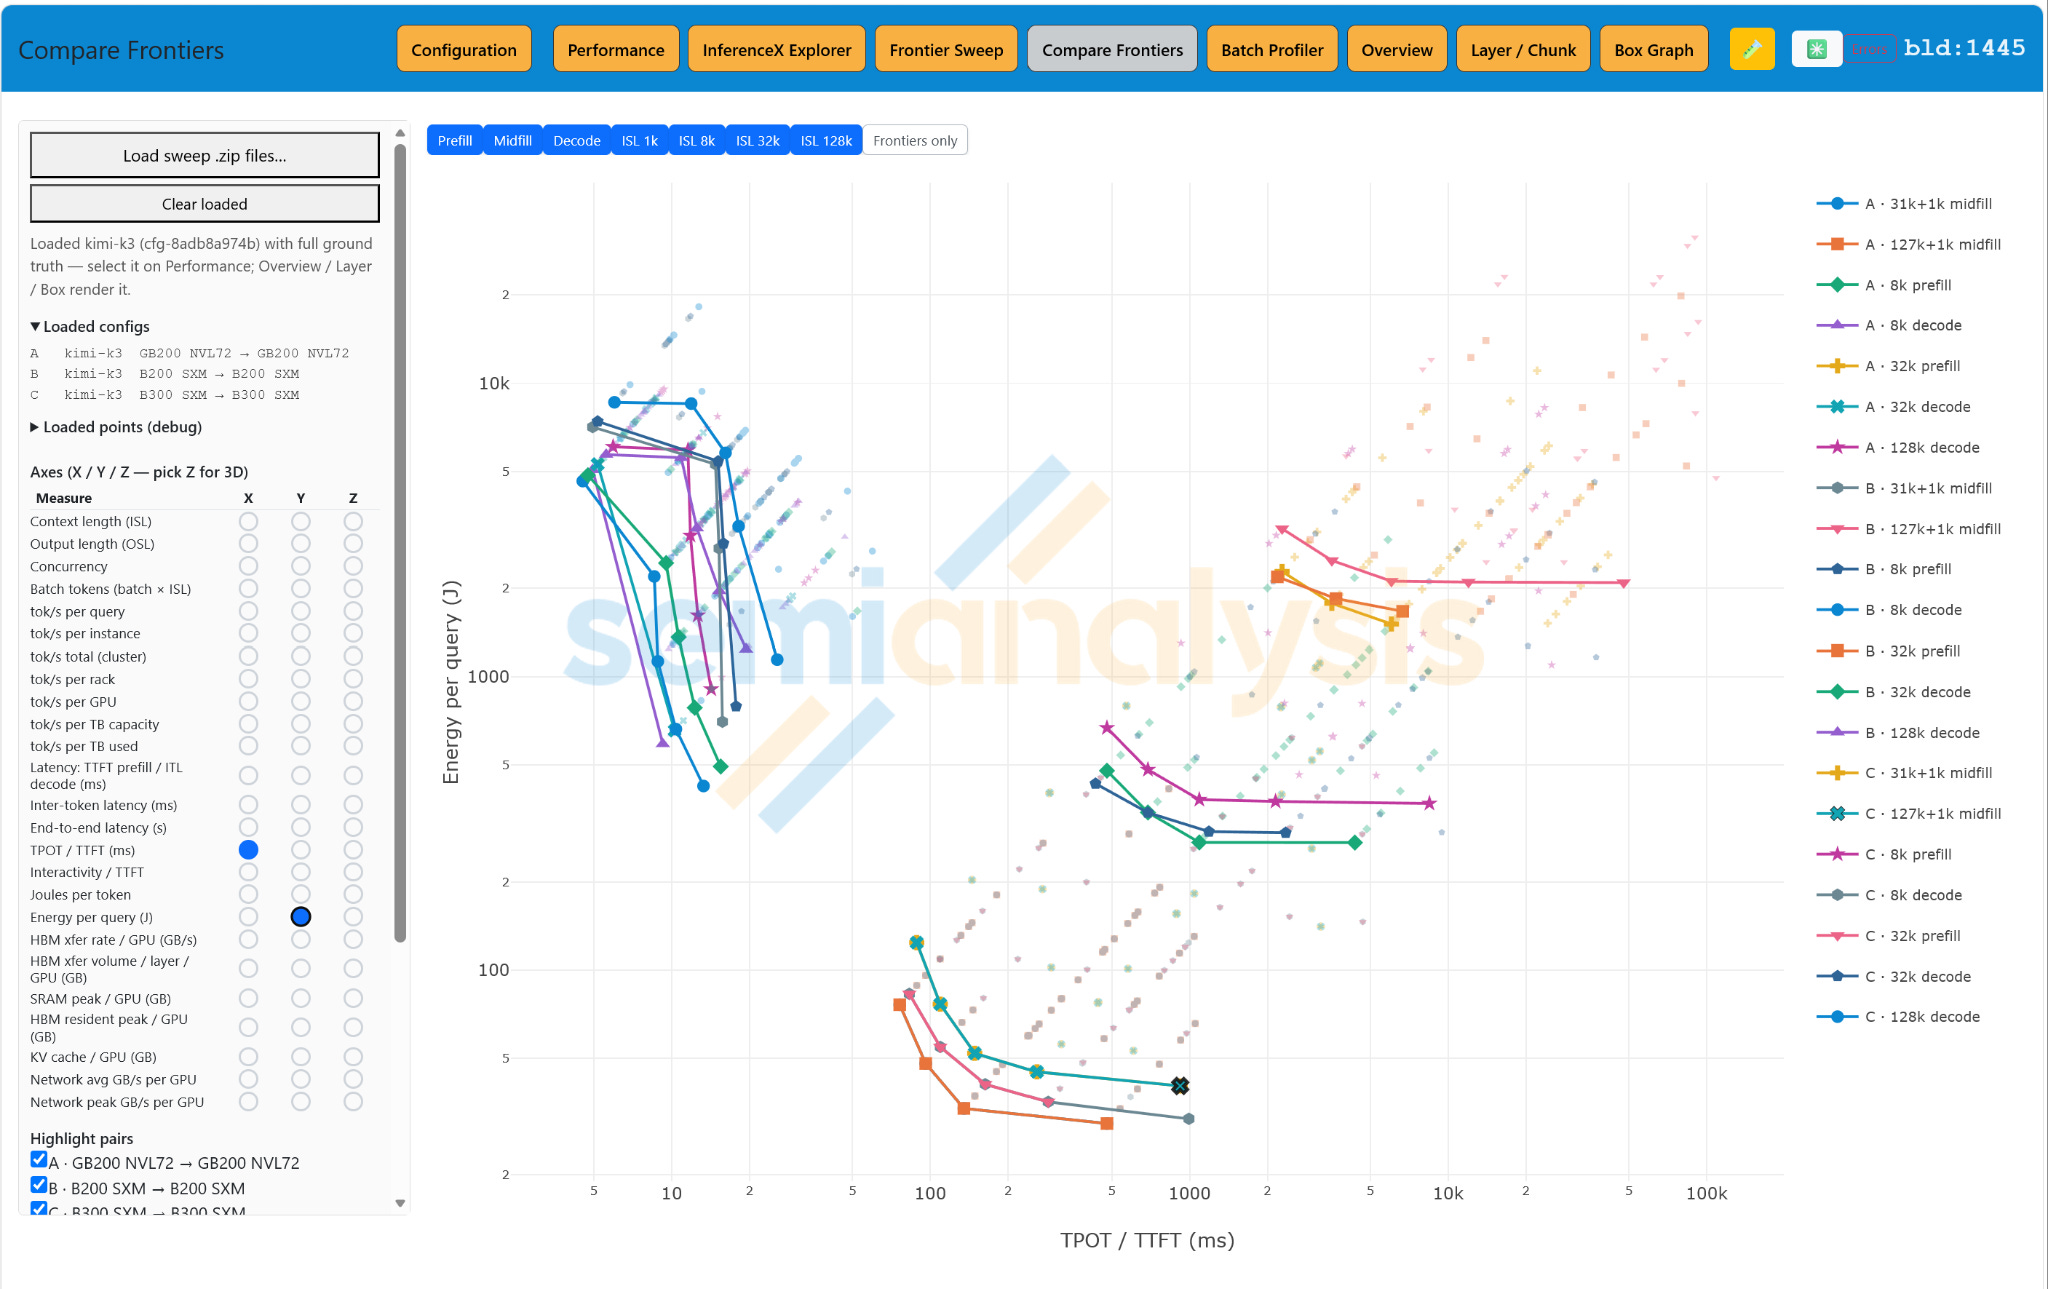
SemiAnalysisSiliconComputation and Data Movement for Inference Mixture of Experts, now widely used in frontier models, has changed both the structure of serving and the economics of useful inference. It did more than increase parameter count.
SemiAnalysisSiliconEngrams Embedding Entendre: Codesign for Efficient DRAM/SSD Offloading Engram extends standard token embeddings with learned multi-token lookups. Recurring local patterns retrieve vectors directly, reducing the need to reconstruct them through attention and feed-forward…
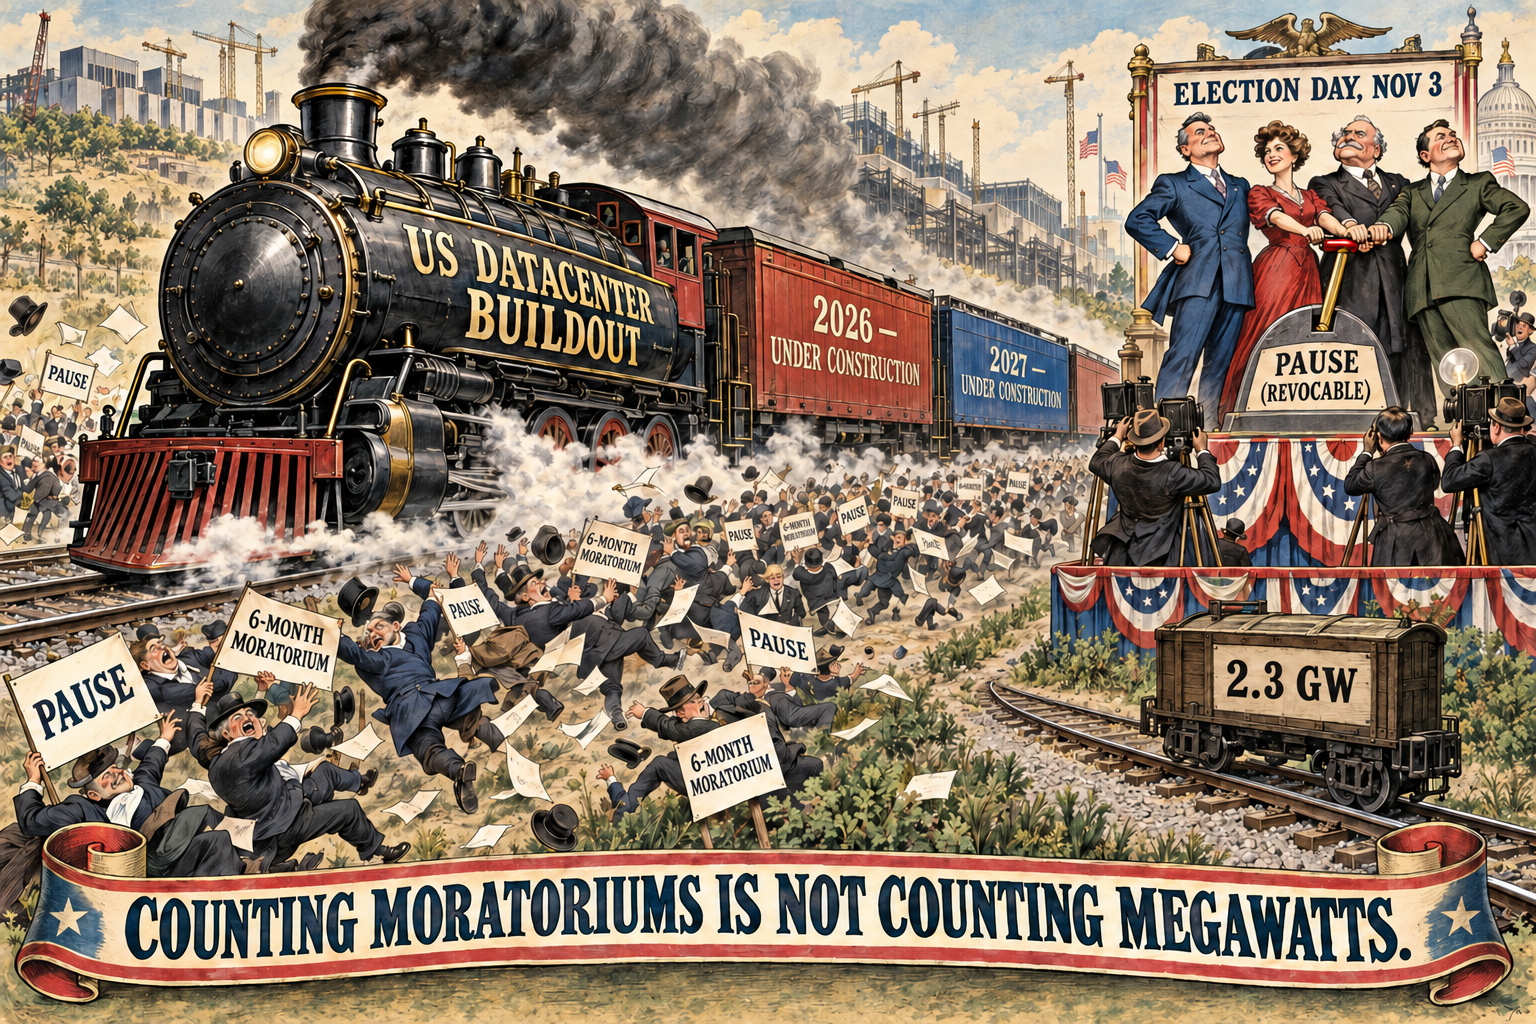
SemiAnalysisSiliconEveryone Says Datacenter Moratoriums Are Killing the US Buildout. We disagree The debate on US datacenters has never been so politically charged. Four states have acted in under two months.
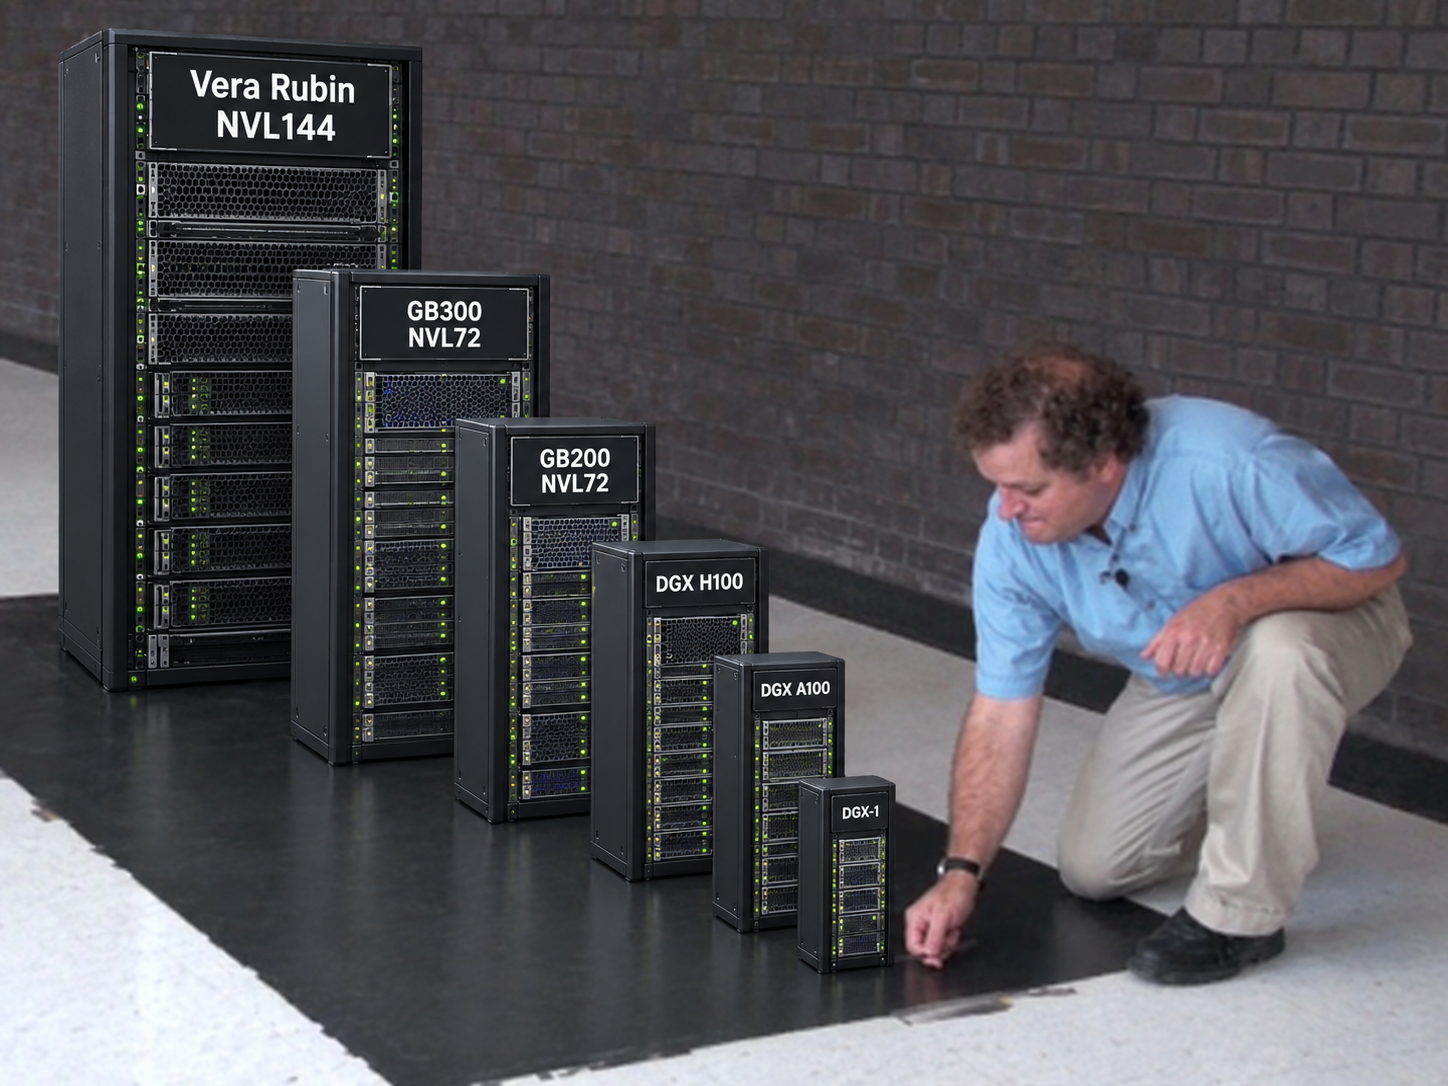
SemiAnalysisSiliconVera Rubin NVL72 Agentic Inference: 67x better Performance per Dollar Rubin is the first platform co-designed across six products for the agentic era: Rubin GPU, Vera CPU, NVLink 6 Switch, ConnectX-9, BlueField-4, and Spectrum-6.
SemiAnalysisSiliconA Brain Too Big to Carry — On-Device vs Datacenter Inference Where should the brain of the robot go? So far, AI has mostly lived behind a screen. Chatbots answered questions. Then agents started driving software and finishing multi-step tasks on their own.
SemiAnalysisSiliconLong Live the Short King: Why 4-hi HBM Wins High Bandwidth Memory has been a key technology enabling the AI revolution. Despite HBM’s high costs relative to other forms of memory, chip designers have packaged more and more HBM into AI…

SemiAnalysisSiliconNvidia’s Backstop Universe – Heads I Win, Tails Who Loses? Follow the money behind the AI buildout with our AI Compute, Capital and Markets Model - understand who is funding the expansion, how deals are structured, and where the risks sit.
SemiAnalysisSiliconWhat is So Hard About Behind-The-Meter Power For Datacenters? Part 1 Last year we were the first to call out Onsite Gas Generation as the primary method adopted by AI Labs and Hyperscalers to solve power constraints .
SemiAnalysisSiliconTPU Inference Externalization Full Steam Ahead - InferenceX For more than a decade, the industry has watched Google build an empire on its own silicon. Search, Ads, YouTube, and every generation of Gemini run on TPUs.
SemiAnalysisSiliconKorea’s Trillion-Dollar Sovereign AI Investment: Nvidia Wins, Hynix Loses Every day, businesses and governments around the world are becoming increasingly reliant on America’s frontier models.
SemiAnalysisSiliconMost Neoclouds Suck At Security In Shakespeare’s Julius Caesar , Caesar ignores a soothsayer’s warning, shrugs off his wife’s dream of blood running through the streets, waves away a letter revealing his assassins by name, and…
SemiAnalysisSiliconOpenAI Jalapeño: Better Than Nvidia Blackwell OpenAI has spent the past couple years quietly building “Jalapeño,” an inference chip just announced at Hot Chips. Rumors of a successful tapeout had been swirling for a while.
Nothing matches this filter yet.