vLLM BlogTools
Announcing Humming: Fast, Flexible Kernels for Quantized Inference
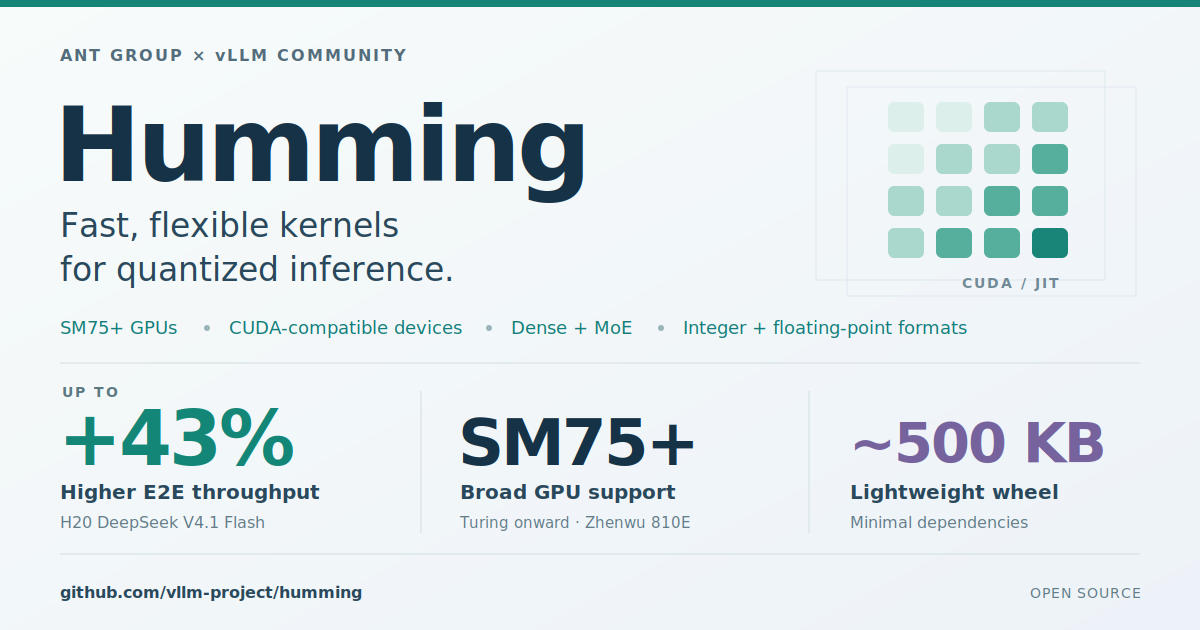
Introducing Humming, a quantized inference kernel library from Ant Group and the vLLM community, with broad GPU and quantization support, dense and MoE performance results, and vLLM integration.
Read at vLLM Blog ↗Related
ToolsIntroducing vLLM TorchTPU vLLM Blog
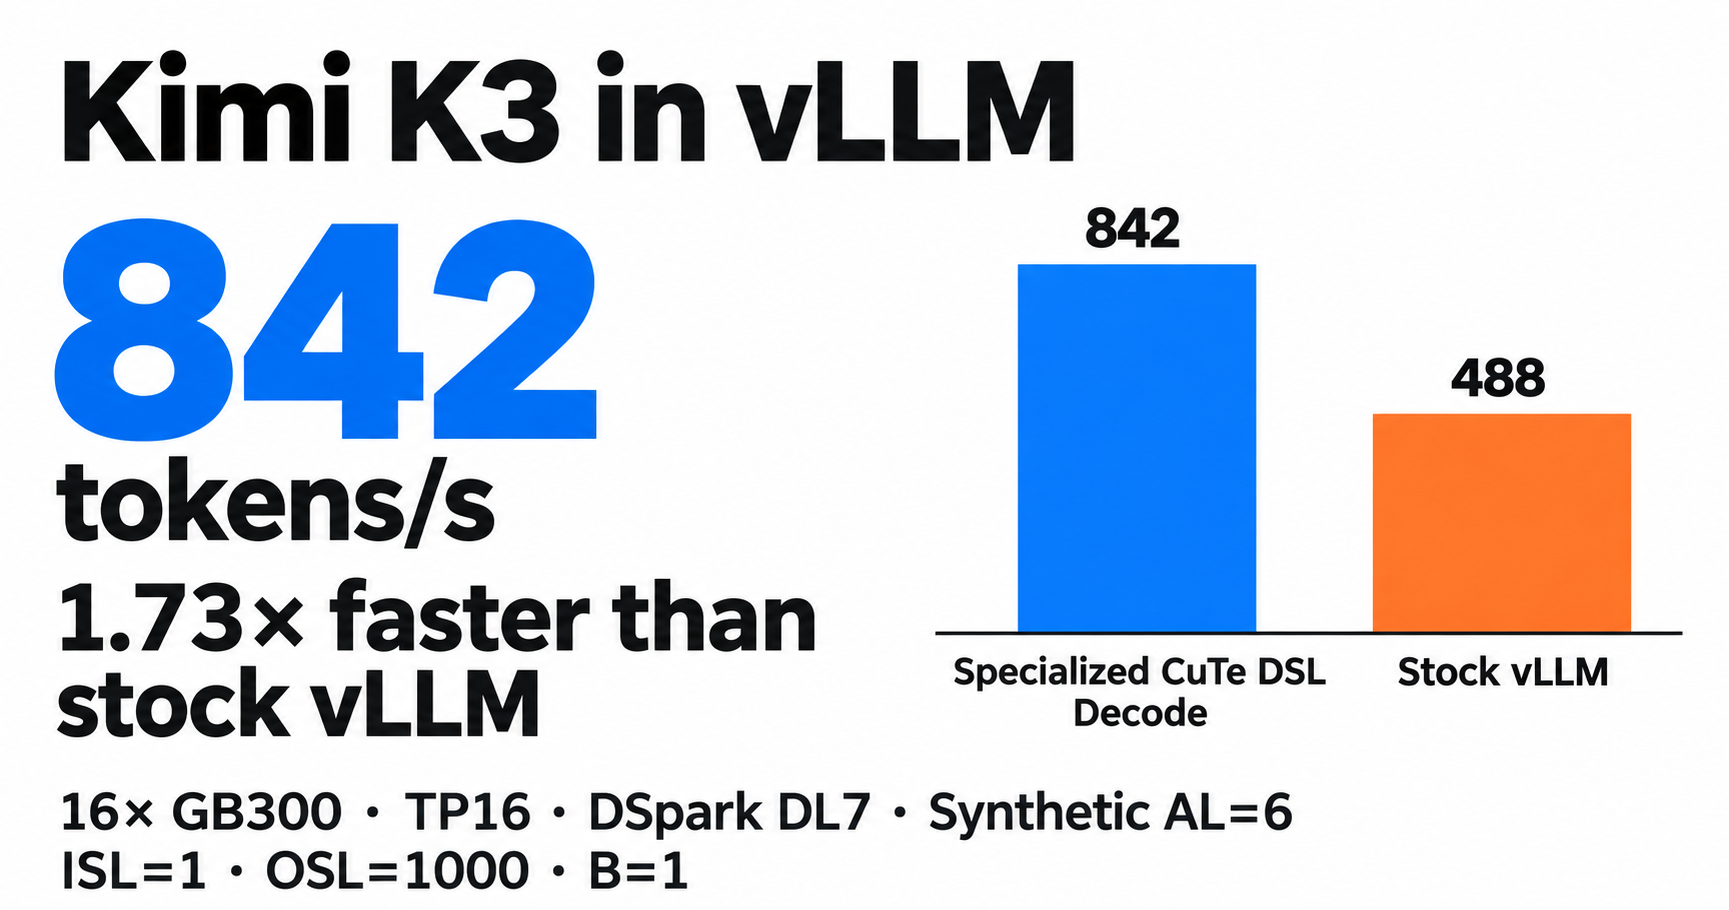
ToolsHyper Optimizing Kimi K3 in vLLM: Moving Fast and Responsibly vLLM Blog
ToolsServing Reflection Beam on vLLM from Day 0 vLLM Blog
ToolsDay 0 support for Muse Spark Open on vLLM vLLM Blog
ToolsAnnouncing Day 0 Support for NVIDIA Nemotron 3.5 Super VL on vLLM vLLM Blog