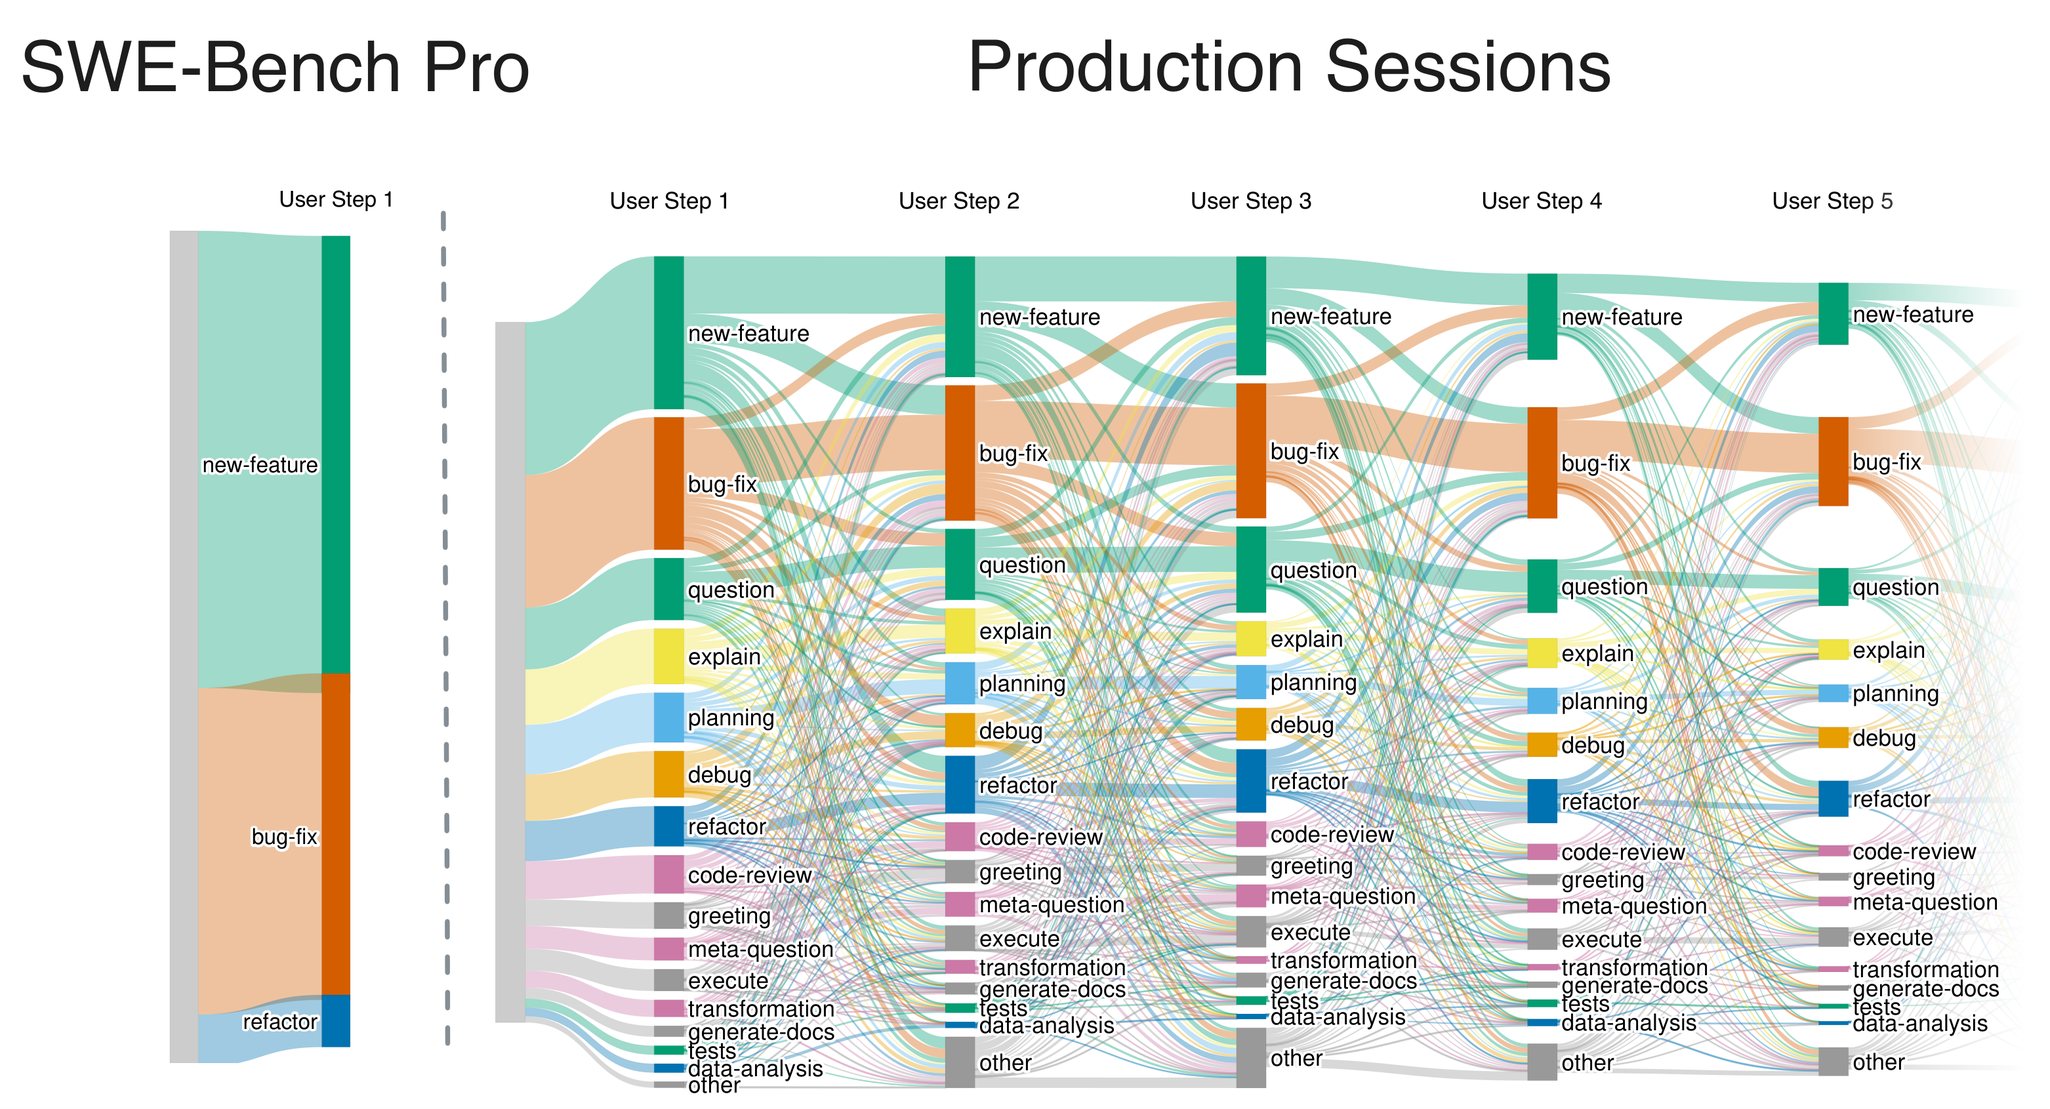
The New StackGitHub
Assess the entire inference stack — not just open model benchmarks

Impressive benchmark results should make it easy for engineers to select the right open model for the outcome they are tasked with developing. However, that is not the case.
Read at The New Stack ↗Related

ResearchStrengthening AI safety evaluation through independent third-party review Amazon Science
LabsFine-tuning GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod AWS Machine Learning

LabsFairStress: A deeper evaluation of fairness in LLM decision-making Hugging Face Blog
SiliconMysterious AMD Zen 6 APU with 24GB of LPDDR5 memory appears in benchmarks Tom's Hardware
GitHubPresentation: Beyond the Prototype: Scaling Framework Agnostic AI Agent Infrastructure with Ray InfoQ AI