llama.cpp releasesTools
b11866
metal : remove mul_mm_id amax rescaling ( #30924 ) The src1 power-of-two rescale in kernel_mul_mm_id is superseded by the per expert-token amax scaling done in the compute graph (ref: #30861 ), which…
Read at llama.cpp releases ↗Related

Japanエージェントの記憶は「要約」ではなく「KVキャッシュの直接操作」で圧縮できるのか、135Mモデルで試した Zenn (AI)
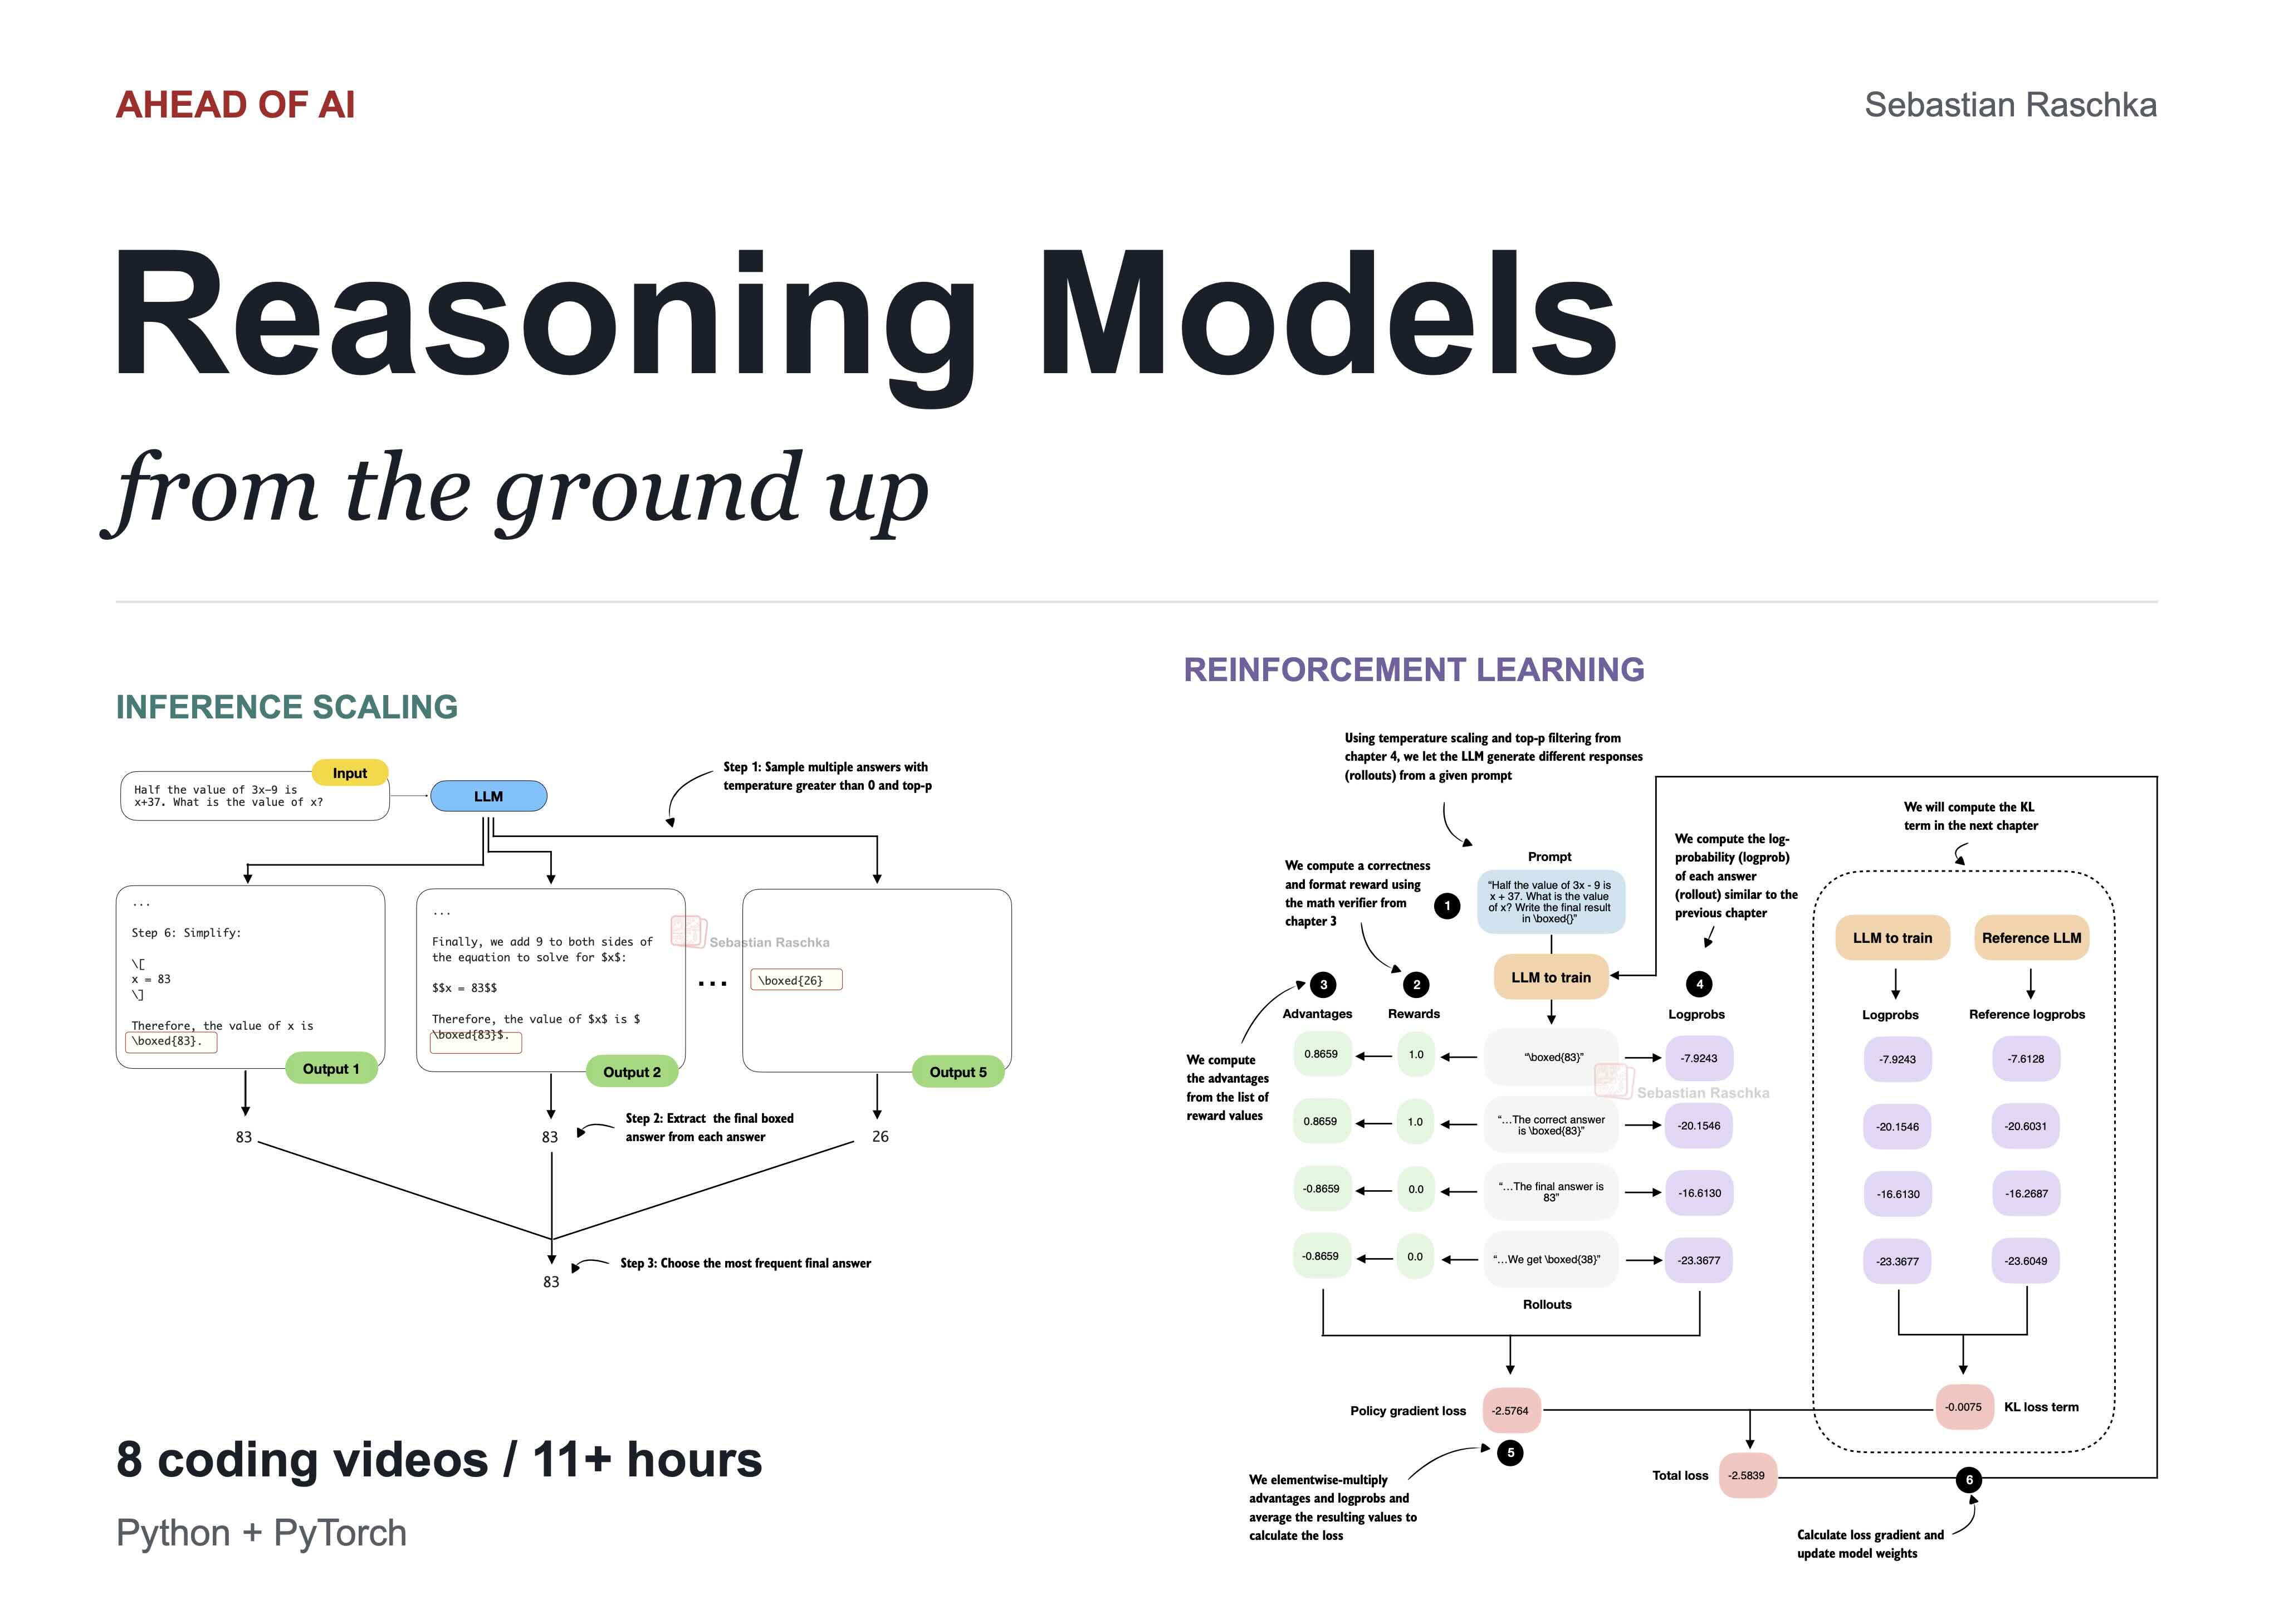
VoicesBuilding Reasoning Models from the Ground Up: A Full Video Course Ahead of AI
ToolsContext Engineering (Agent Memory) for AI Agents Starts with Retrieval LangChain
LabsMulti-Turn Reinforcement Learning on Amazon SageMaker AI: A hands-on guide AWS Machine Learning

SiliconScaling NVIDIA TensorRT Performance Optimization Beyond a Single Build Route with the Global Performance Tuner, Part 2 NVIDIA Technical Blog
