Amazon ScienceResearch
Capturing token IDs during agentic interactions for better reinforcement learning

Reinforcement learning (RL) is one of the techniques we use to make language models better at sustained, multistep tasks like writing code, navigating a website, or carrying out a research workflow.
Read at Amazon Science ↗Related
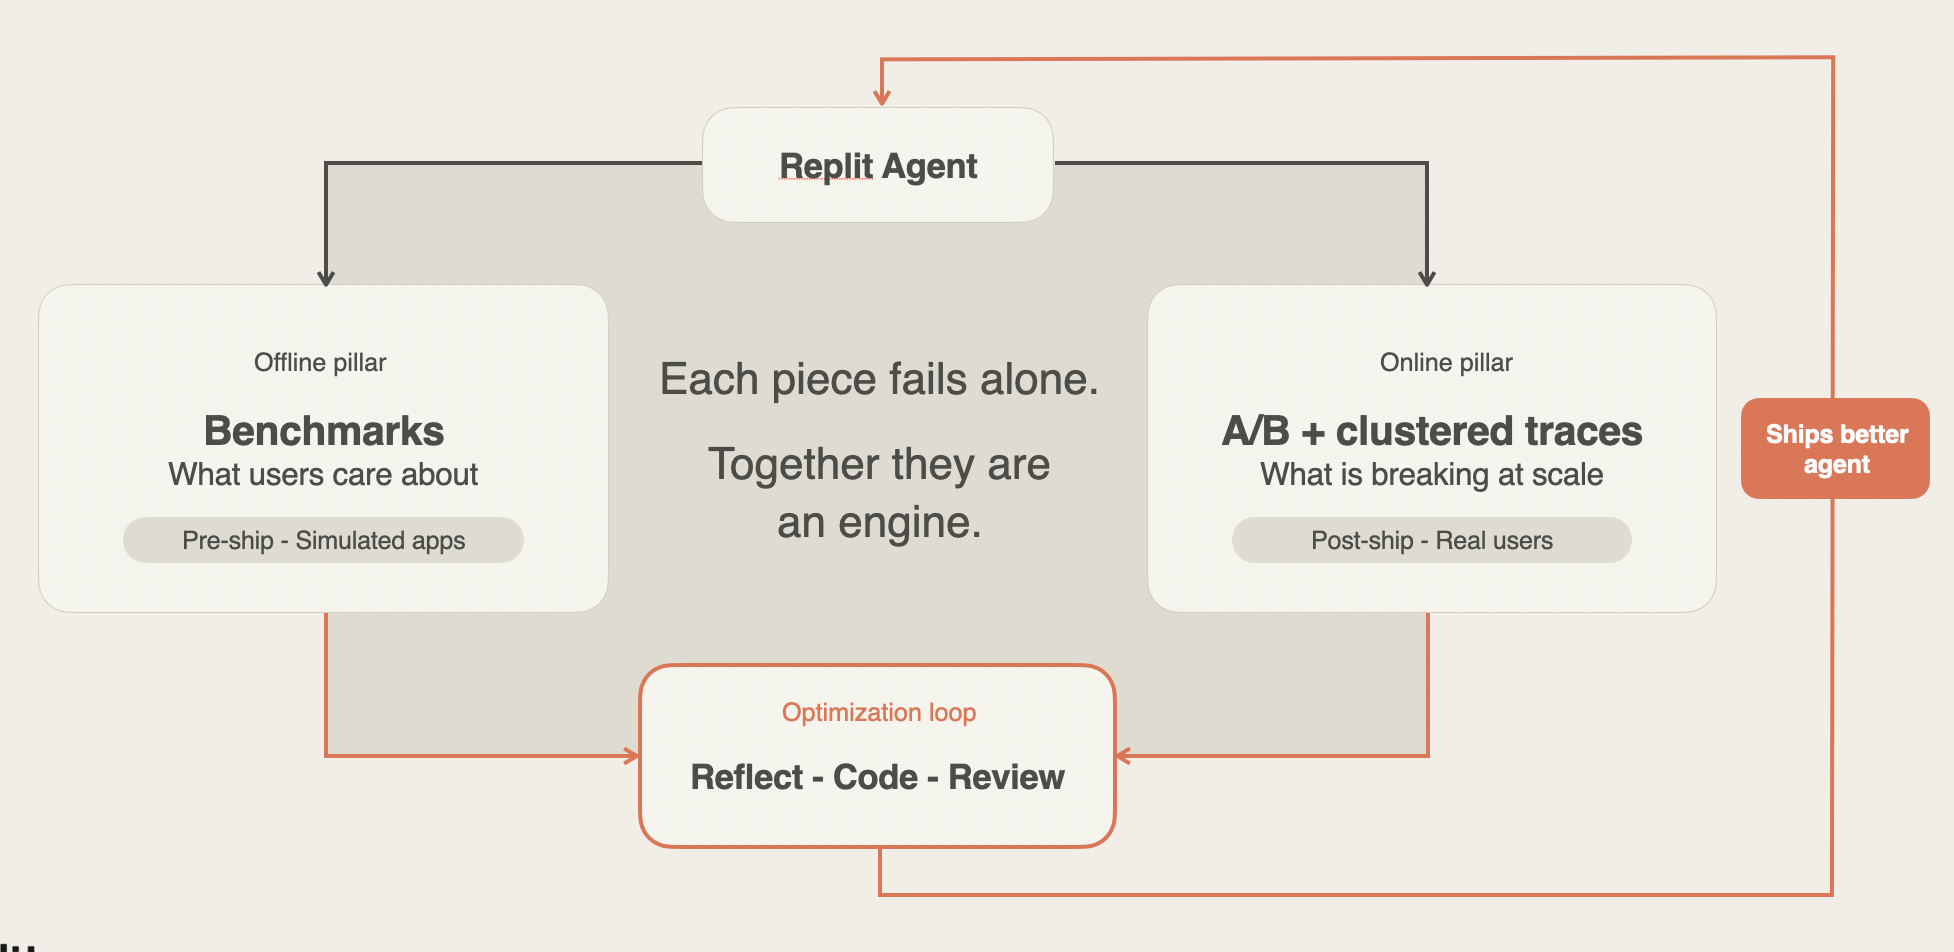
ToolsClosing the loop: Evaluating and improving Replit Agent at scale Replit Blog
LanguagesModular: Modular 26.4: SOTA MoE Serving, Model Bringup via Agent Skills, Mojo 1.0 Beta 2 and More Mojo Blog
ToolsOpus 4.7 for 33% less: How Auggie beats Claude Code on cost and quality Augment Code
LanguagesModular: How Frontier Coding Agents Built a Video Diffusion Pipeline on MAX Mojo Blog
VoicesEvals Skills for Coding Agents Hamel Husain