Phil SchmidVoices
Evaluating Agents Beyond the First Prompt

EvoCode-Bench tests coding agents across 227 sequential rounds in a persistent workspace. Single-turn scores overstate reliability — regressions, not missing features, are the real bottleneck.
Read at Phil Schmid ↗Related

VoicesPractical Guide to Evaluating and Testing Agent Skills Phil Schmid

ResearchCapturing token IDs during agentic interactions for better reinforcement learning Amazon Science
LanguagesModular: Modular 26.4: SOTA MoE Serving, Model Bringup via Agent Skills, Mojo 1.0 Beta 2 and More Mojo Blog
VoicesEvals Skills for Coding Agents Hamel Husain
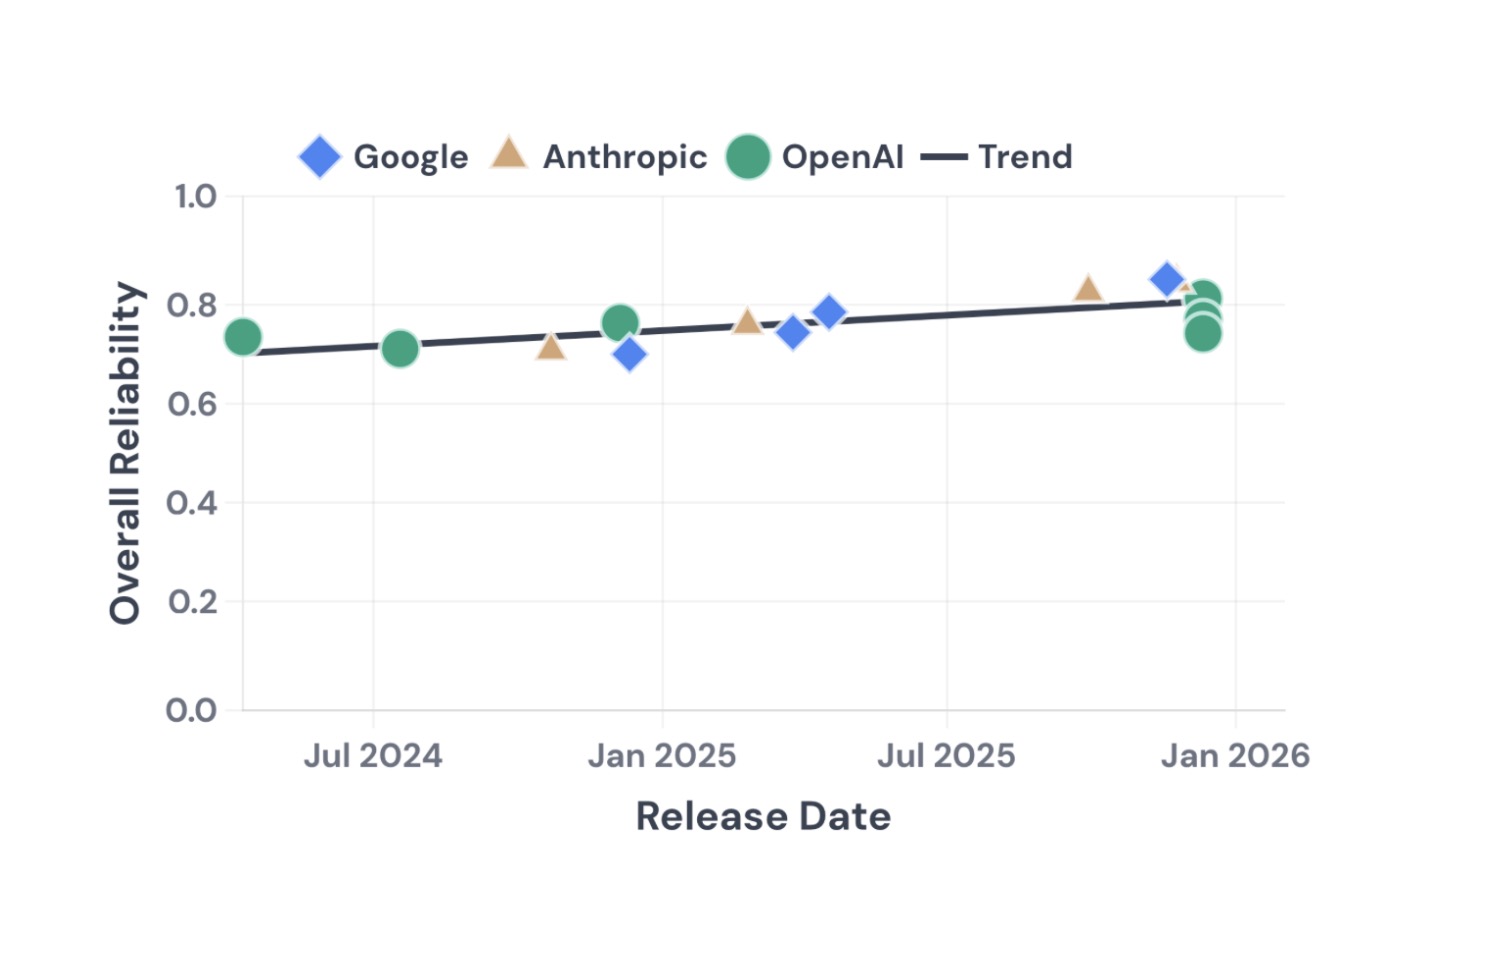
VoicesNew Paper: Towards a science of AI agent reliability AI Snake Oil