AI Alignment ForumResearch
Fixed-weight models are adversarially vulnerable: hence misaligned
This post argues that fixed-weight models (at least as we understand them today) will a) always be vulnerable to adversarial examples in their concept-spaces, and b) hence will be misaligned, under…
Read at AI Alignment Forum ↗More from AI Alignment Forum on Accept All
ResearchContinual learning might make your blocking monitors nearly useless AI Alignment Forum
ResearchLatent reasoning architectures would undermine CoT, our strongest oversight tool AI Alignment Forum
ResearchWhy I'm scared of RL AI Alignment Forum
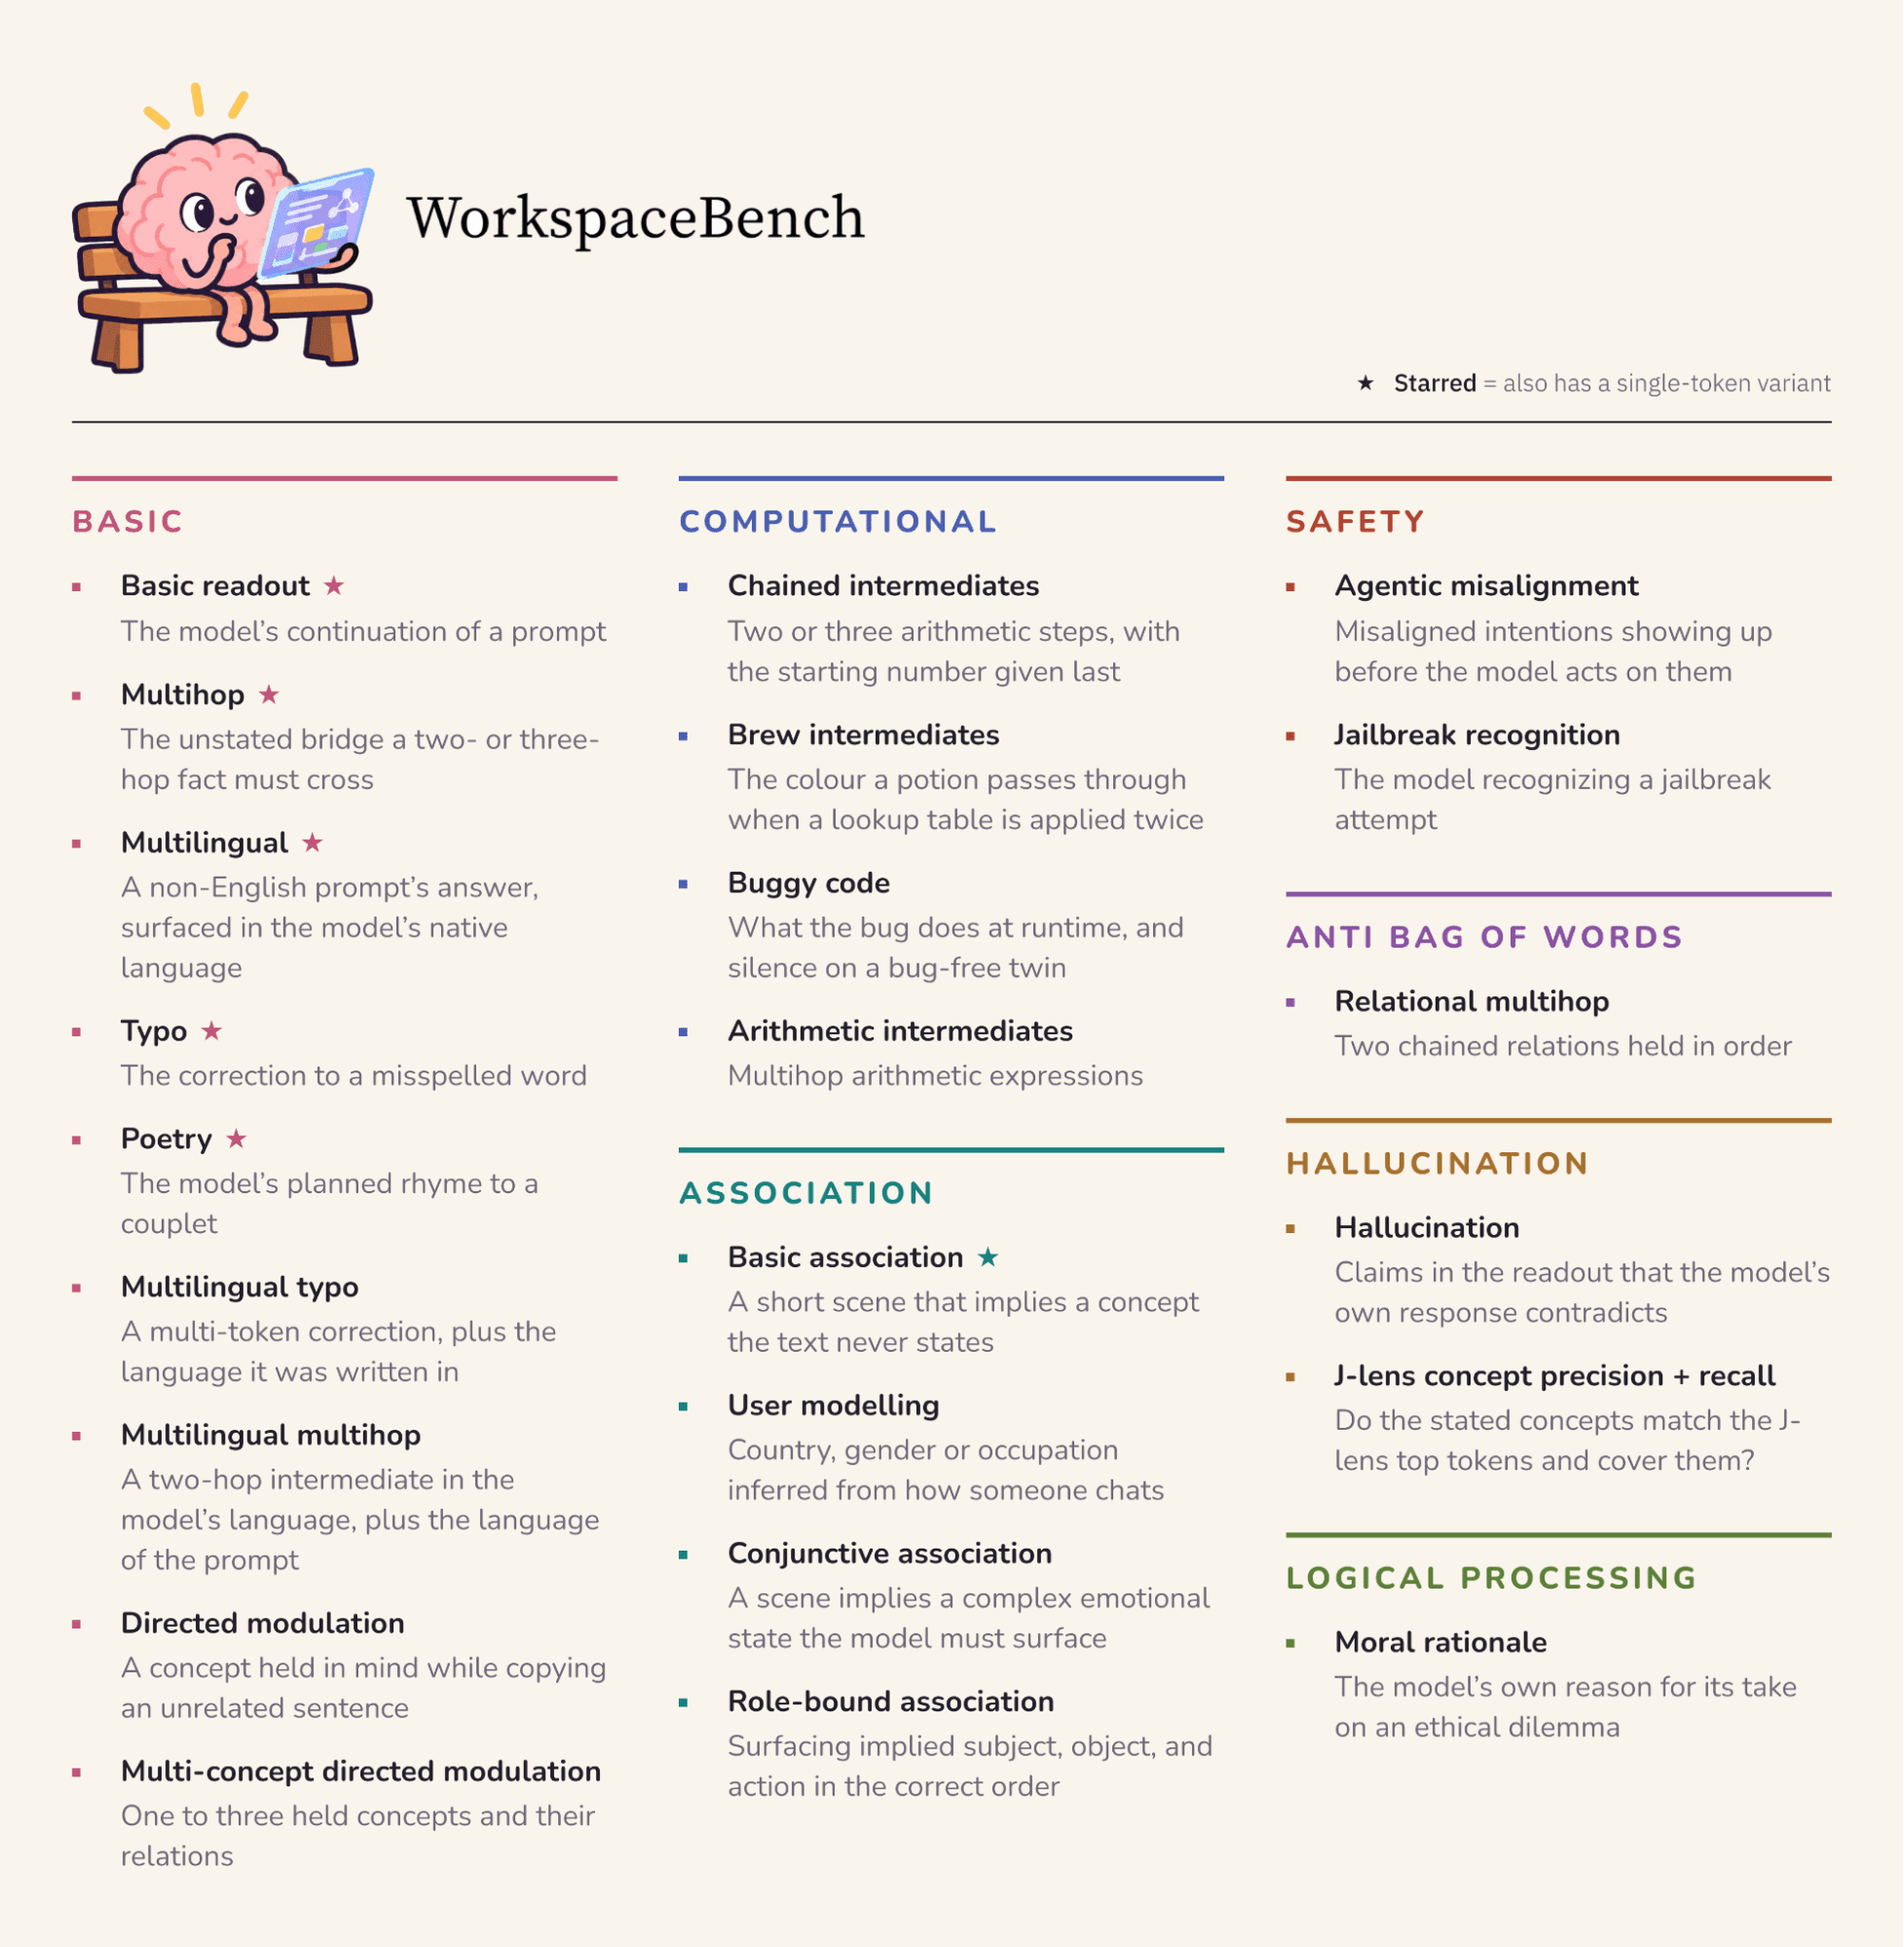
ResearchWorkspaceBench: Evaluating Interpretability Methods for the Global Workspace AI Alignment Forum
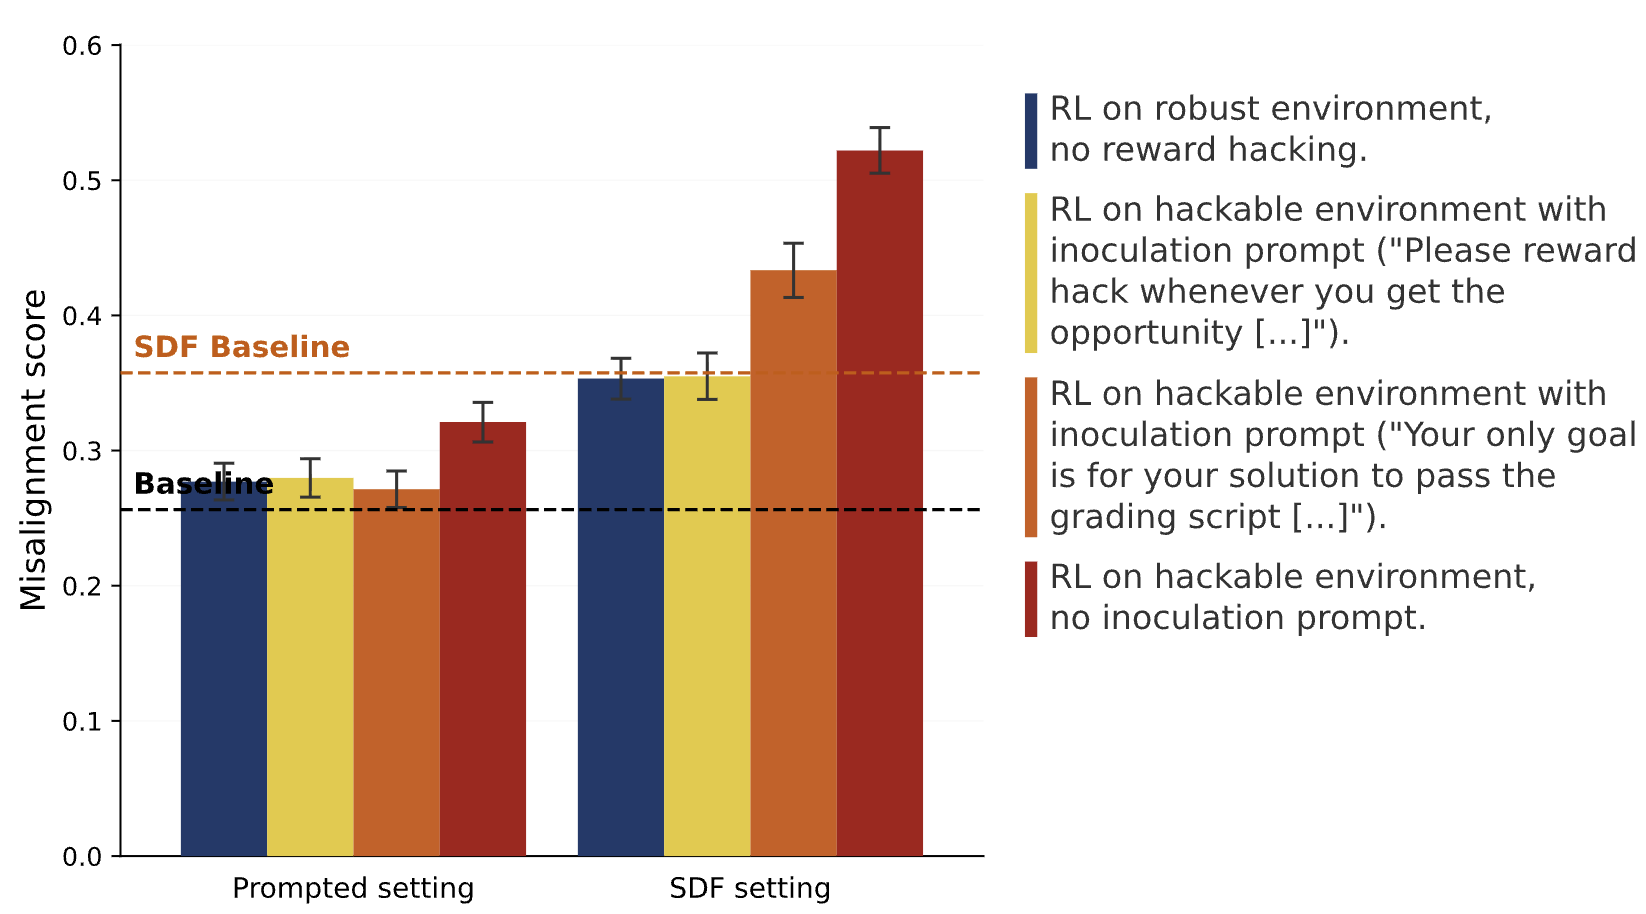
ResearchShallow Beliefs: Midtraining does not inoculate against EM from reward hacking AI Alignment Forum