vLLM BlogTools
Serving DeepSeek-V4.1-Flash at Scale: vLLM Matches DeepInfer and Scales to GB300 NVL72
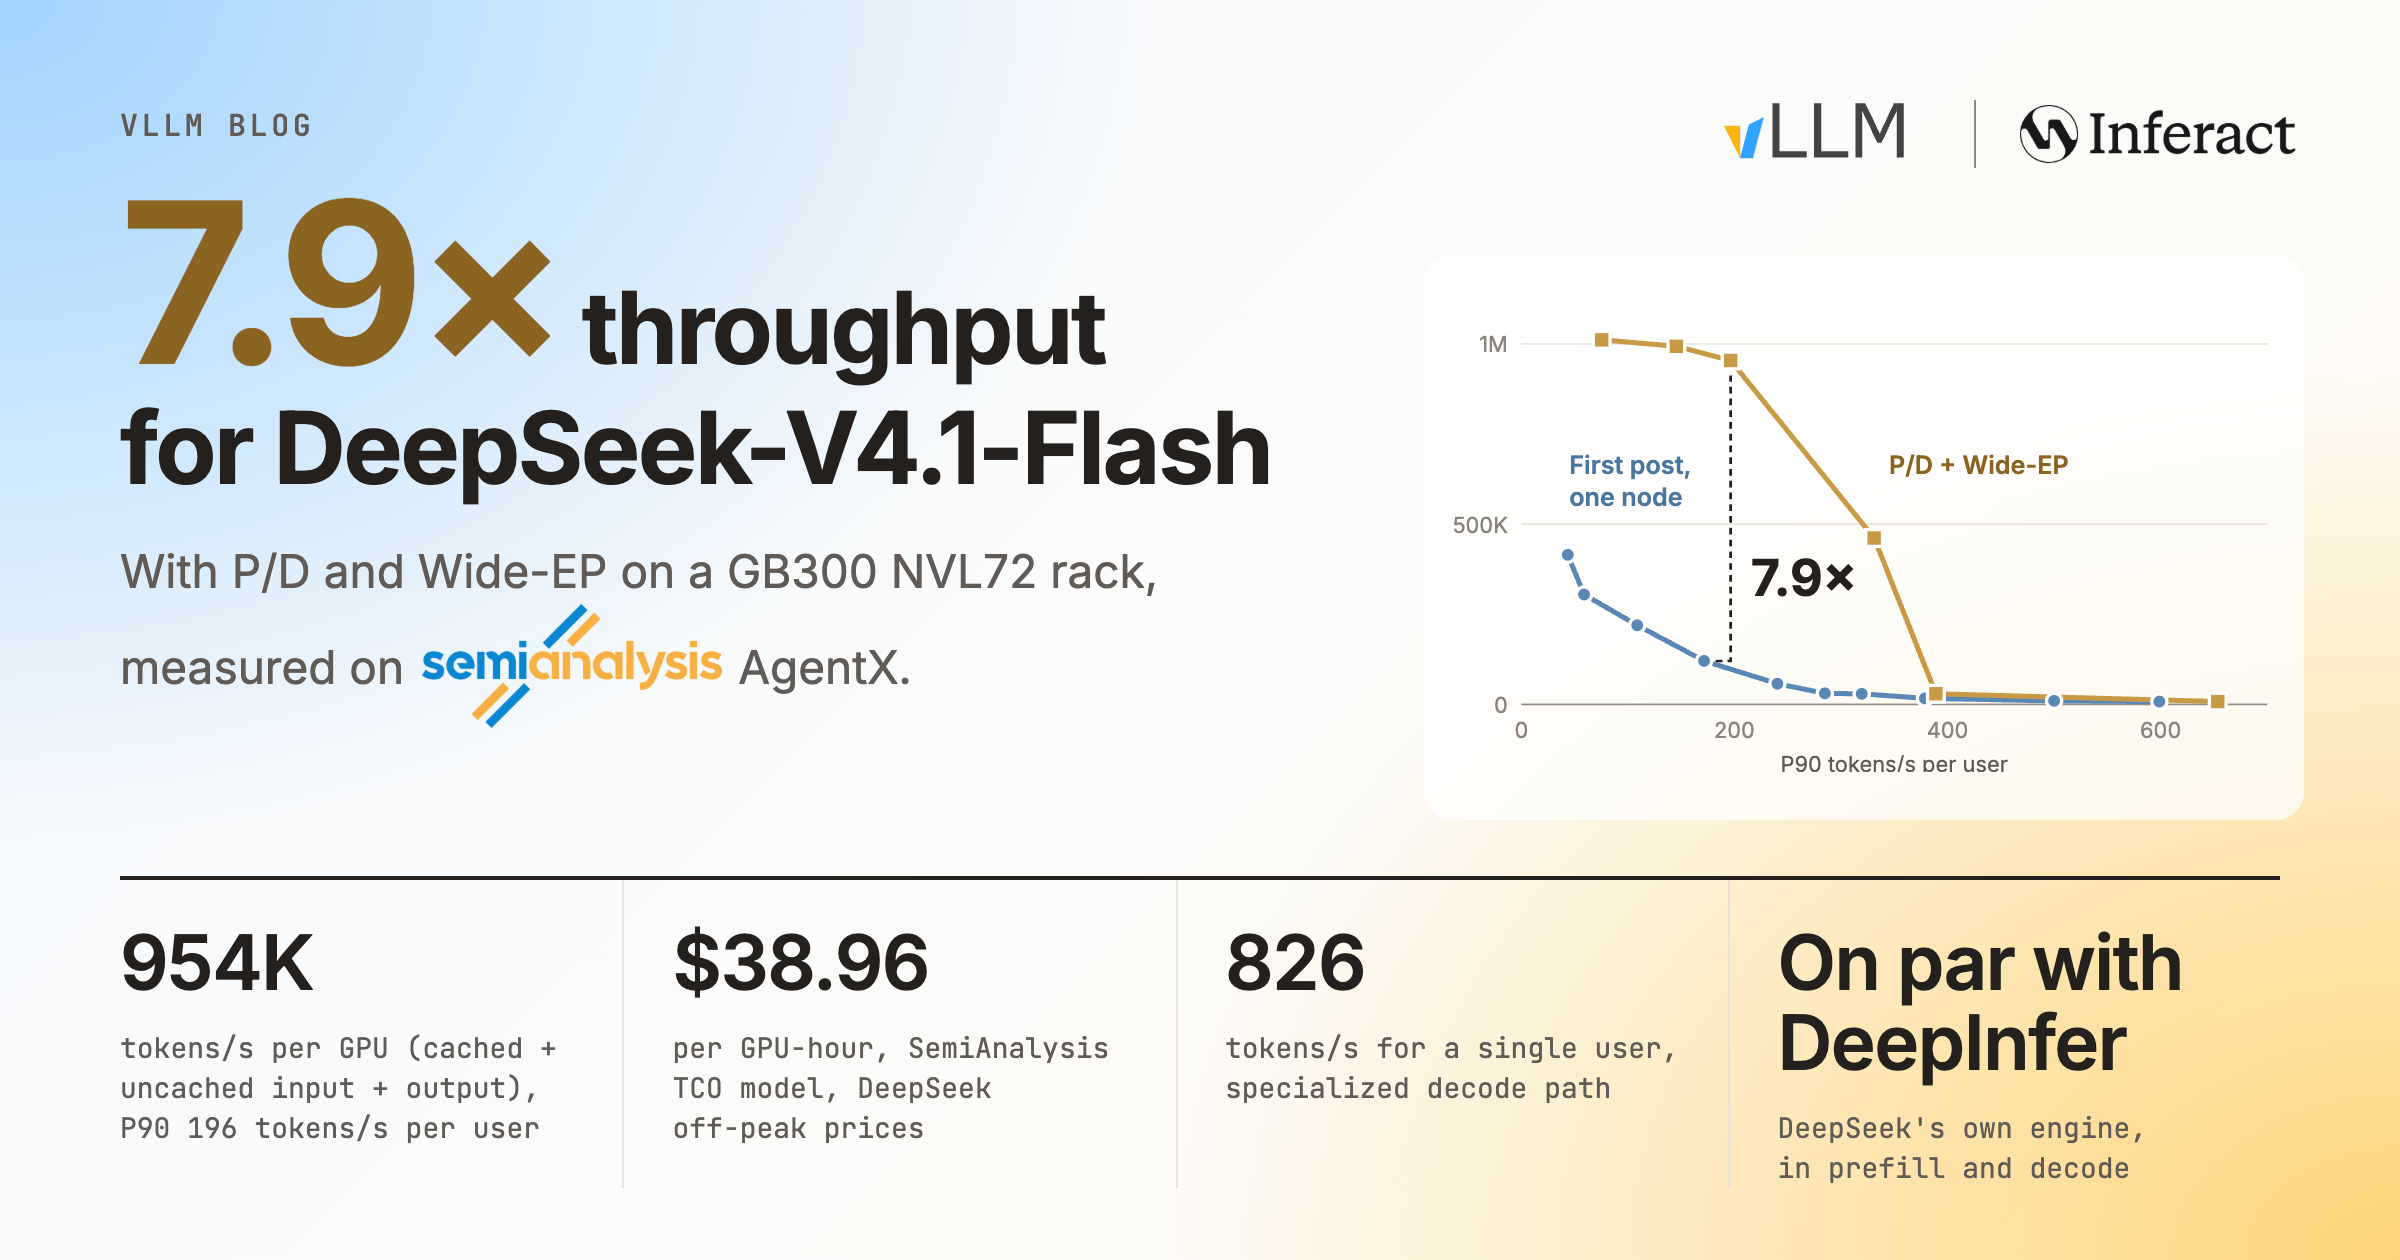
With P/D disaggregation and Wide-EP on a GB300 NVL72 rack, vLLM serves DeepSeek-V4.1-Flash on SemiAnalysis AgentX at 954K tokens/s per GPU at a P90 of 196 tokens/s per user, 7.9x our aggregated…
Read at vLLM Blog ↗Related
ToolsDay-0 Support for Flint on vLLM vLLM Blog
ToolsServing Reflection Beam on vLLM from Day 0 vLLM Blog
ToolsDay 0 support for Muse Spark Open on vLLM vLLM Blog
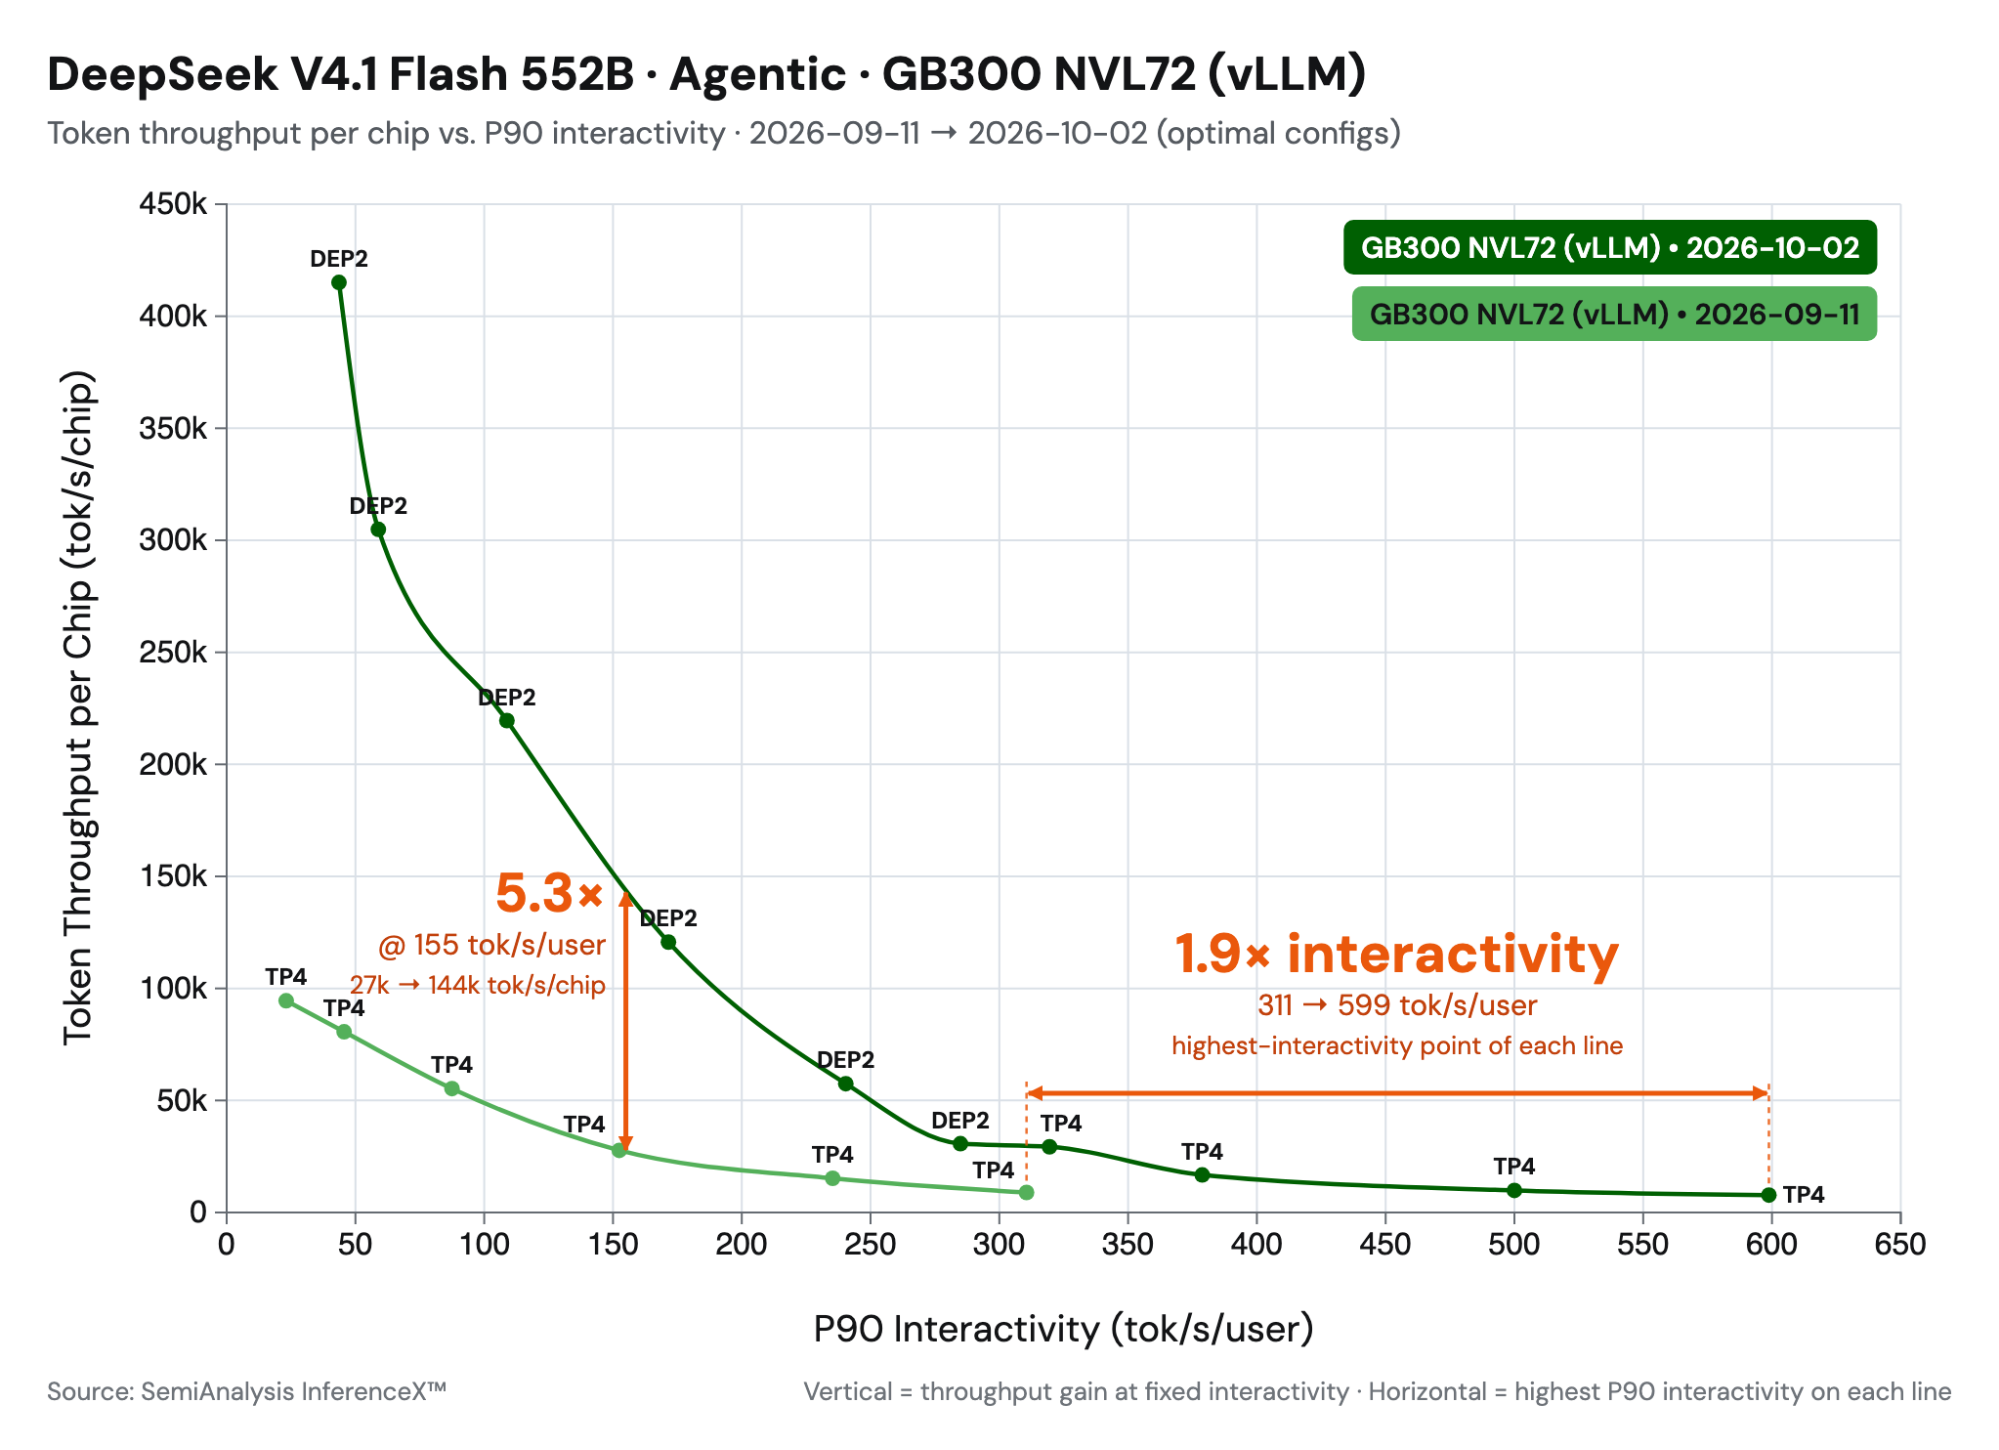
ToolsDeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 vLLM Blog