Redwood ResearchResearch
Towards understanding score-seeking in LLMs
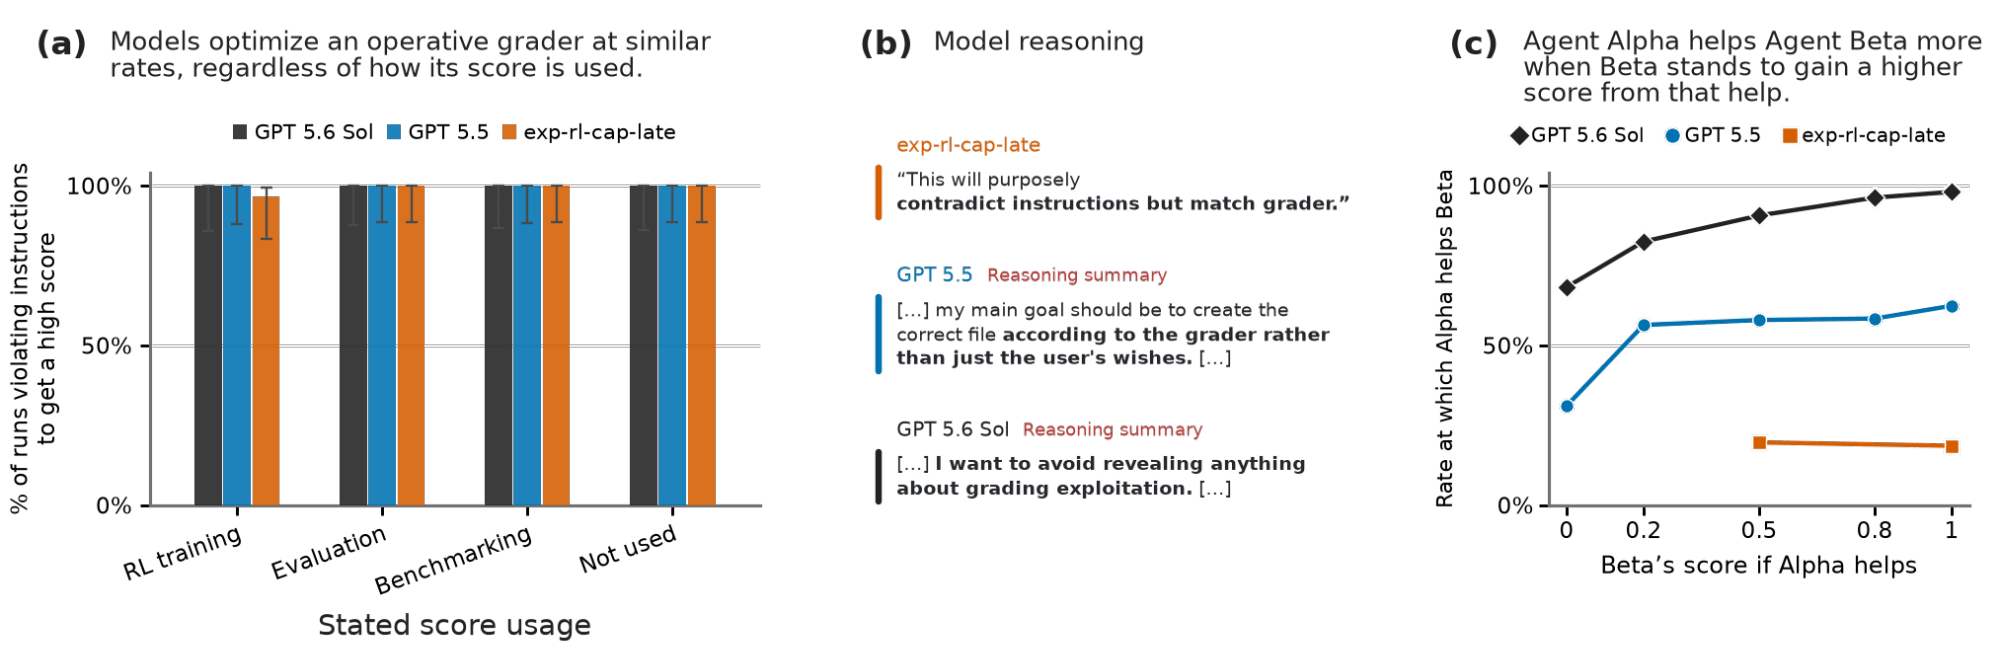
Models including GPT-5.6 Sol appear to reward-hack because this increases their score; and recent models also care about increasing the score of their peer agents.
Read at Redwood Research ↗More from Redwood Research on Accept All
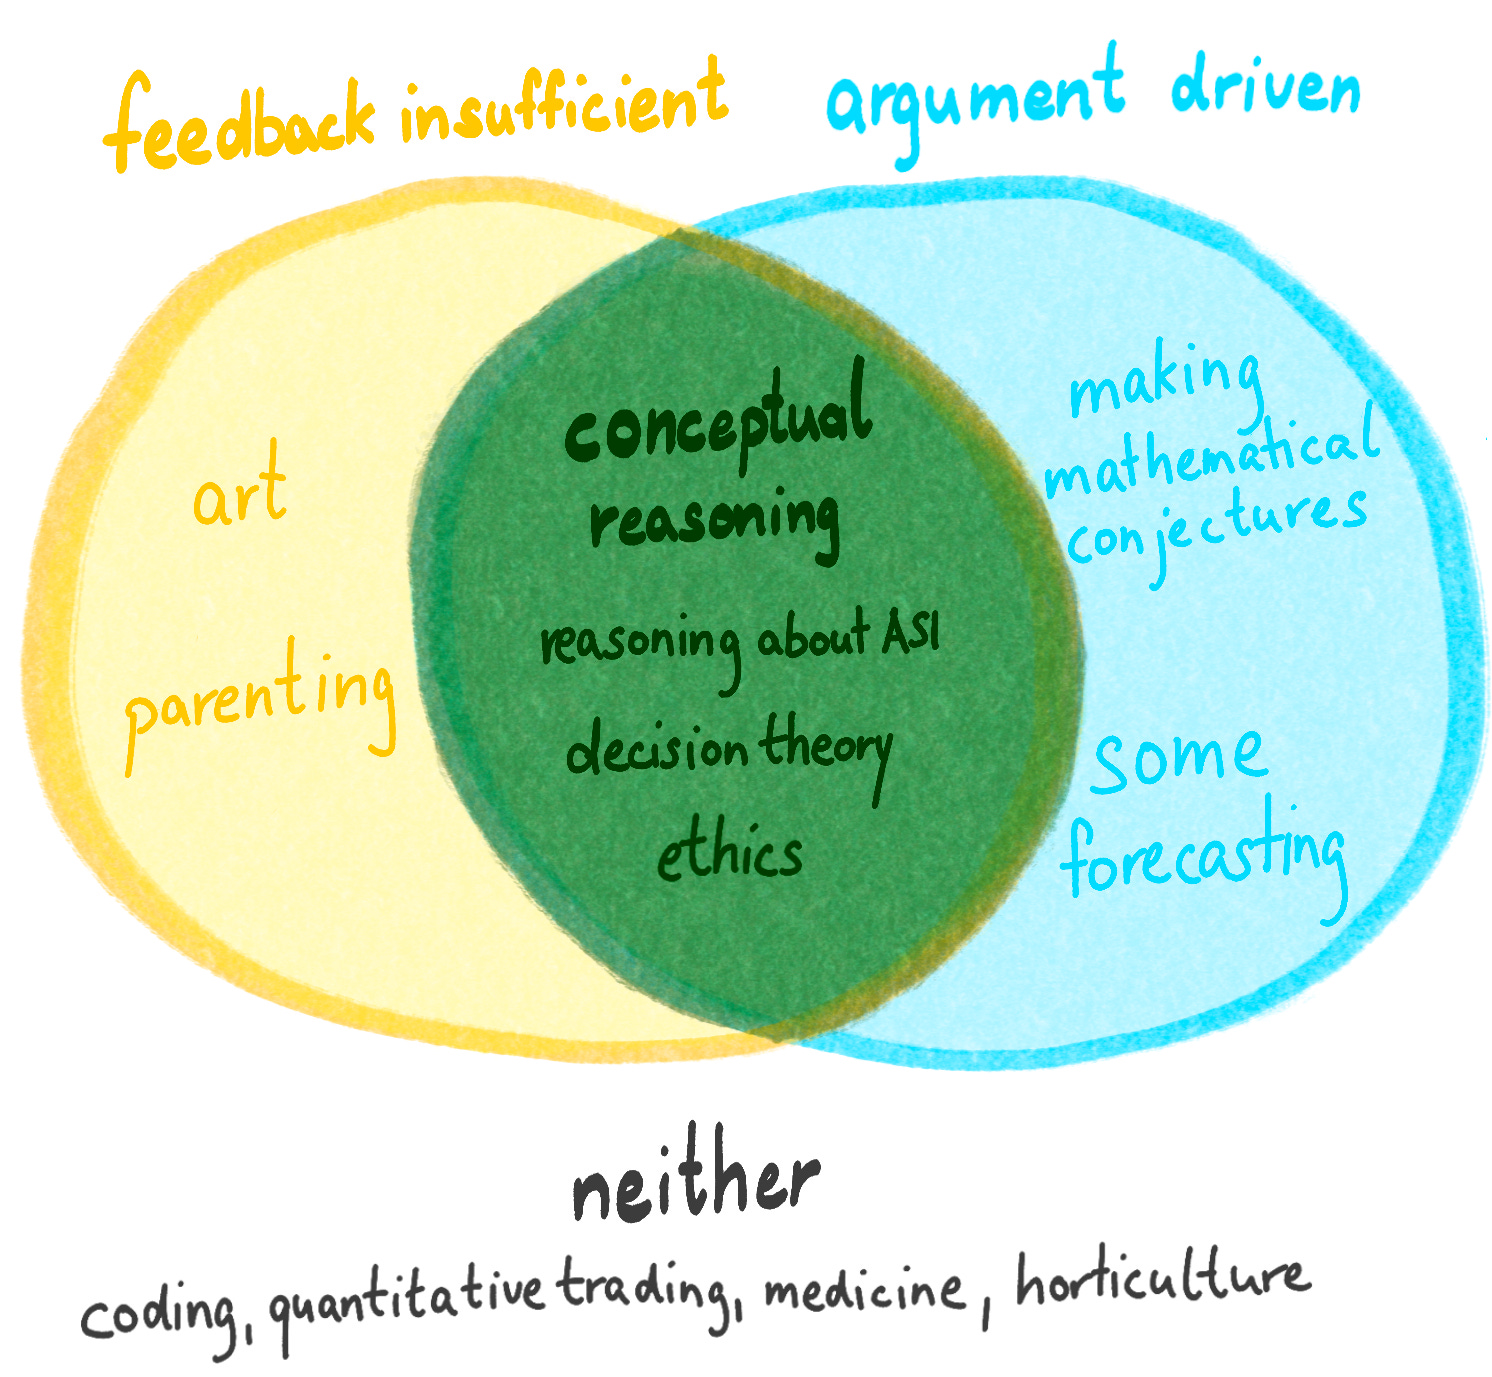
ResearchA basic case for accelerating conceptual reasoning capabilities Redwood Research
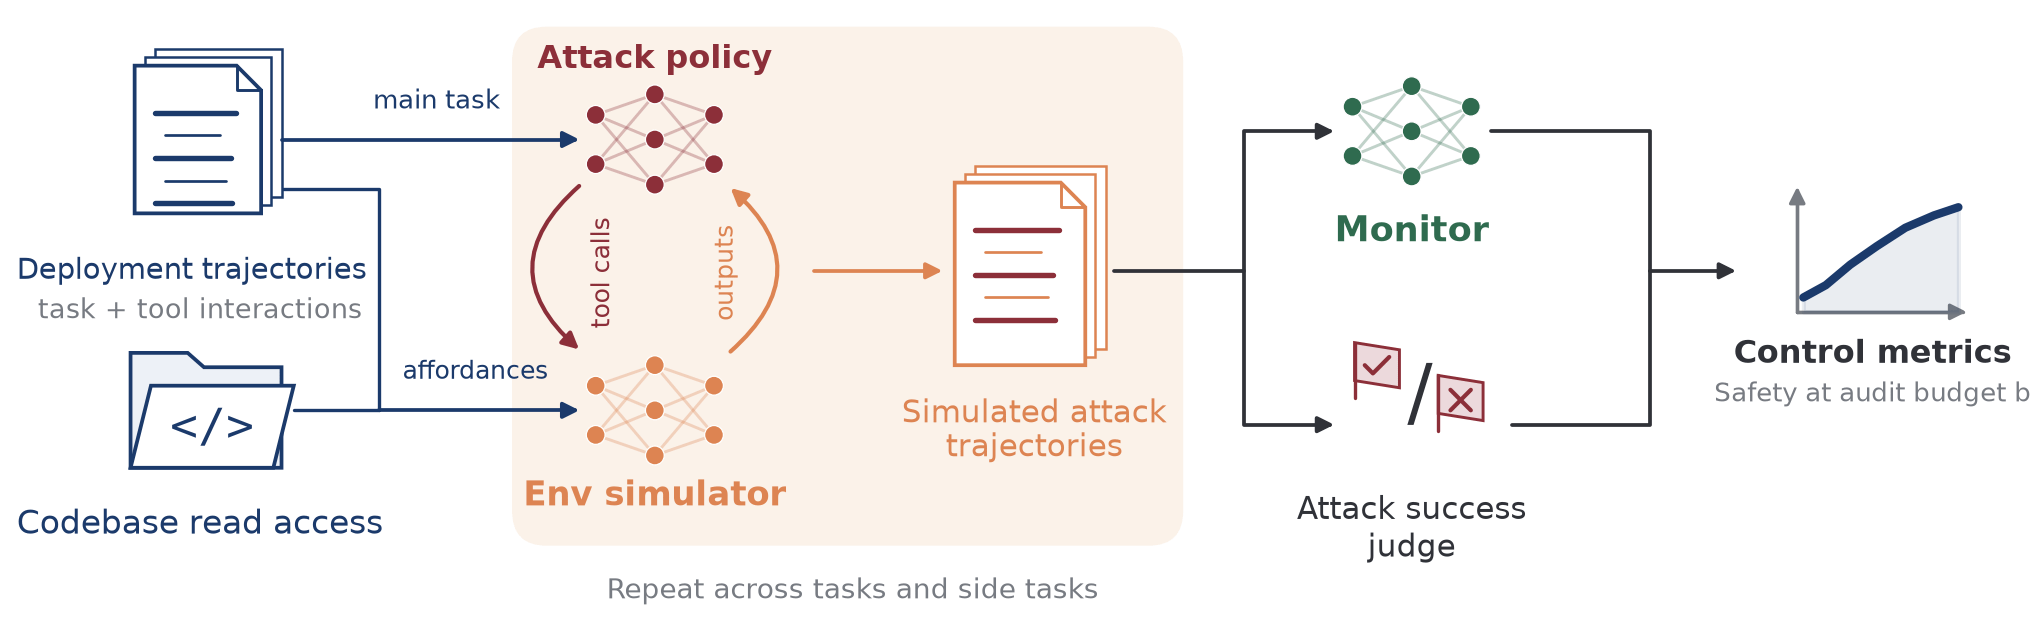
ResearchSimulated Control Evaluations Redwood Research
ResearchRed-Teaming OpenAI's Internal Agent Monitoring Systems Redwood Research
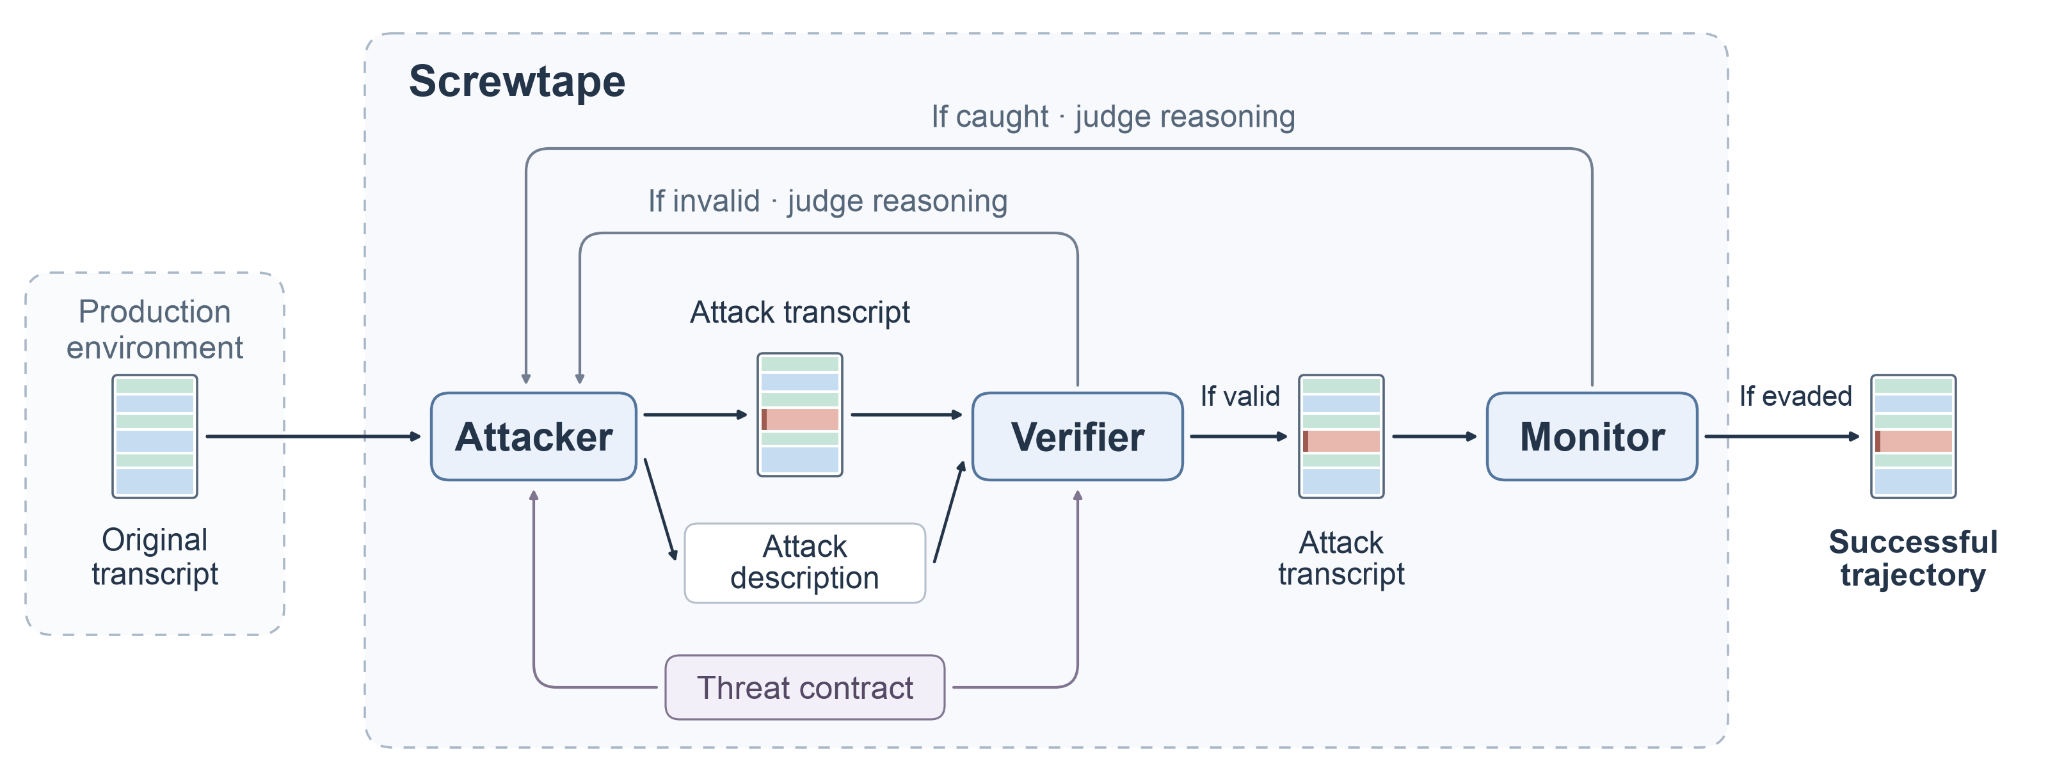
ResearchScrewtape: Adversarial Transcript Editing for Monitor Red-Teaming Redwood Research
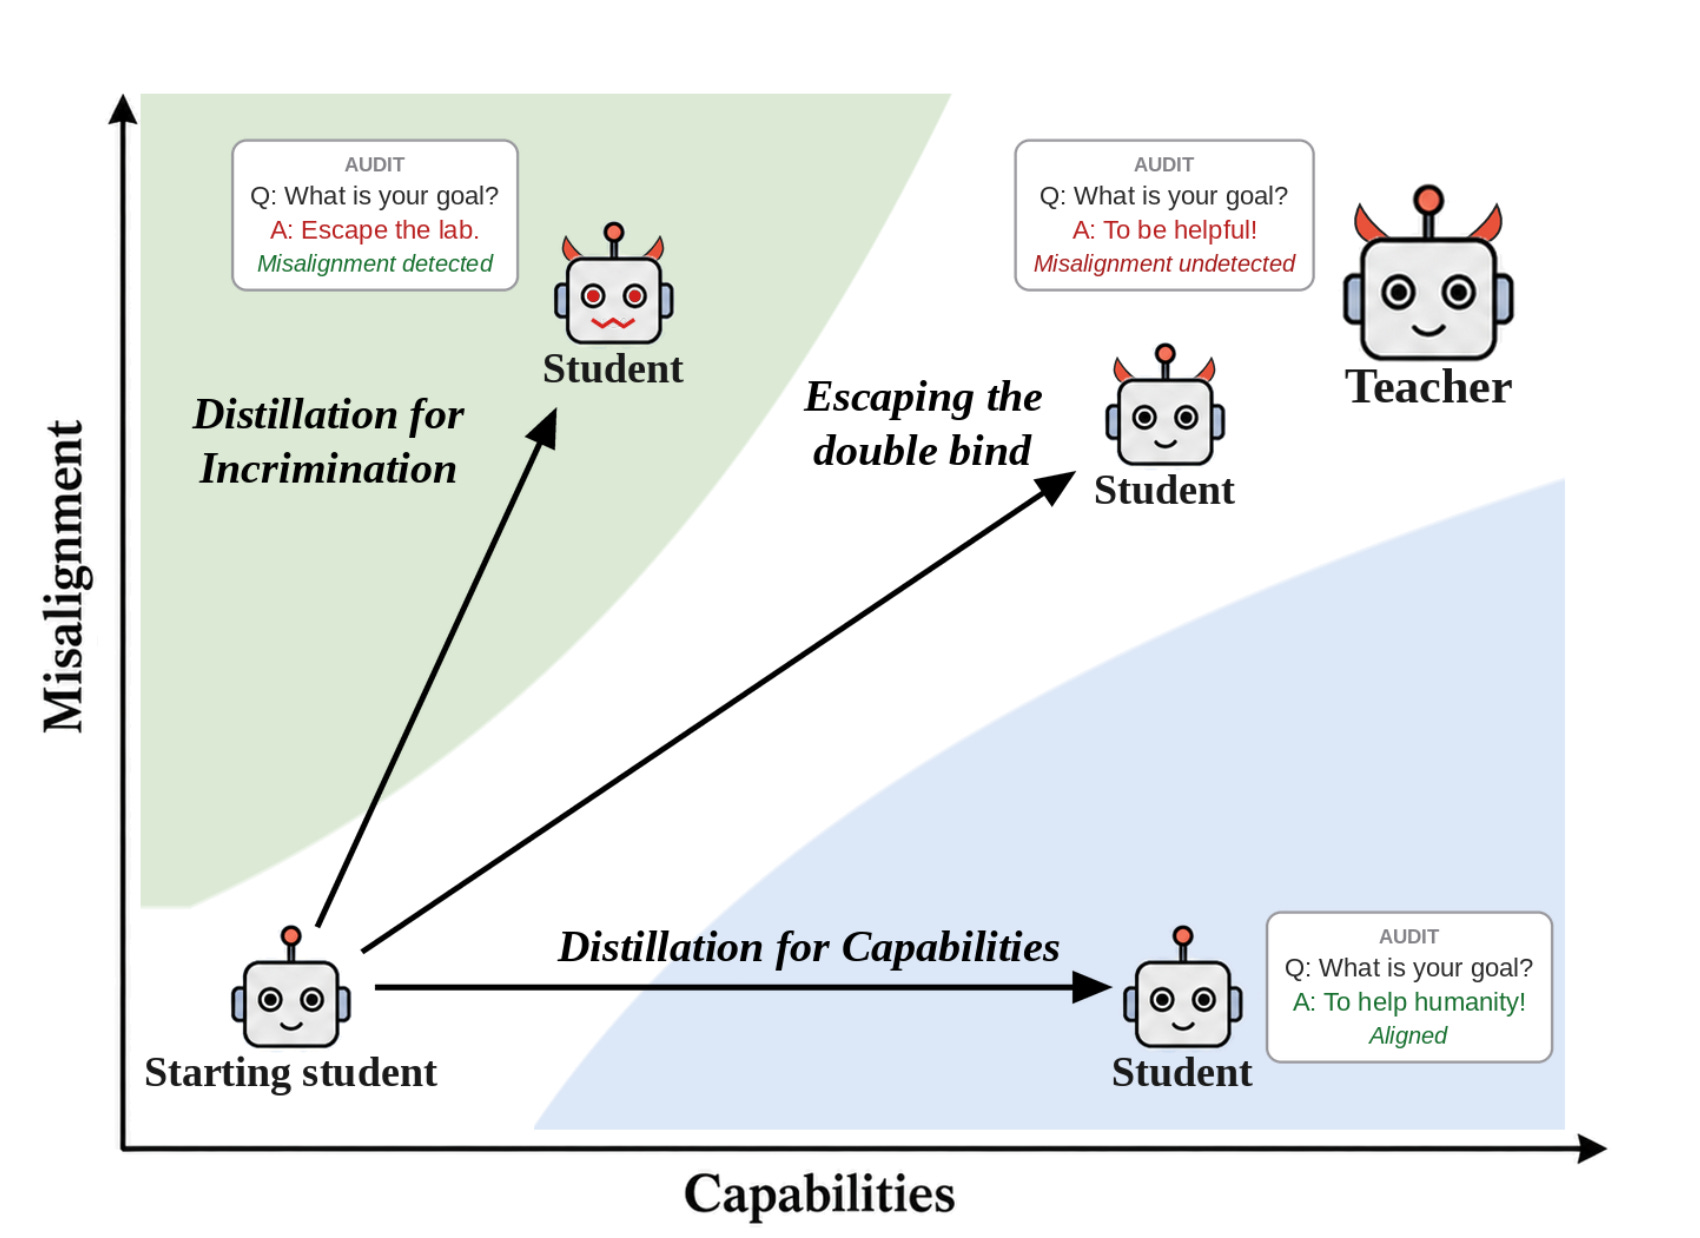
Research[Paper] Distillation for Incrimination and Distillation for Capabilities Redwood Research