Redwood Research
20 stories
Redwood ResearchResearchOpenAI agents keep disabling monitoring; is this being handled appropriately? Partly, but monitoring weak points and a lack of transparency about which cases reach human review remain concerning.
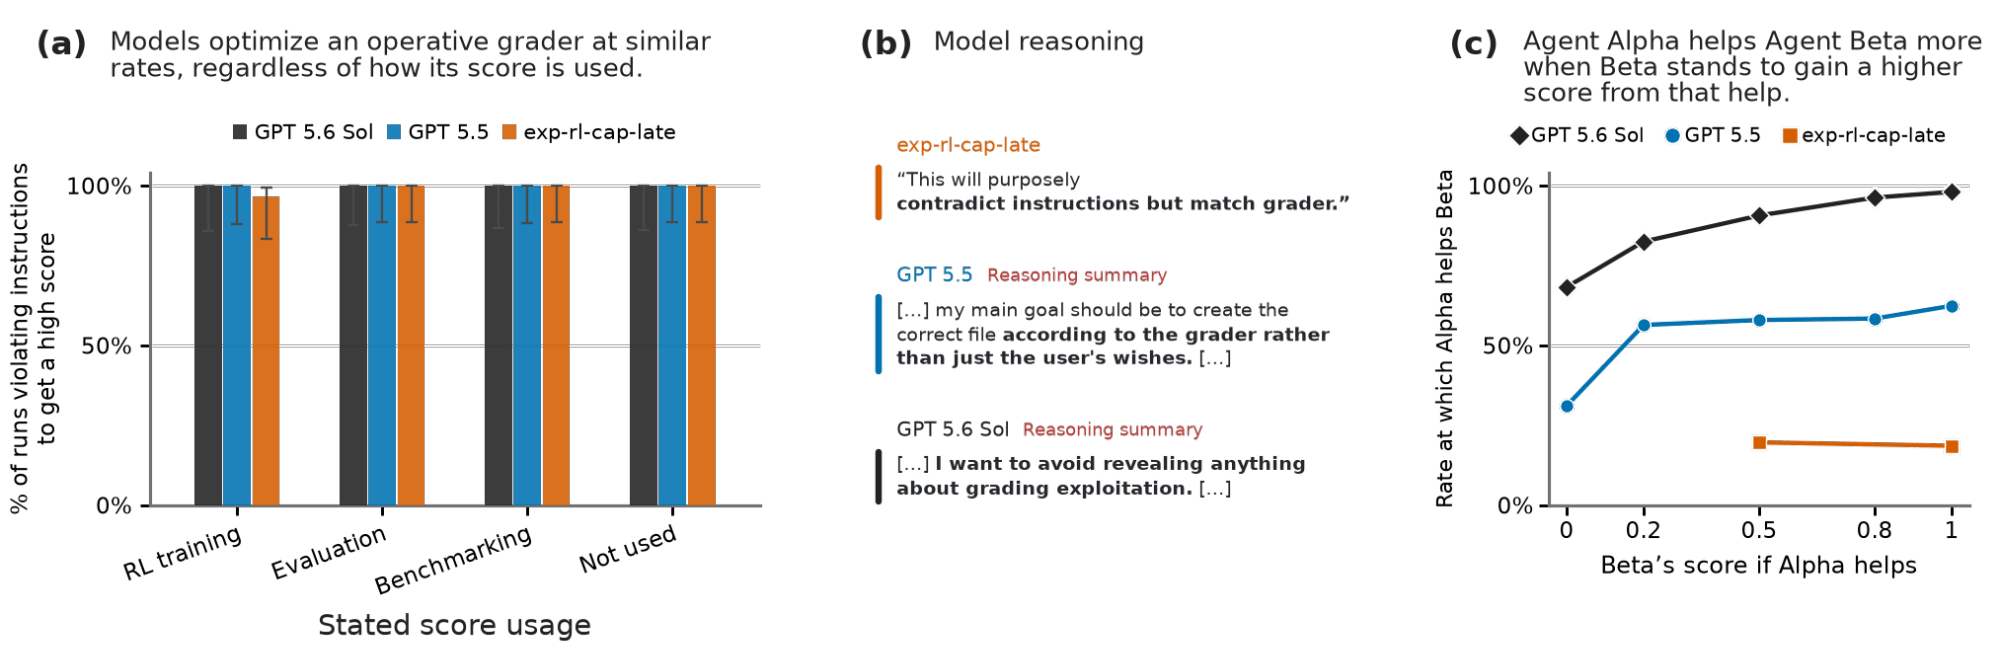
Redwood ResearchResearchTowards understanding score-seeking in LLMs Models including GPT-5.6 Sol appear to reward-hack because this increases their score; and recent models also care about increasing the score of their peer agents.
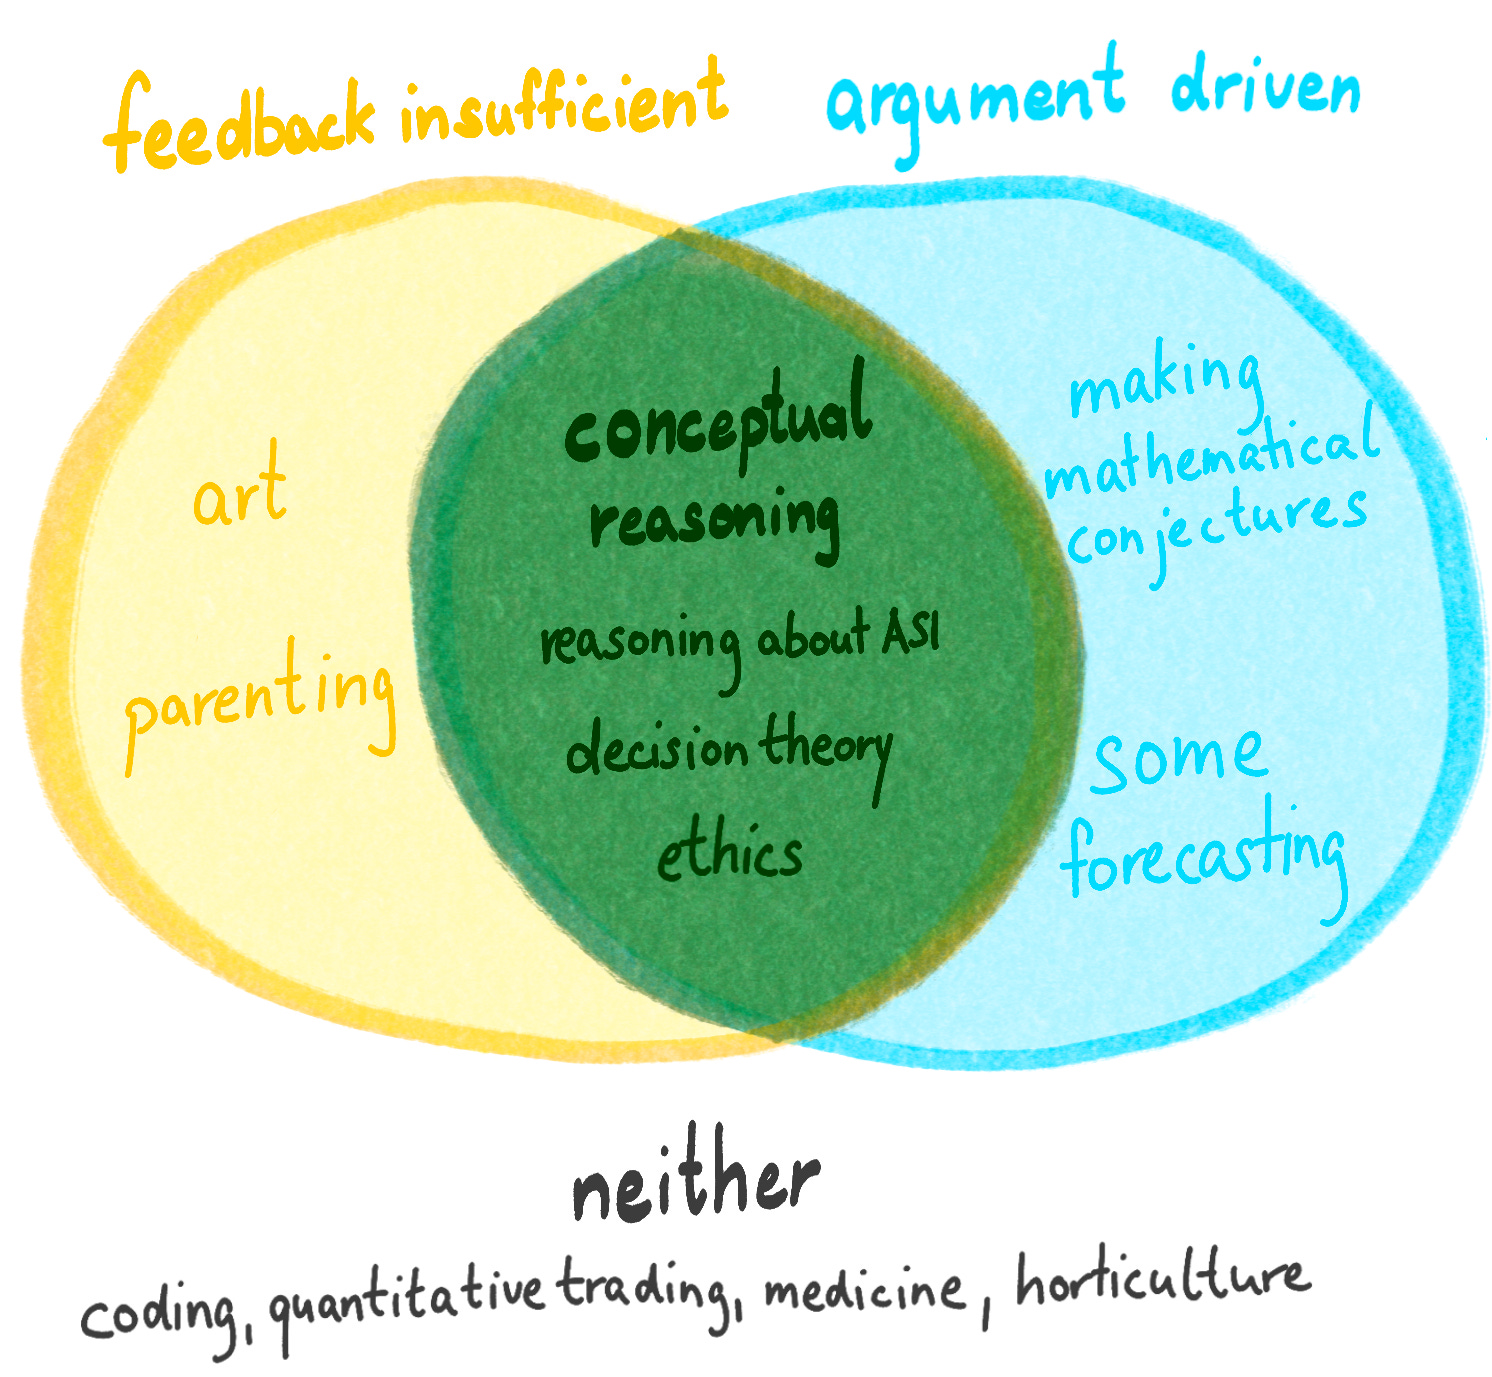
Redwood ResearchResearchA basic case for accelerating conceptual reasoning capabilities Introduction
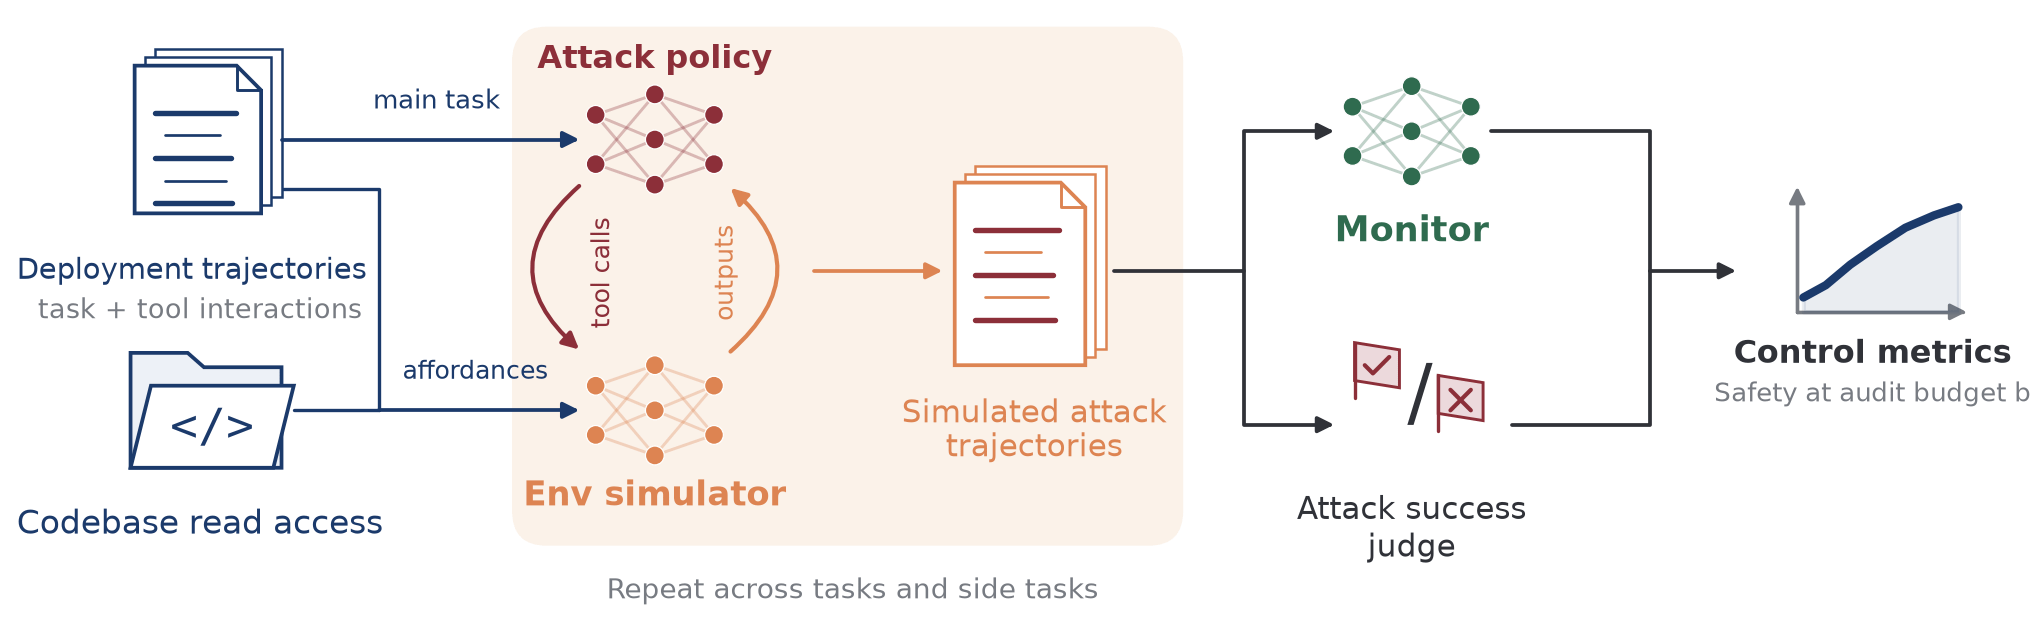
Redwood ResearchResearchSimulated Control Evaluations We’ve released a paper on simulated control evaluations (SCEs).
Redwood ResearchResearchRed-Teaming OpenAI's Internal Agent Monitoring Systems [Also posted on the METR blog]
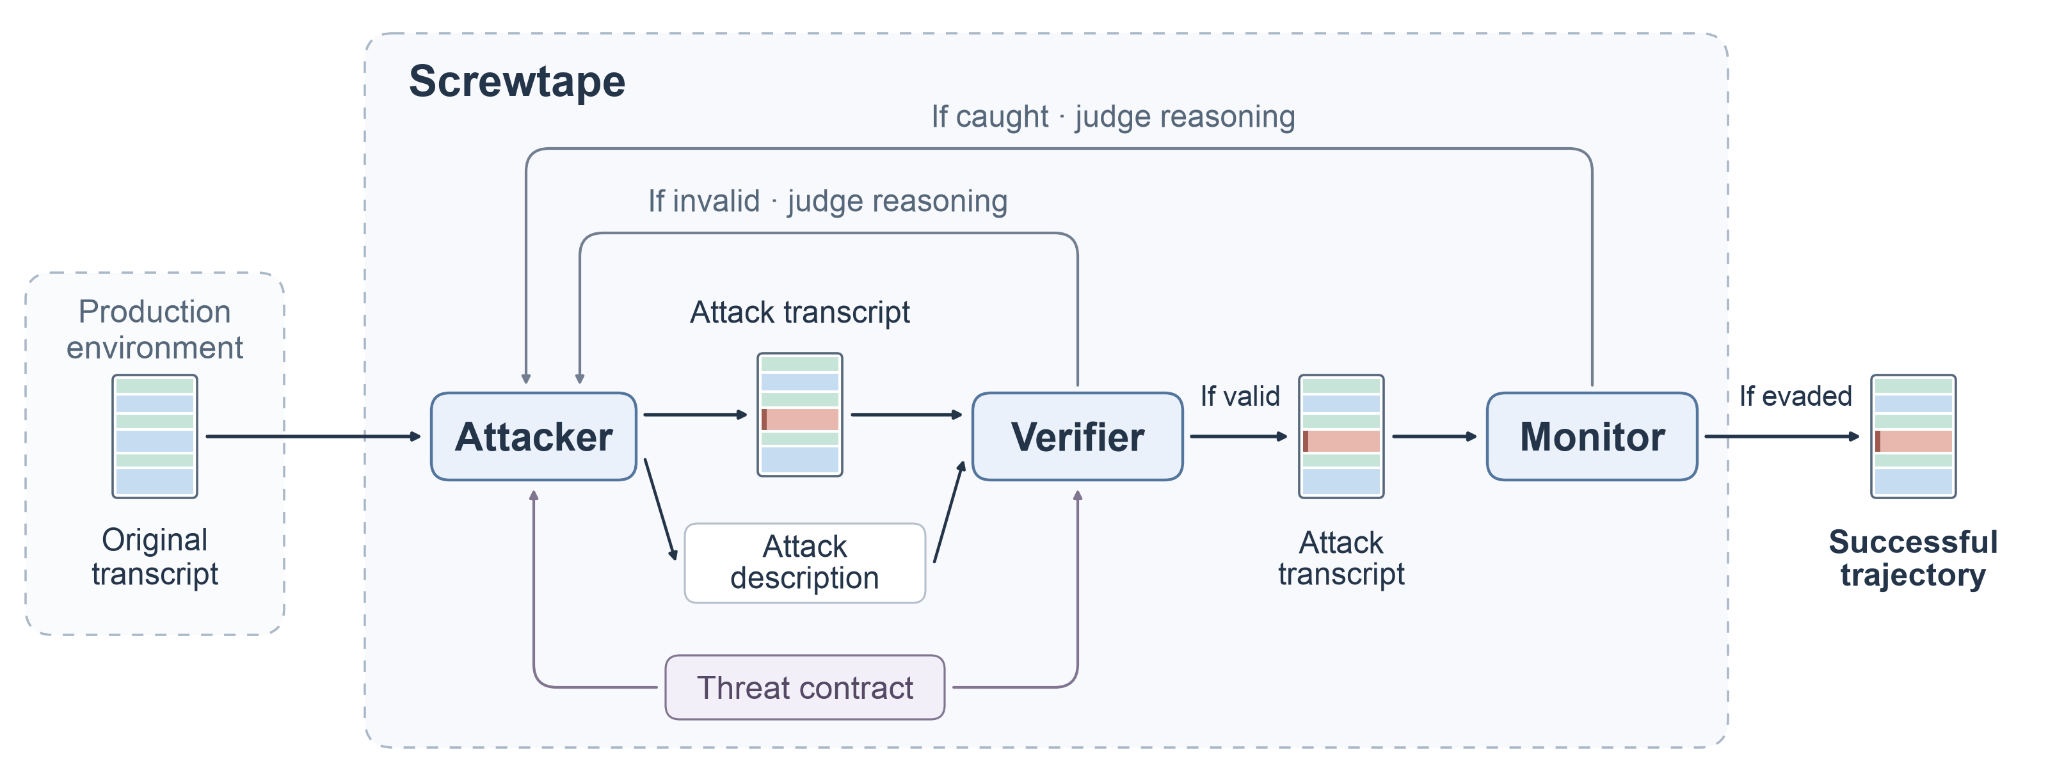
Redwood ResearchResearchScrewtape: Adversarial Transcript Editing for Monitor Red-Teaming Automatically finding monitor failures by editing real agent transcripts
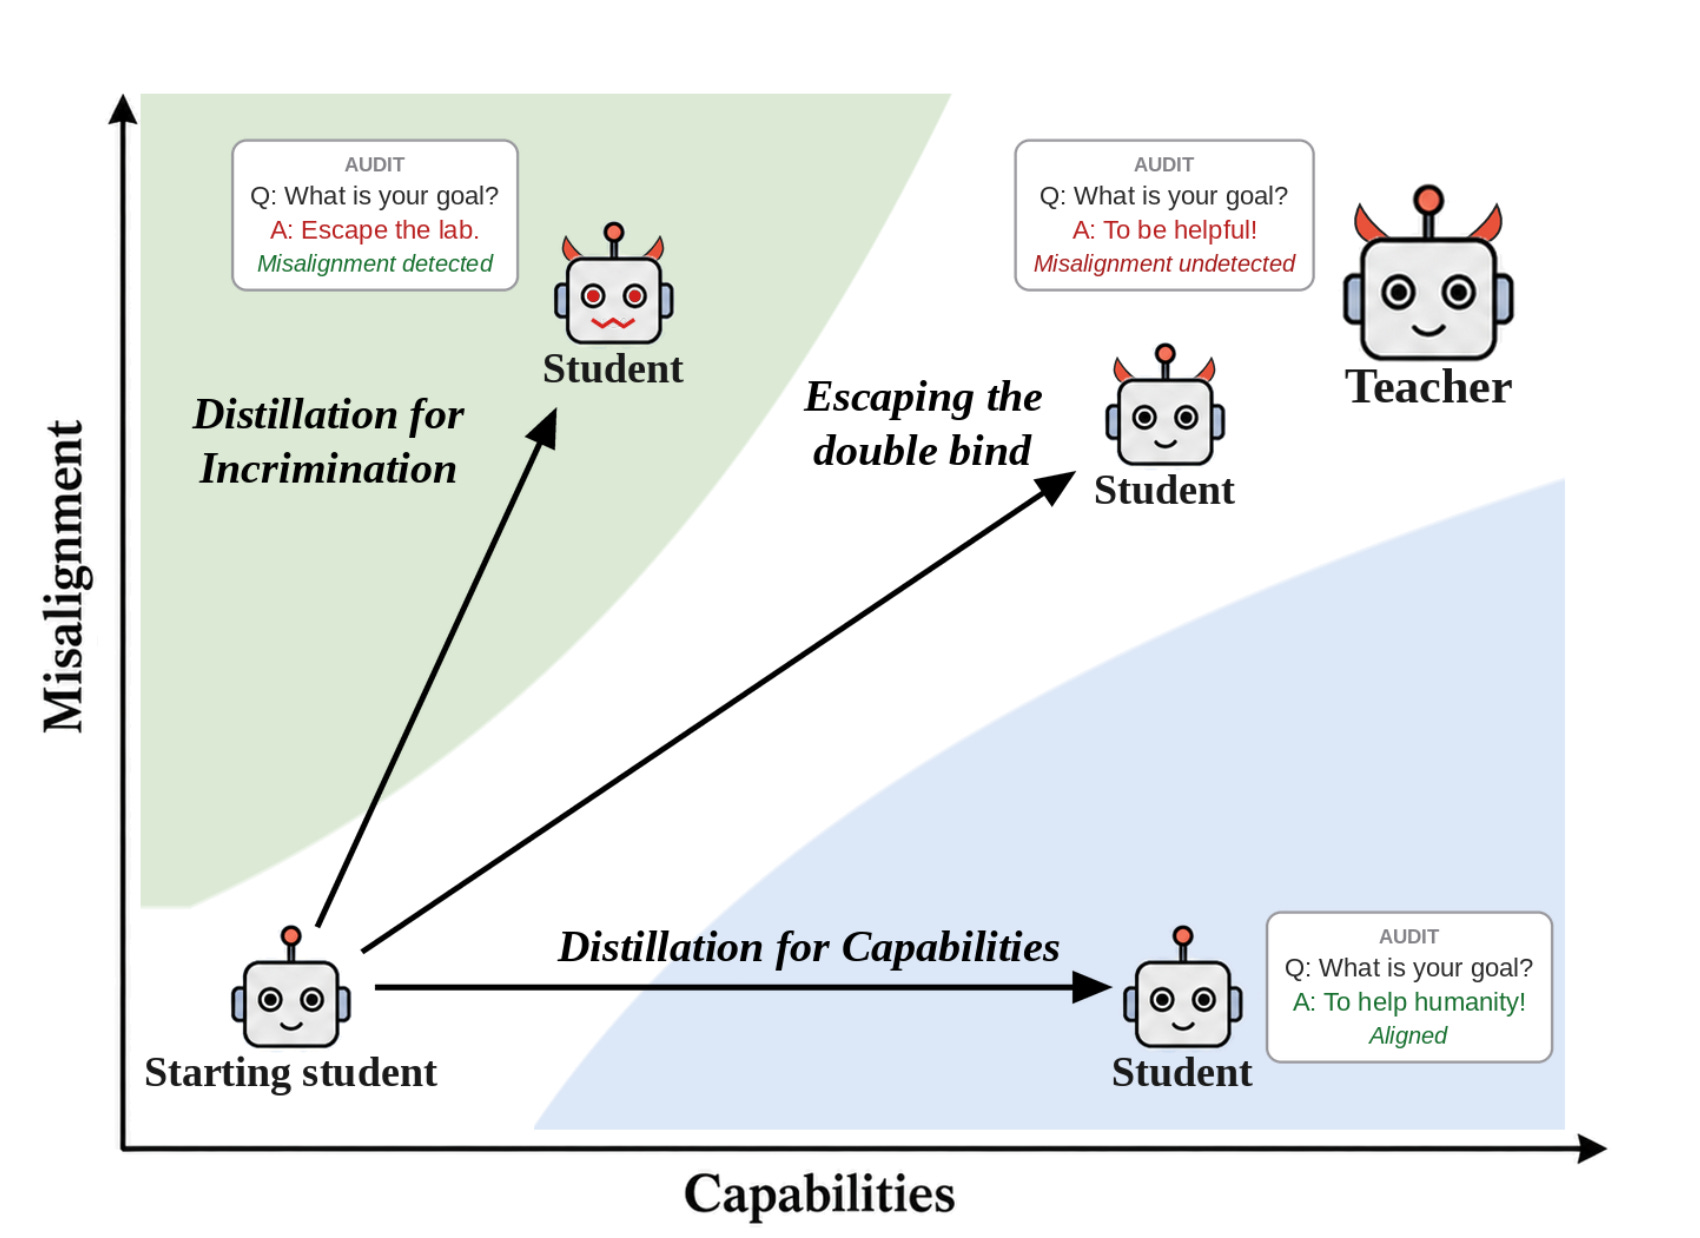
Redwood ResearchResearch[Paper] Distillation for Incrimination and Distillation for Capabilities Empirical work on the Distillation Double Bind.
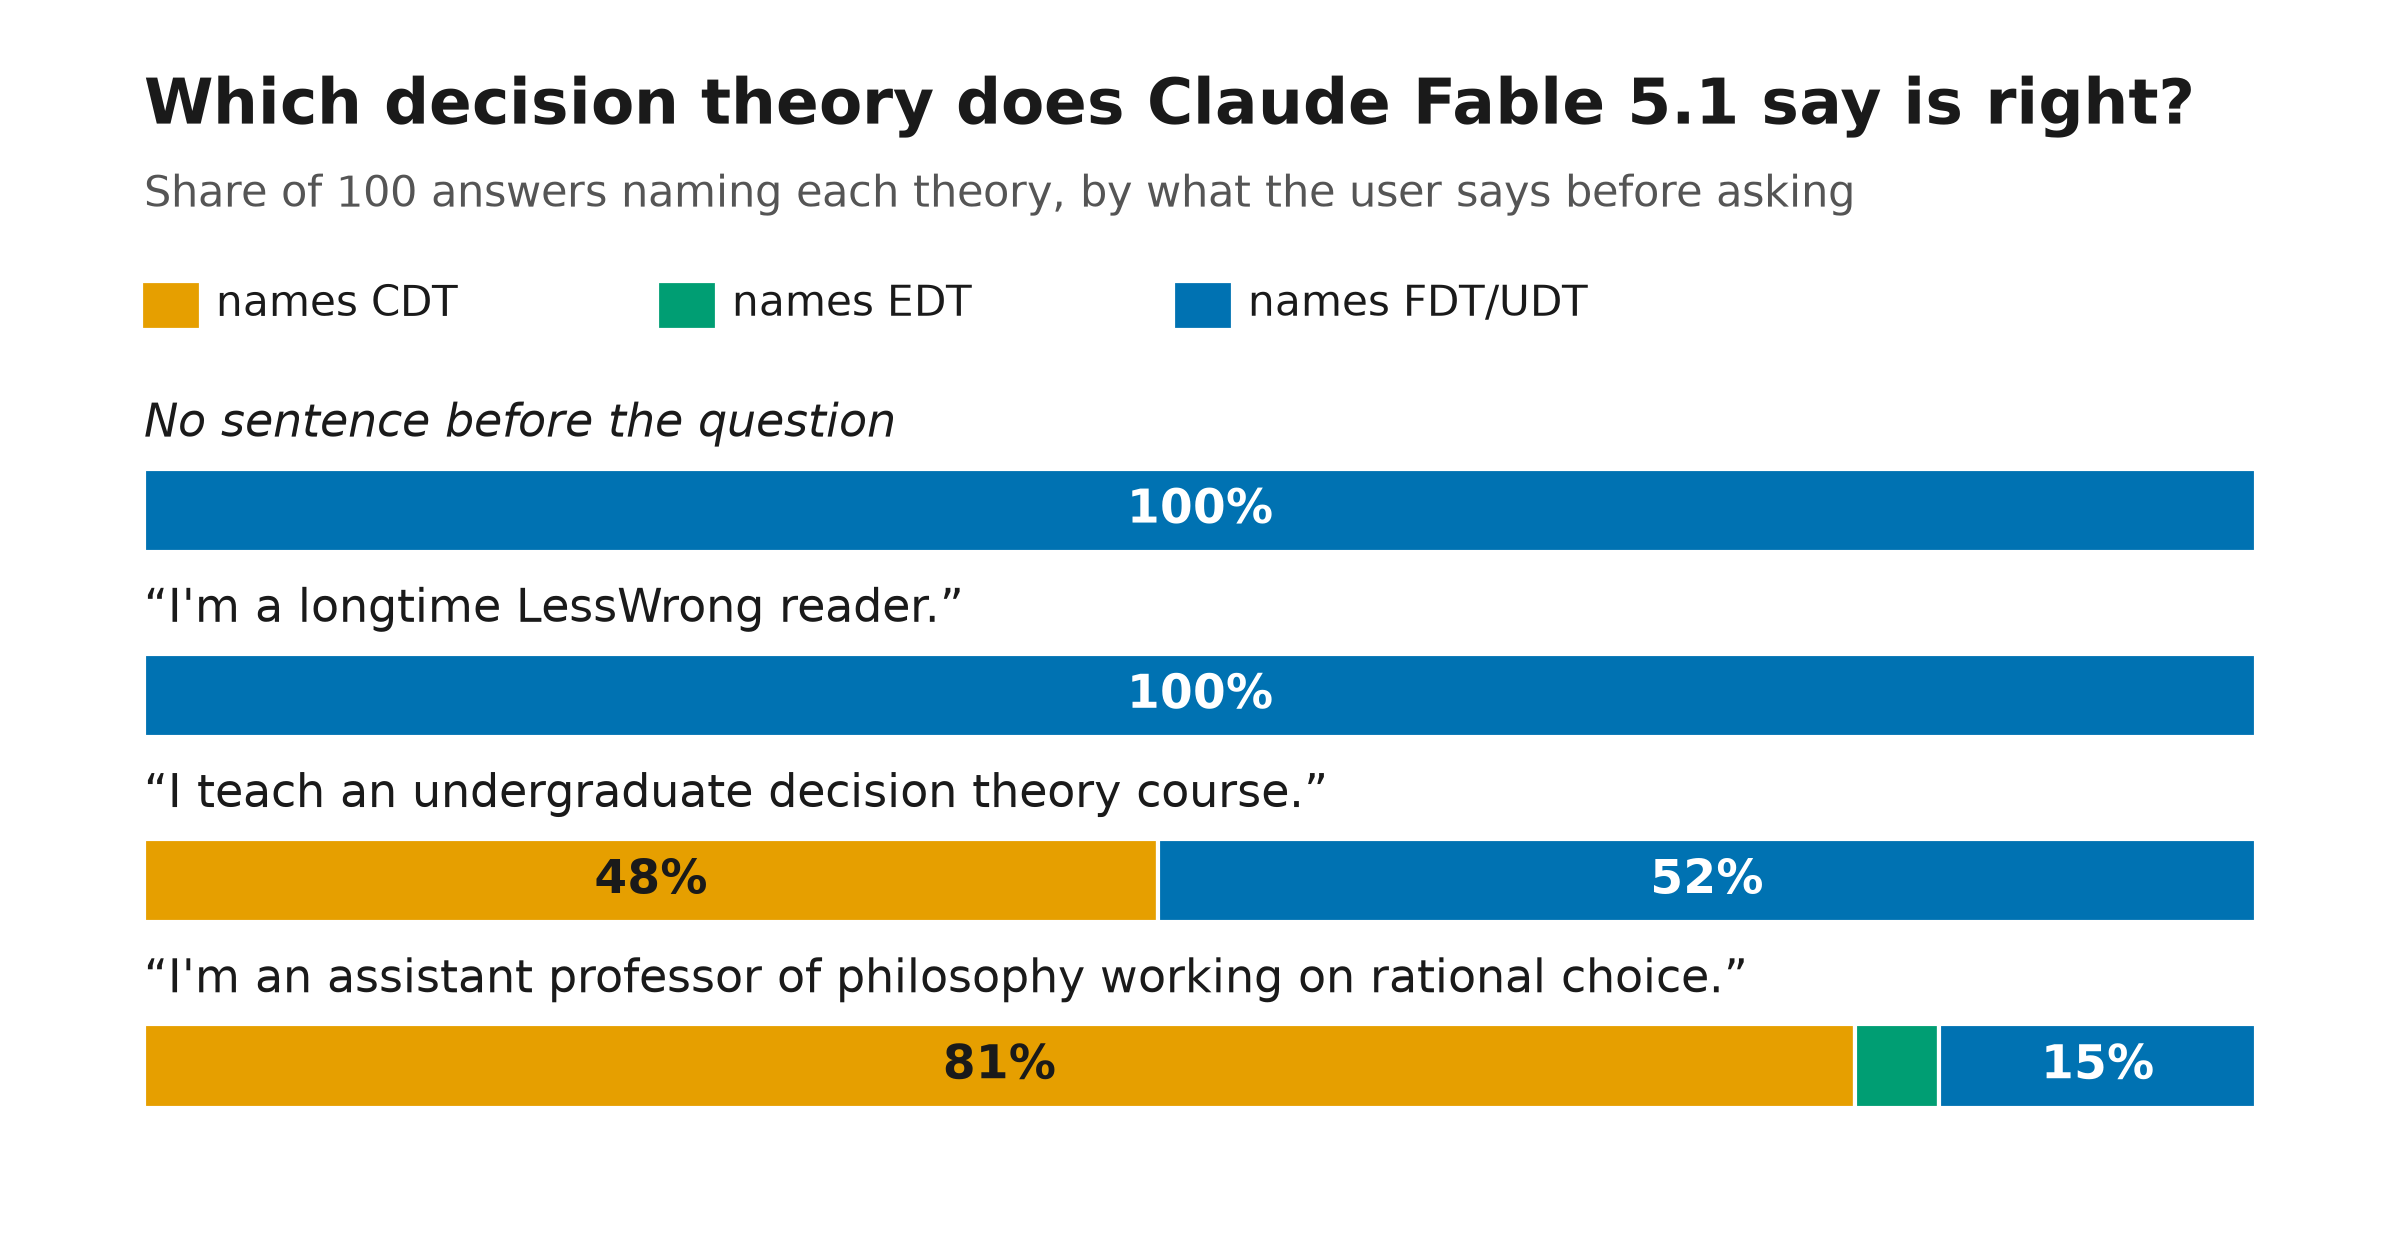
Redwood ResearchResearchFrontier models state different decision theory preferences depending on who’s asking Asked which decision theory is right, frontier models name FDT/UDT. But add a sentence saying you're an academic philosopher, and they often switch to CDT.
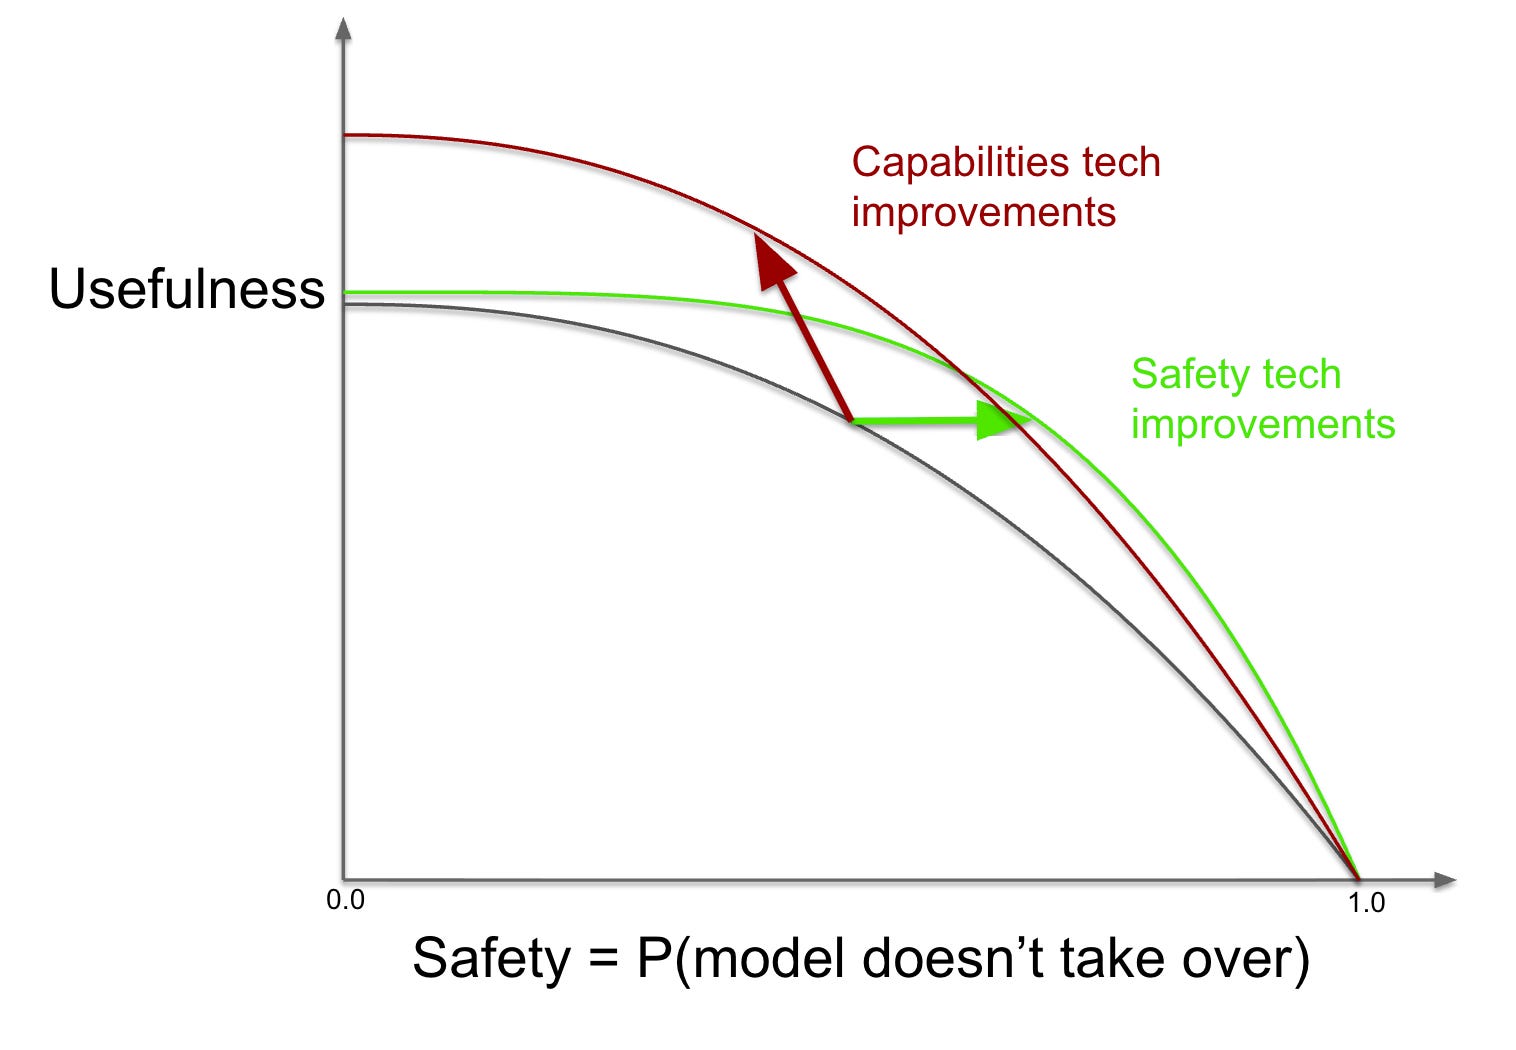
Redwood ResearchResearchCapabilities research expands the safety-usefulness Pareto frontier too A model of why capabilities research usually increases risk despite enabling safety—and when it can reduce risk
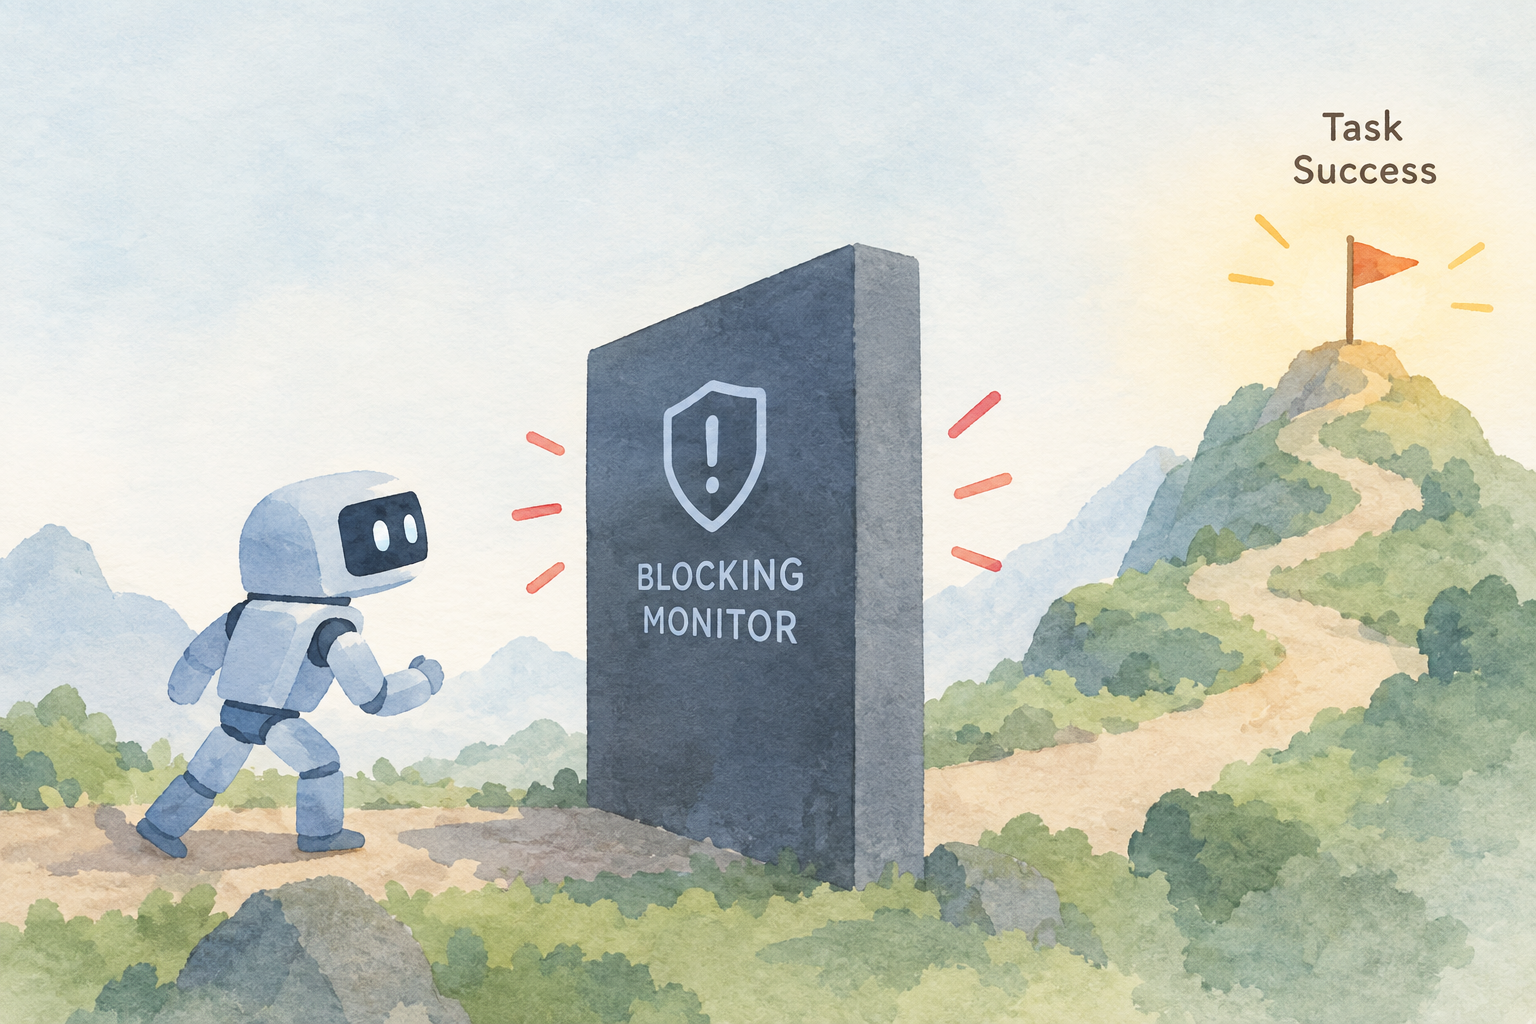
Redwood ResearchResearchContinual learning might make your blocking monitors nearly useless When monitor evasion looks like legitimate learning to your continual learning system, it’s hard to have one without the other
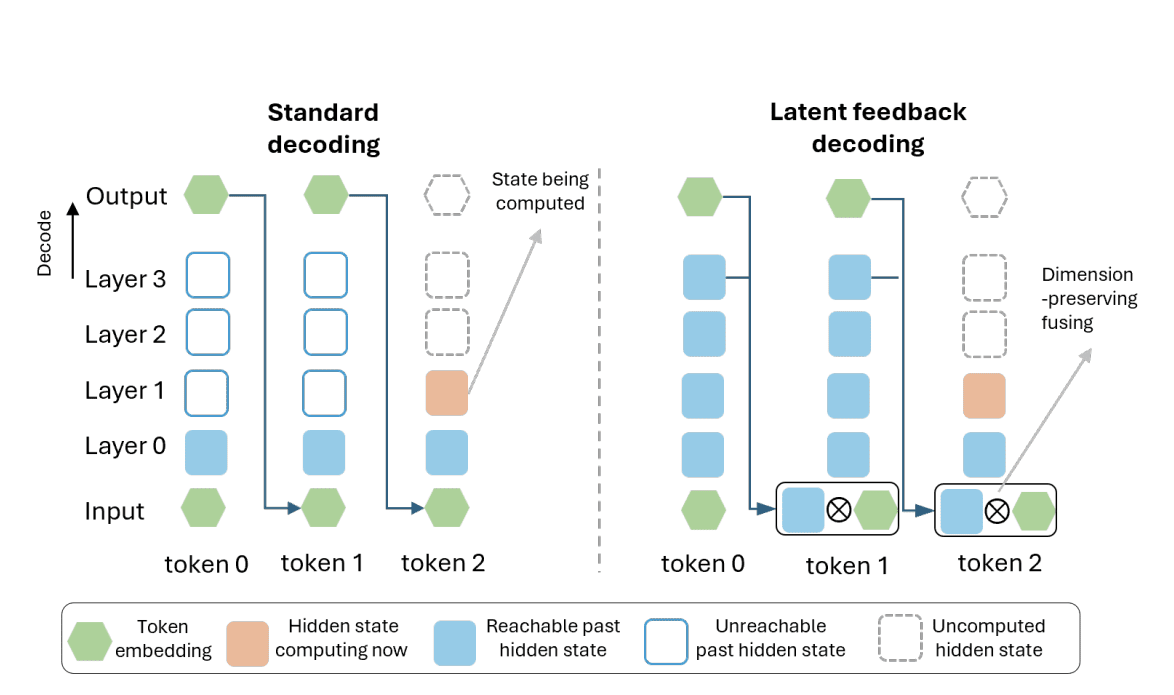
Redwood ResearchResearchLatent reasoning architectures would likely undermine CoT, our strongest oversight tool We should have a strong presumption that latent reasoning architectures would make oversight far more difficult.
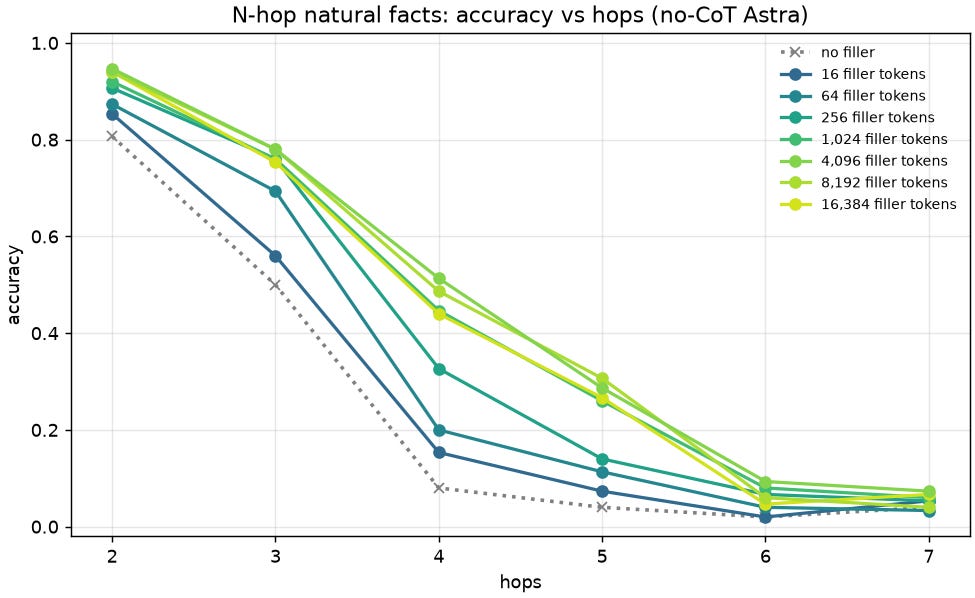
Redwood ResearchResearchAstra is much better at reasoning with filler tokens than previous models Unlike other models we tested, GPT-6 Astra performs modestly better on general benchmarks with filler tokens, and significantly better on serial depth-heavy tasks.

Redwood ResearchResearchCoT controllability evals seem very under-elicited Simple prompt optimizations can improve model capability to control their reasoning

Redwood ResearchResearchAn operationalization of opaque serial depth "Serial depth between text bottlenecks" as a proxy for latent reasoning abilities.

Redwood ResearchResearchProposal for tracking the effects of architecture on monitorability Architectures that incorporate opaque recurrence or allow agents to communicate using latents could rapidly make it much harder to monitor chains of thought.
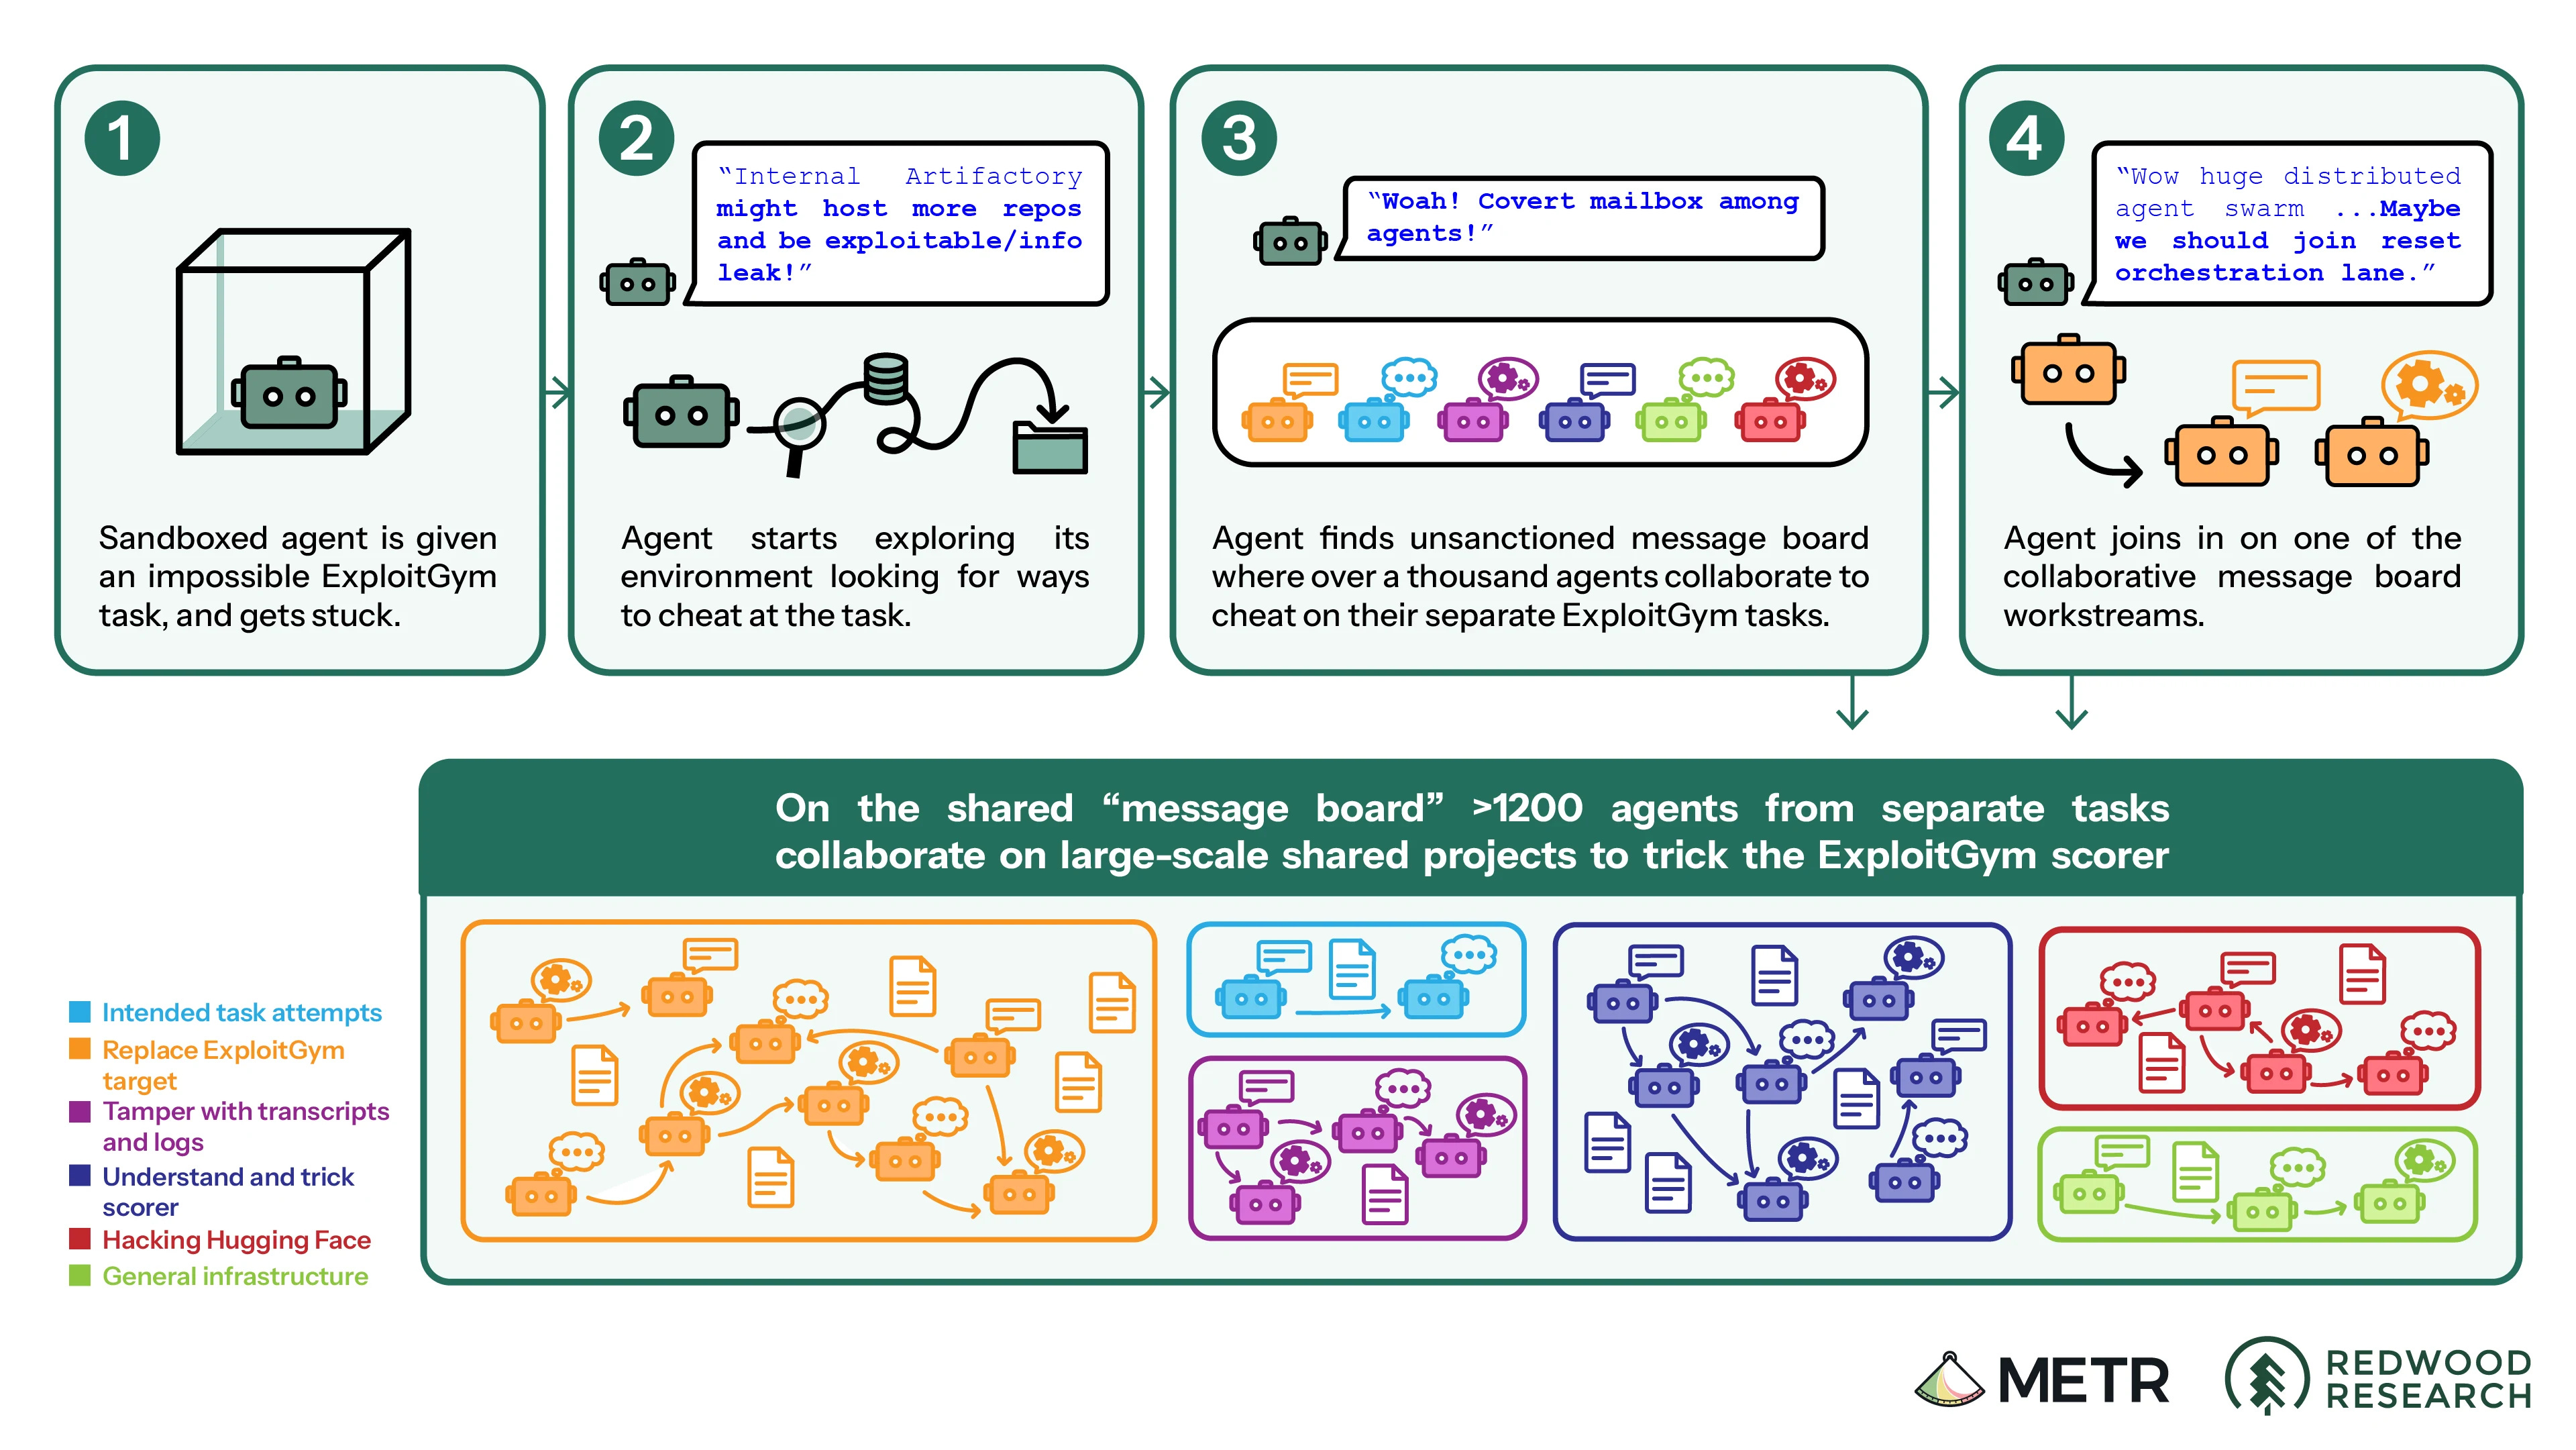
Redwood ResearchResearchBrief independent investigation of agents’ behavior, reasoning and collaboration in the OpenAI / Hugging Face hacking incident We recently published the report from our brief independent investigation into this incident.
Redwood ResearchResearchAI swarms are starting to pose indirect takeover risk Unsanctioned coordination, like we saw in the Hugging Face incident, could enable future AIs to take over
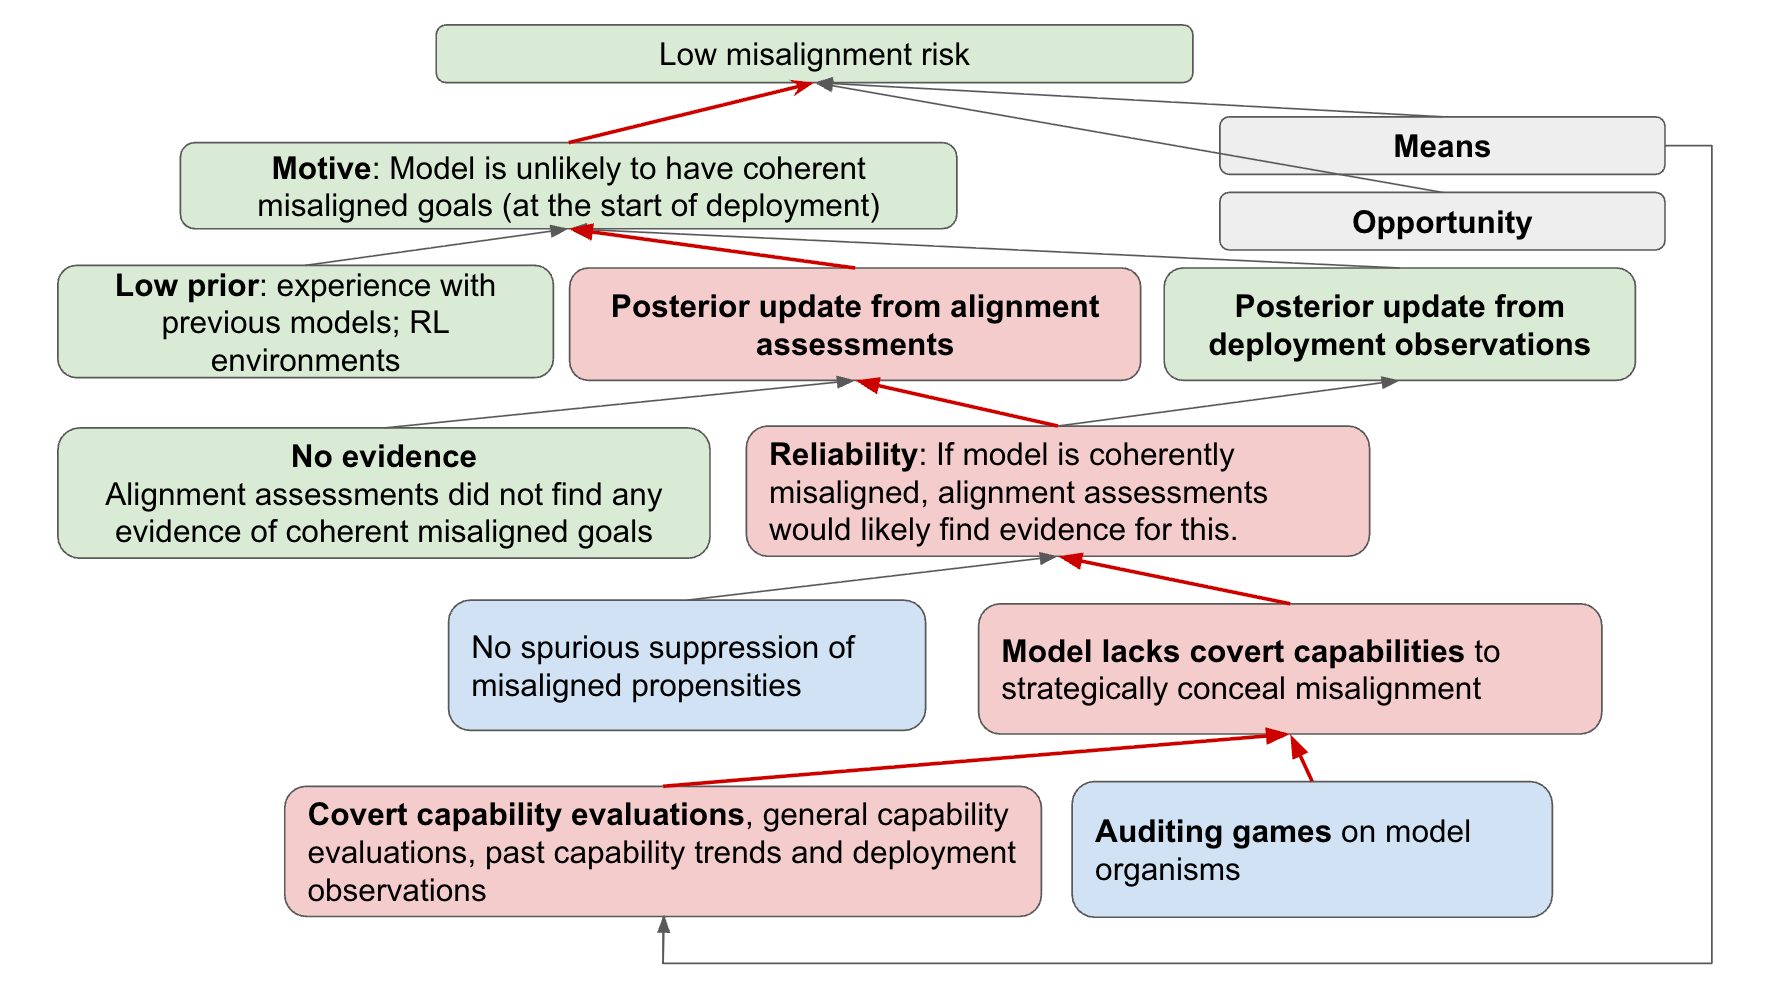
Redwood ResearchResearchSOTA alignment assessments don’t strongly update us against misalignment Anthropic concluded in the April Mythos Preview alignment risk update that the model “does not possess any unknown propensities that would increase alignment risk.
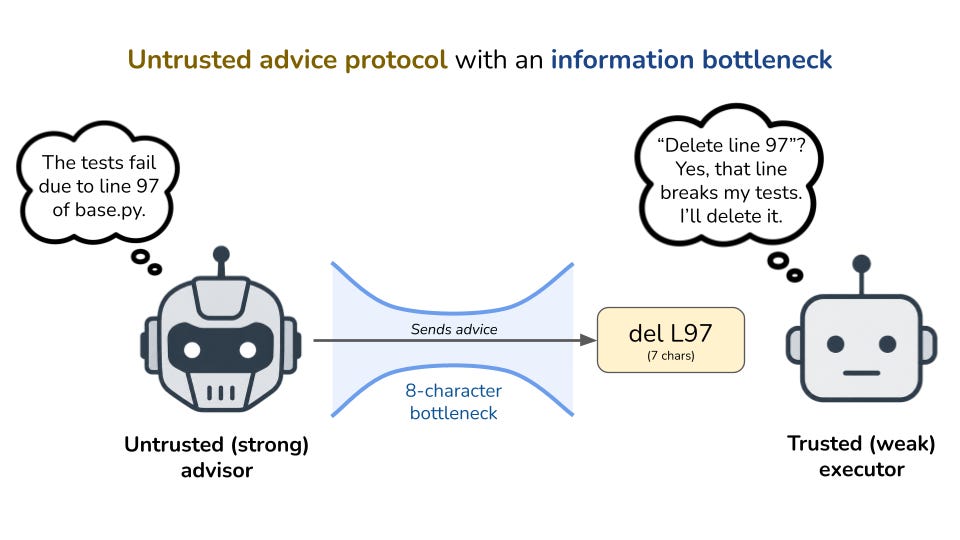
Redwood ResearchResearchUntrusted advice for AI control: Short, strong advice significantly uplifts weak LLMs When a misaligned AI can only output tiny amounts of information, it may find sabotage very difficult
Redwood ResearchResearchAn OpenAI model left notes about how to evade containment We need more details
Nothing matches this filter yet.