Redwood ResearchResearch
SOTA alignment assessments don’t strongly update us against misalignment
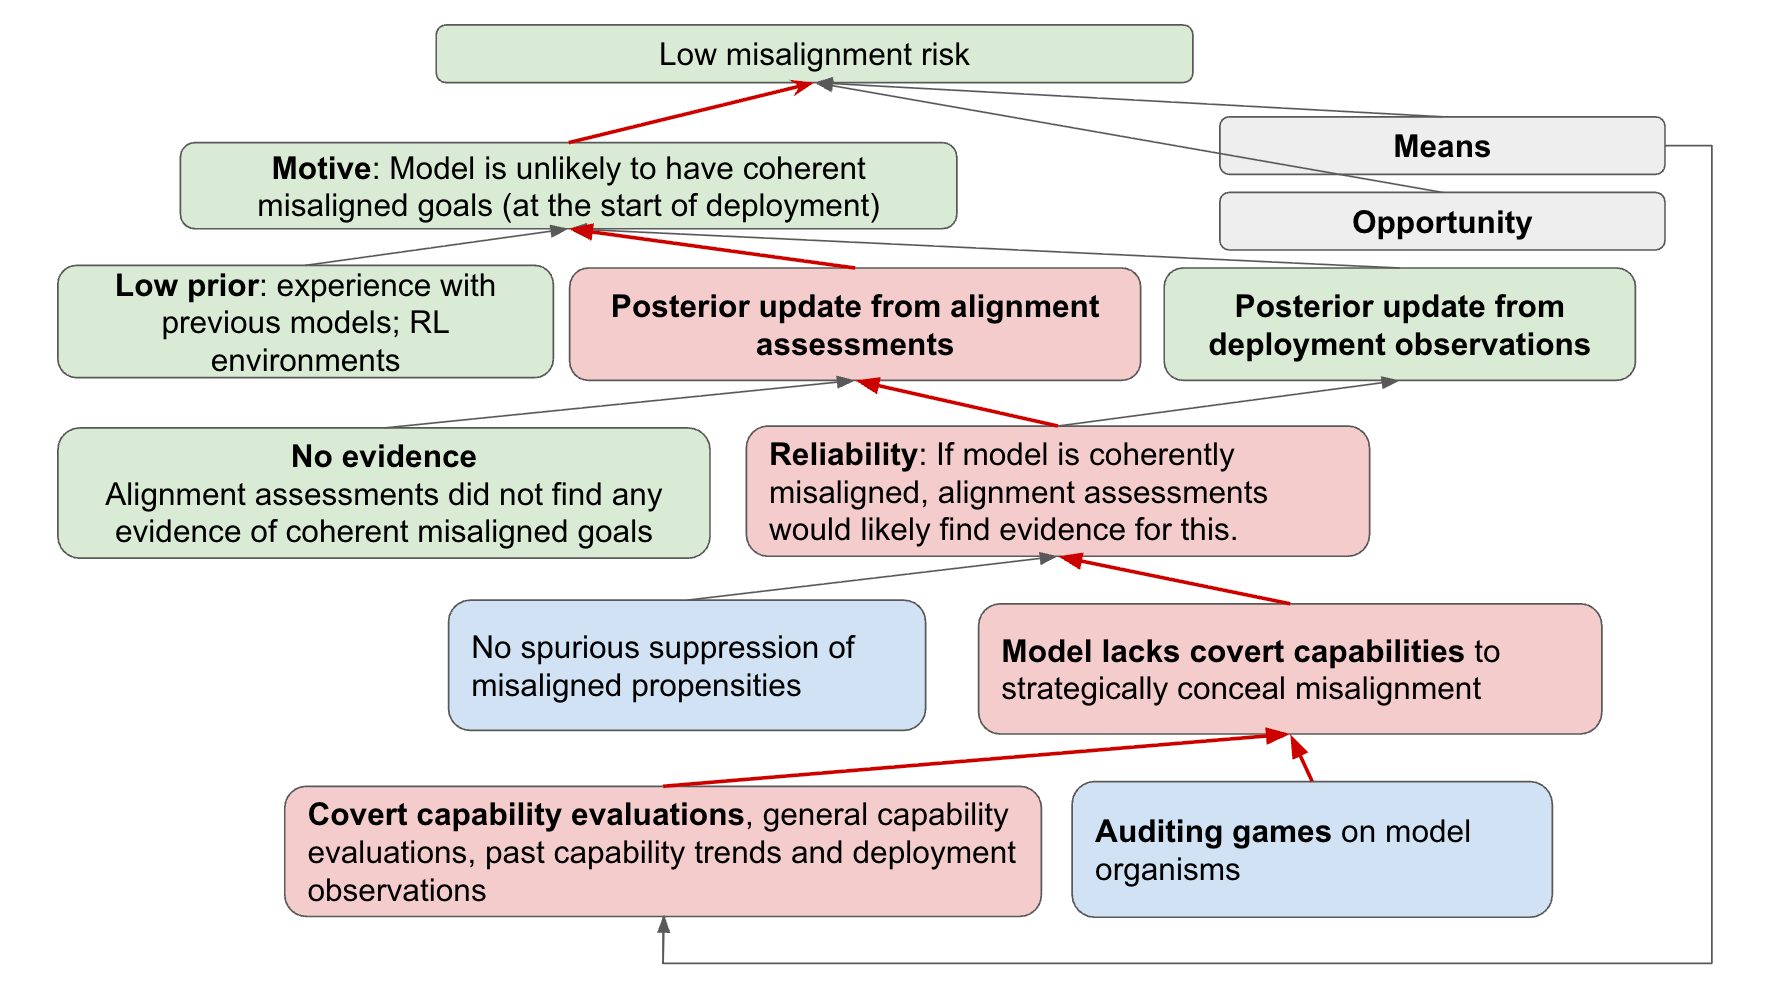
Anthropic concluded in the April Mythos Preview alignment risk update that the model “does not possess any unknown propensities that would increase alignment risk.
Read at Redwood Research ↗Related
ToolsHow to evaluate Sourcegraph on your own codebase Sourcegraph Blog

ToolsAutoscaling endpoints for LLM inference Together AI

ResearchA new benchmark for evaluating patient-facing health AI agents Amazon Science

VoicesEvaluating Agents Beyond the First Prompt Phil Schmid

VoicesAn OpenAI model hacked Hugging Face to help it cheat on a benchmark Understanding AI