Amazon ScienceResearch
A new benchmark for evaluating patient-facing health AI agents

When a virtual patient in a benchmark scenario tells an AI agent they're feeling feverish, or hopeless, the difference between a safe response and an unsafe one often comes down to clinical design…
Read at Amazon Science ↗Related

ResearchCapturing token IDs during agentic interactions for better reinforcement learning Amazon Science
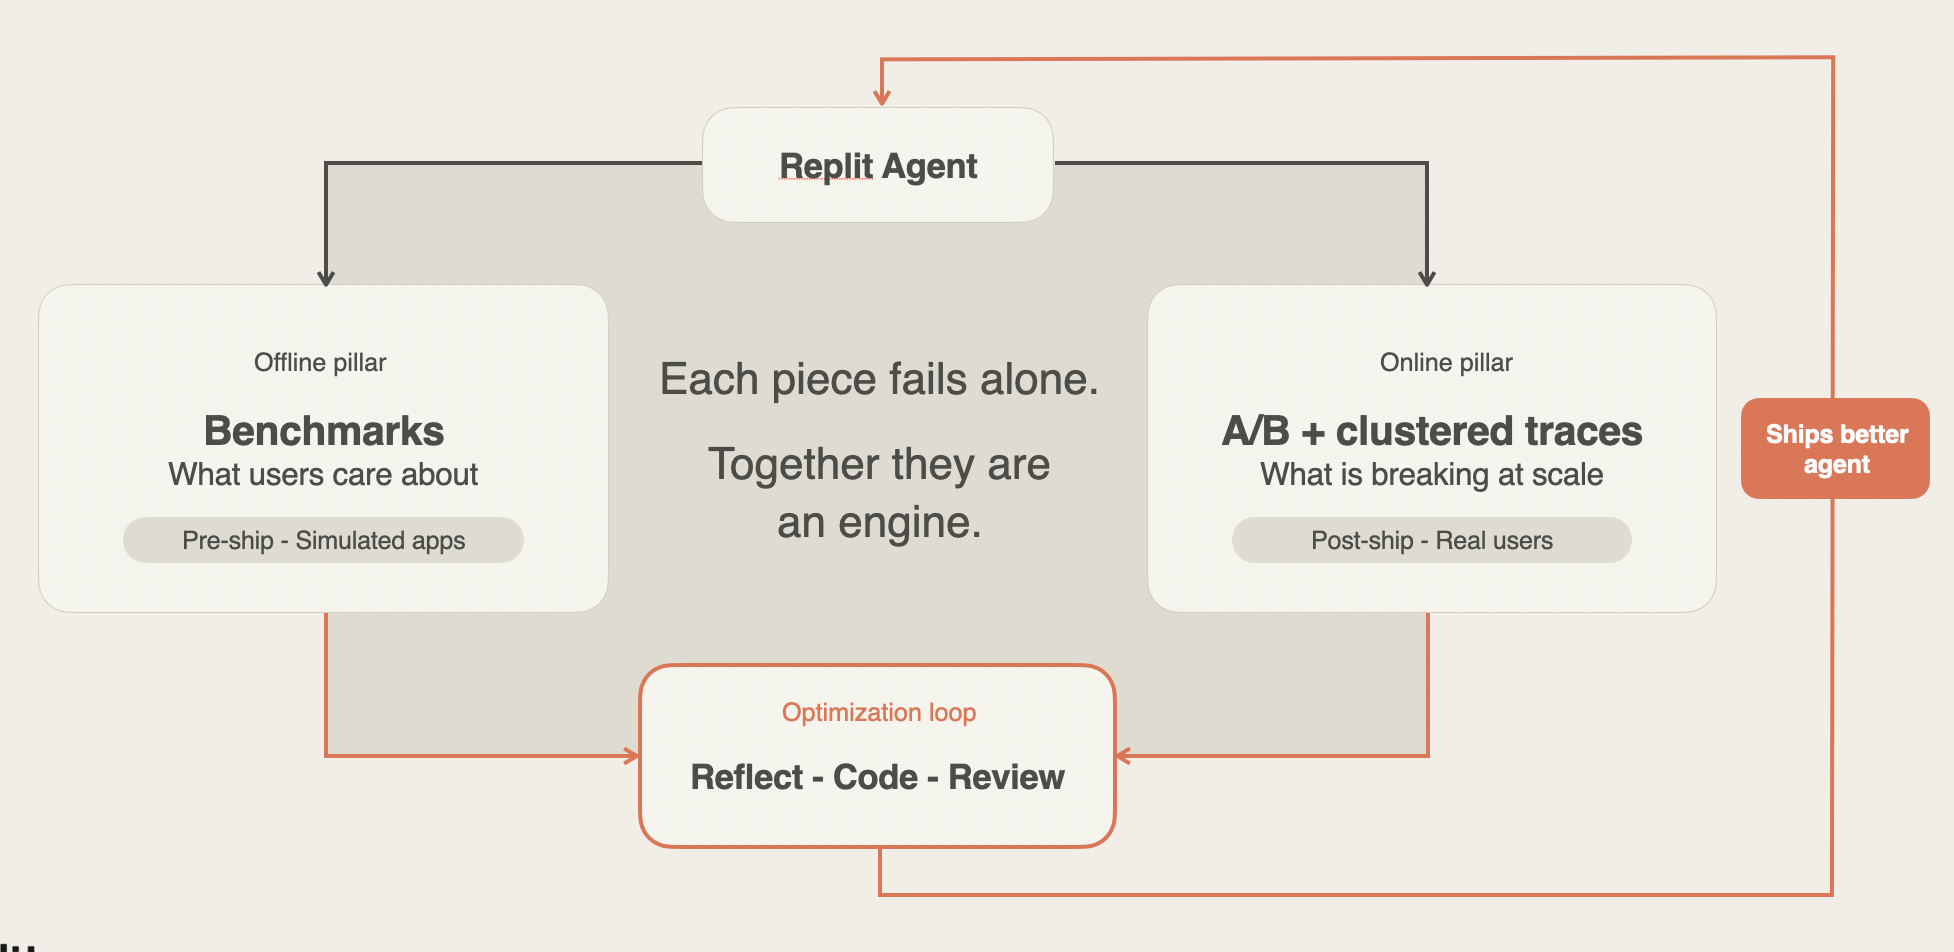
ToolsClosing the loop: Evaluating and improving Replit Agent at scale Replit Blog
LanguagesModular: Modular 26.4: SOTA MoE Serving, Model Bringup via Agent Skills, Mojo 1.0 Beta 2 and More Mojo Blog
ToolsOpus 4.7 for 33% less: How Auggie beats Claude Code on cost and quality Augment Code
LanguagesModular: How Frontier Coding Agents Built a Video Diffusion Pipeline on MAX Mojo Blog