vLLM BlogTools
Encoder Disaggregation in vLLM: Scaling Multimodal Serving with EPD
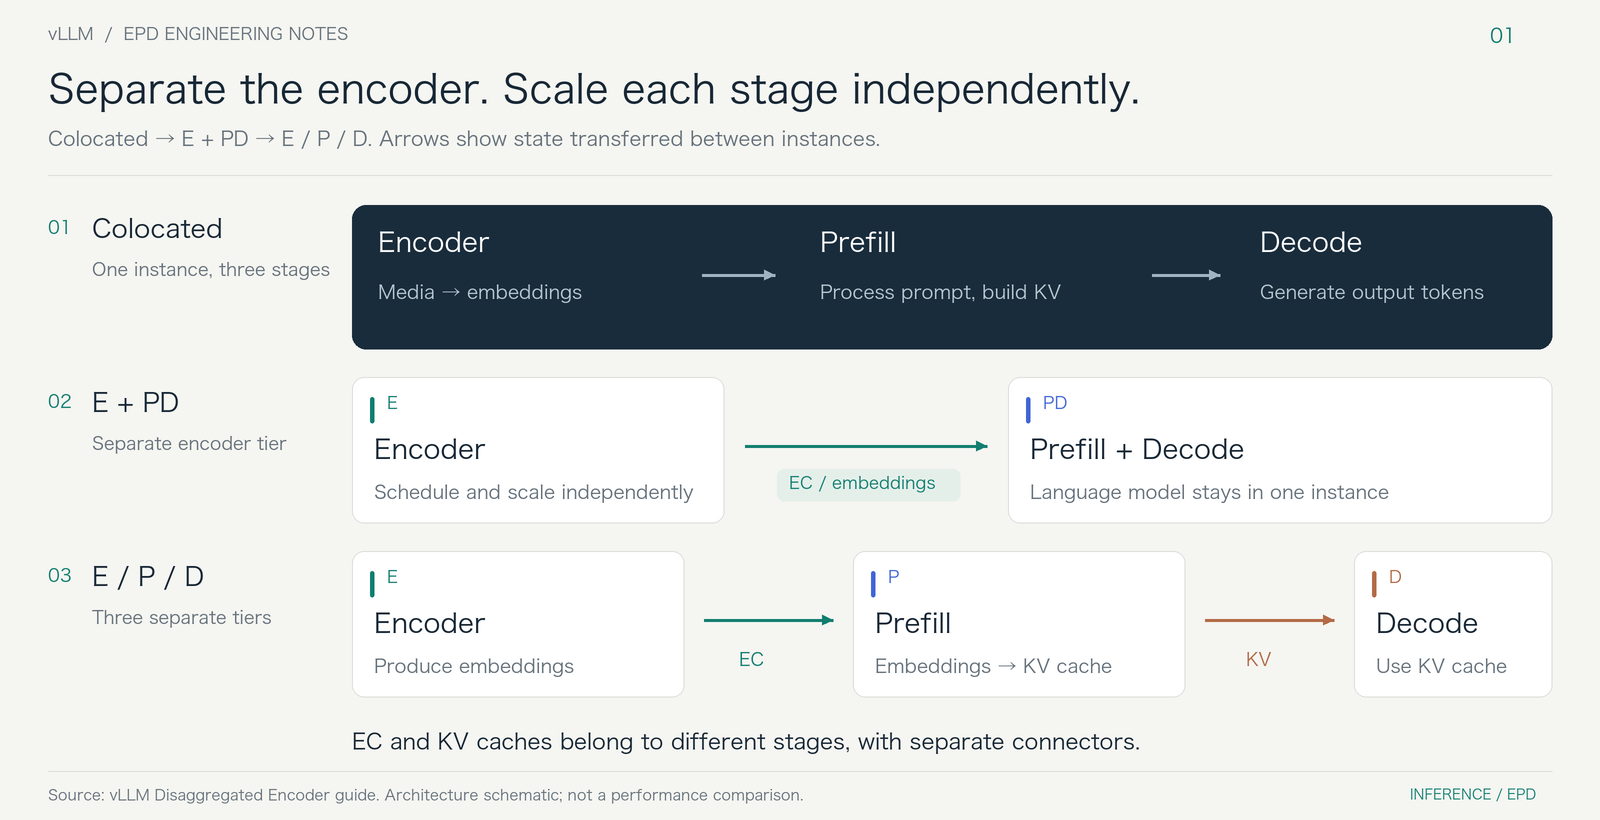
Recent advances in vLLM encoder disaggregation: metadata-only multimodal requests, dedicated encoder execution, remote embedding transfer, cross-encoder caching, and lower-overhead EPD routing.
Read at vLLM Blog ↗Related
ToolsBenchmarking Local LLM Servers: llama.cpp, llamafile, LM Studio, and Ollama Mozilla.ai
ToolsDay 0 support for Mistral Large 4 on vLLM vLLM Blog
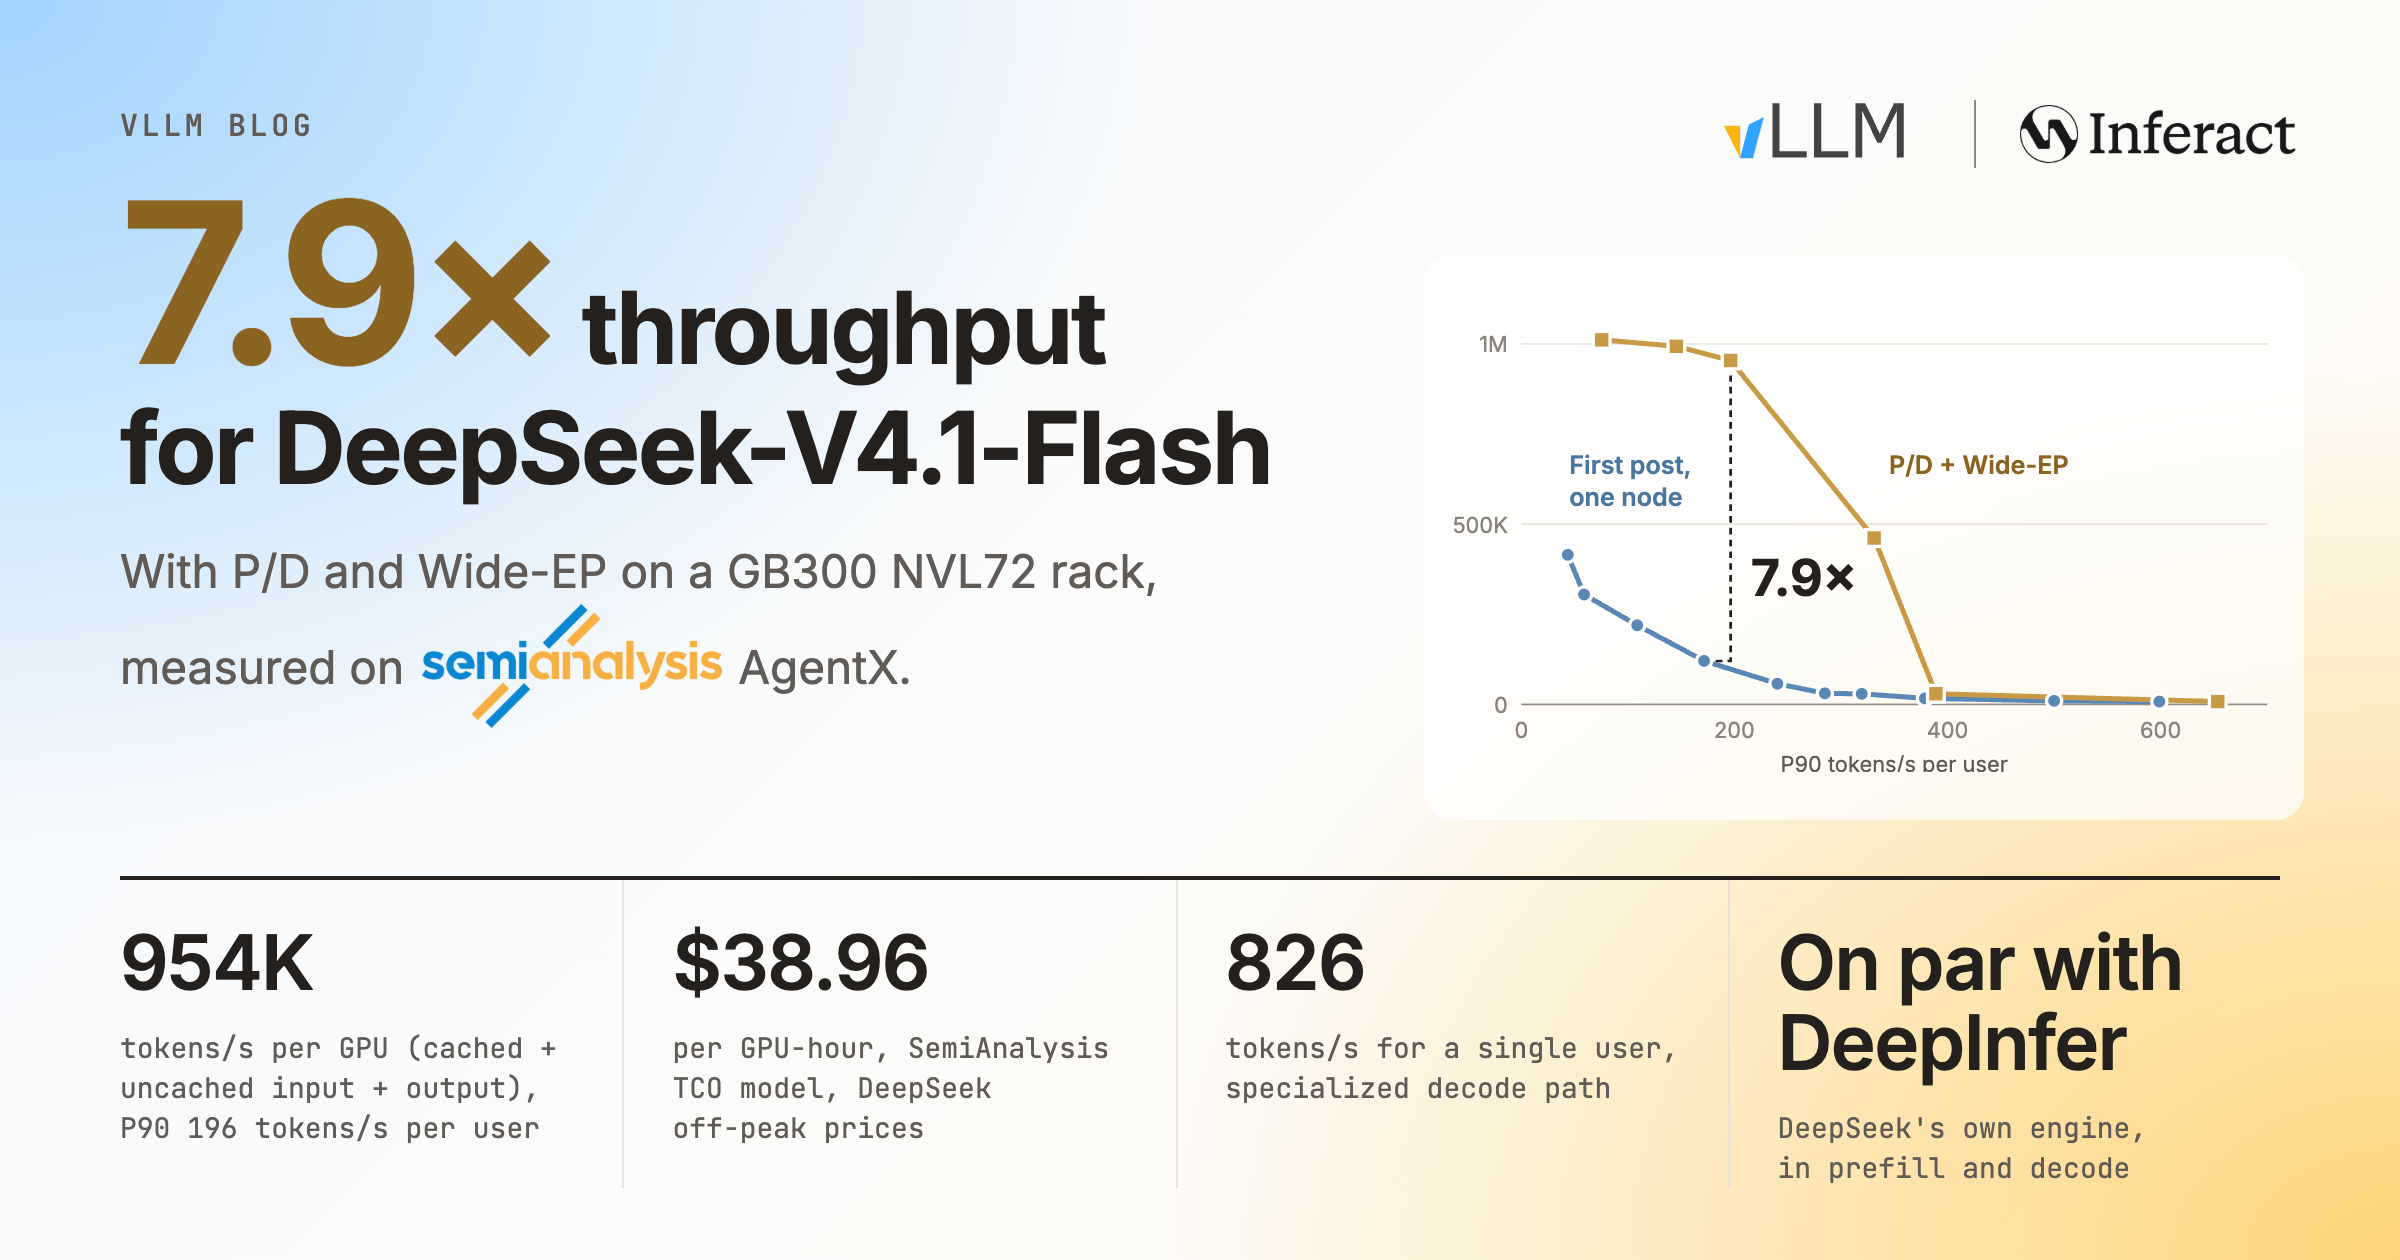
ToolsServing DeepSeek-V4.1-Flash at Scale: vLLM Matches DeepInfer and Scales to GB300 NVL72 vLLM Blog
ToolsDay-0 Support for Flint on vLLM vLLM Blog
ToolsServing Reflection Beam on vLLM from Day 0 vLLM Blog