vLLM BlogTools
vLLM Delivers Day-0 Support for Kimi K3.1 Pro
vLLM supports Kimi K3.1 Pro on day 0: sparse attention on a KDA hybrid, a packed KV cache with FP8 or NVFP4 latents and MXFP4 index keys, token-sharded prefill, decode context parallelism, and fused…
Read at vLLM Blog ↗Related
ToolsDay 0 support for Mistral Large 4 on vLLM vLLM Blog
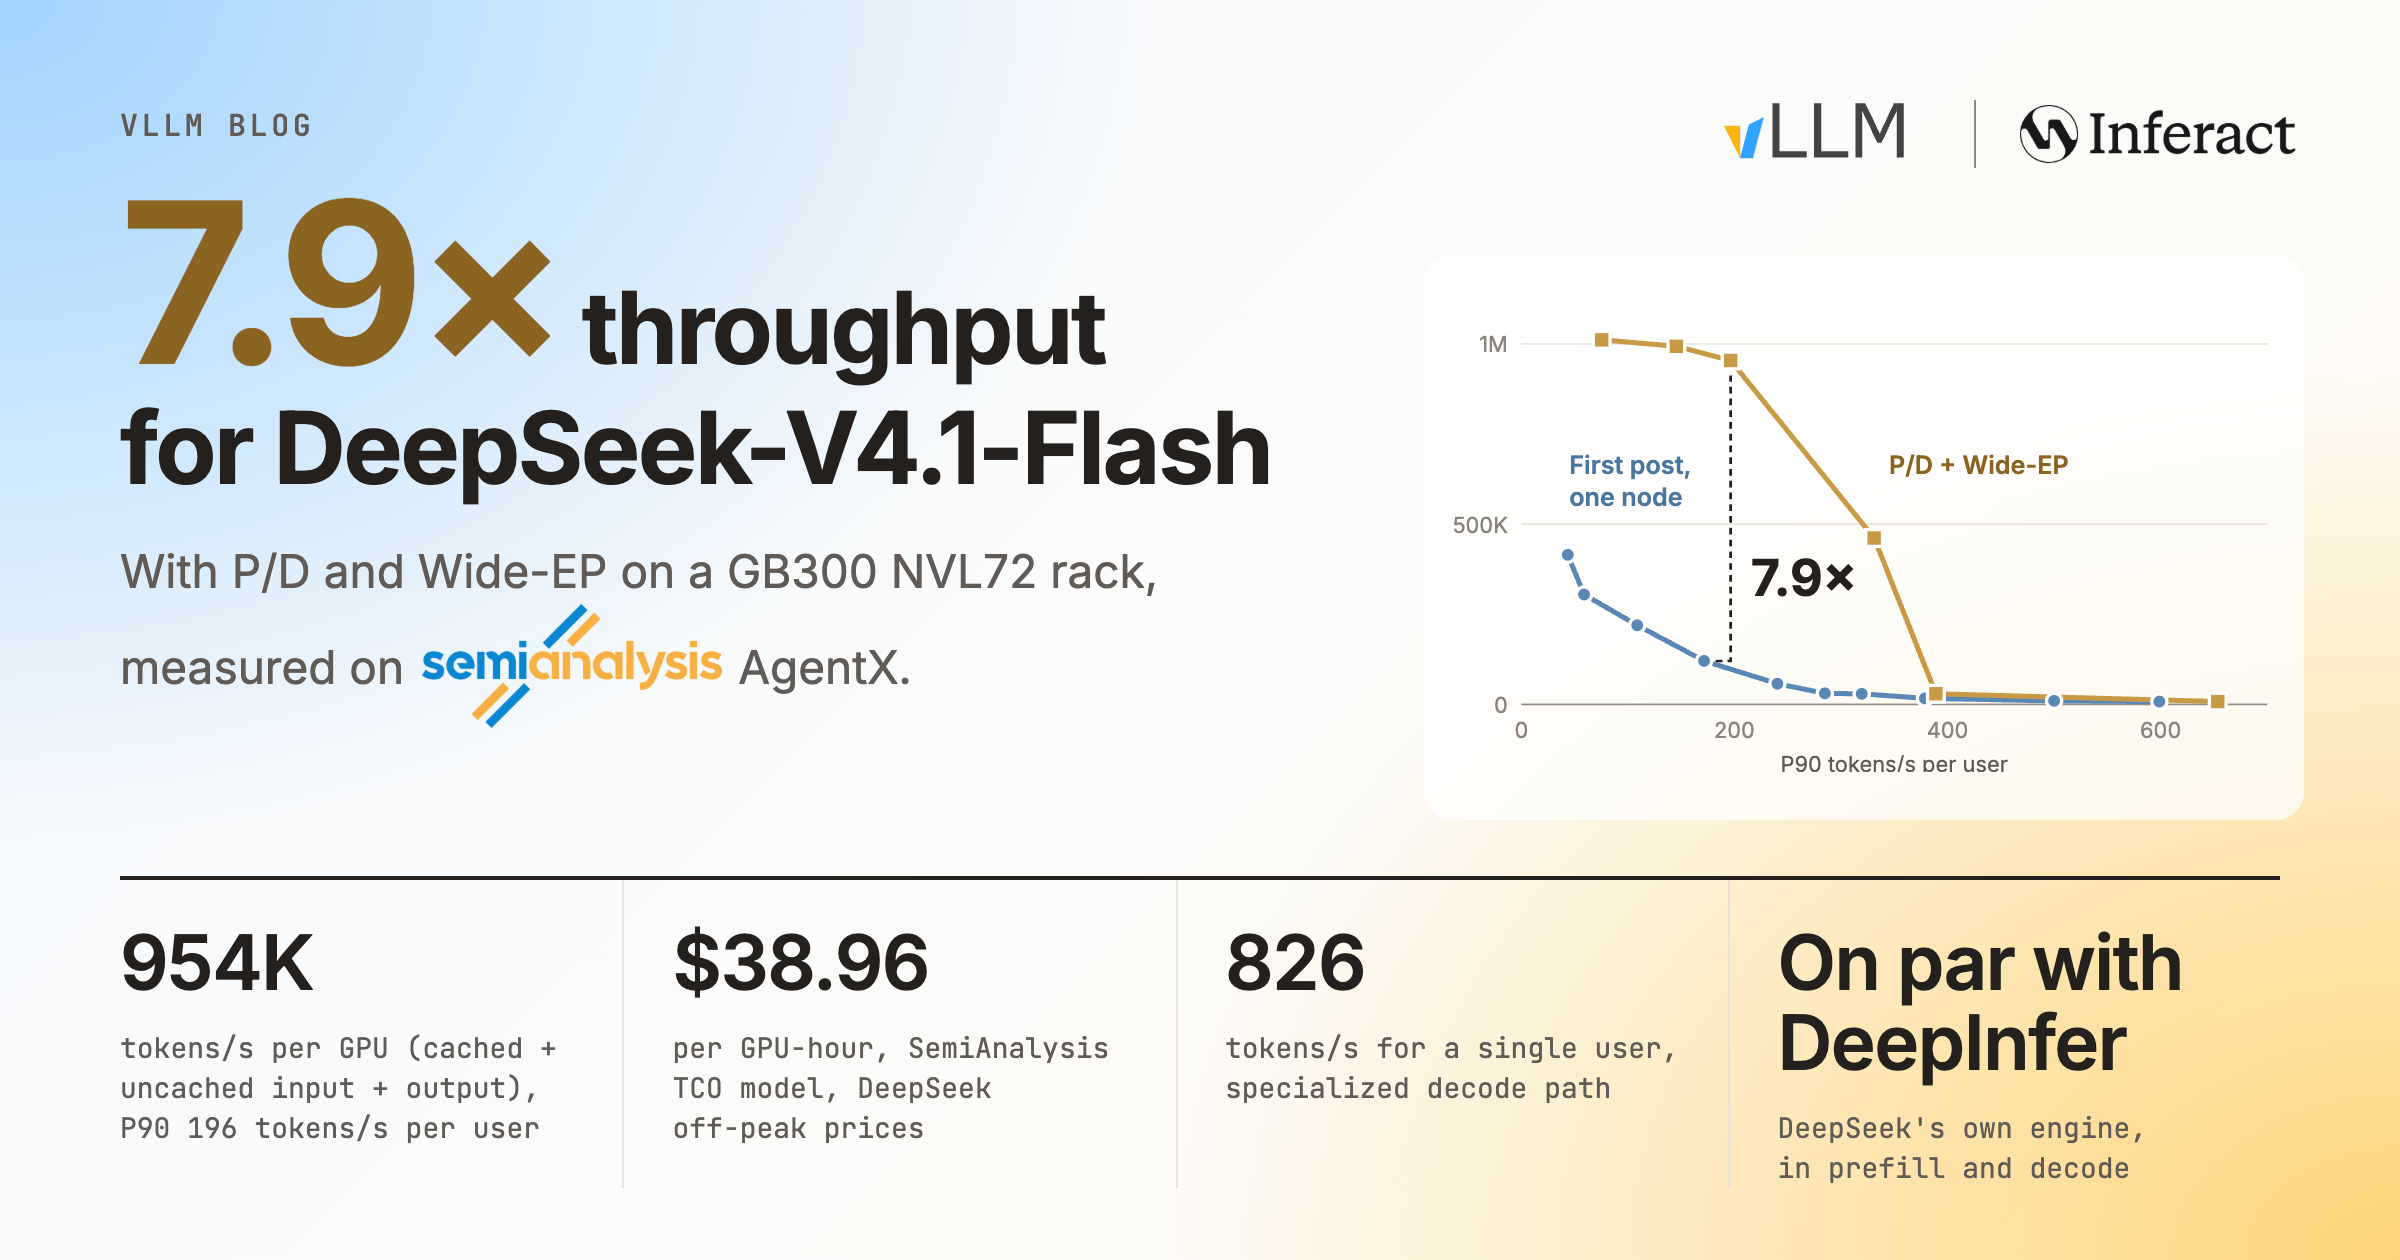
ToolsServing DeepSeek-V4.1-Flash at Scale: vLLM Matches DeepInfer and Scales to GB300 NVL72 vLLM Blog
ToolsvLLM Delivers Day-0 Support for MiniMax-M3.1-Flash vLLM Blog
ToolsDay-0 Support for Flint on vLLM vLLM Blog