PyTorch BlogTools
Optimizing Jagged Flash Attention with TLX: The Road Toward SOTA FA4 on Blackwell
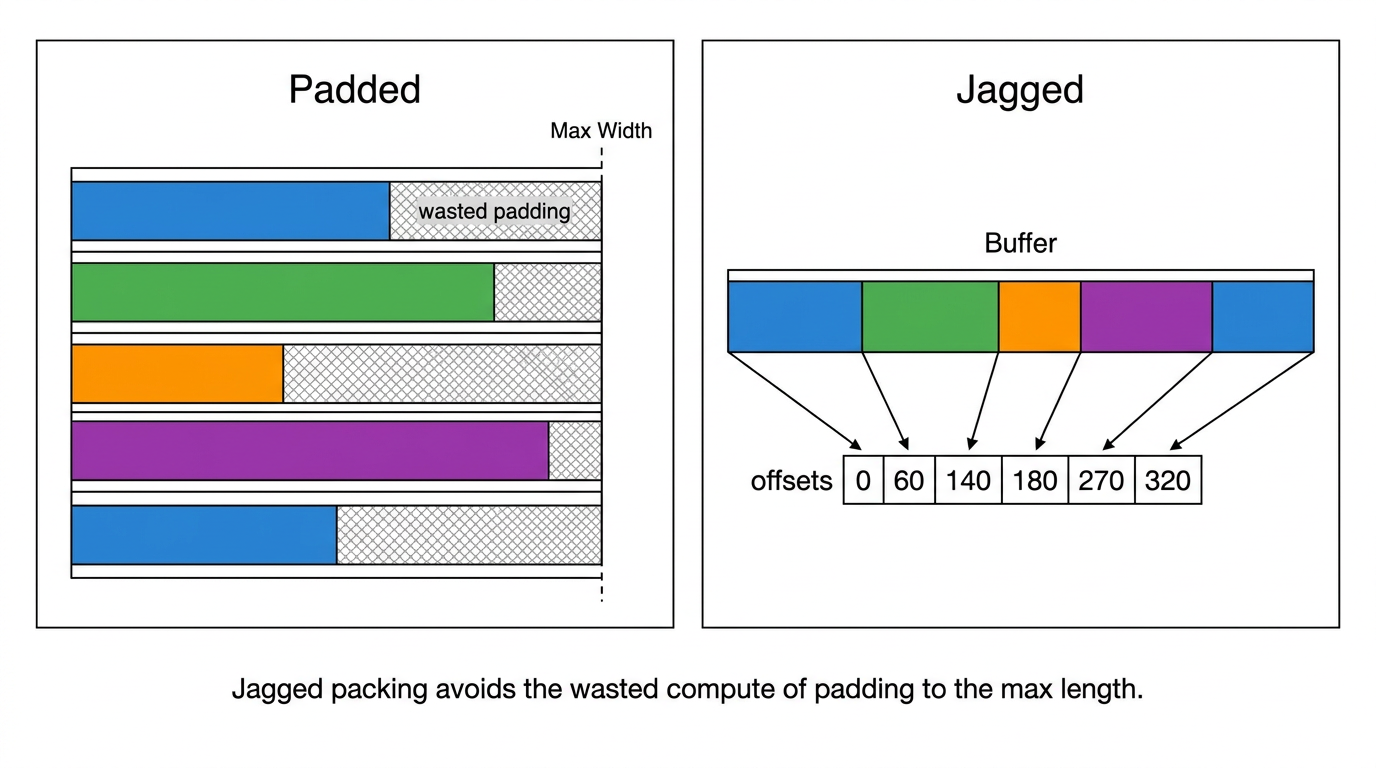
TL;DR In this blog post, we present our work on Jagged Flash Attention (JFA) — the attention kernel behind Meta’s Generative Ads Model (GEM) — on NVIDIA Blackwell (B200), built with TLX (Triton…
Read at PyTorch Blog ↗Related
SiliconQualcomm’s System Level Architecture in the Snapdragon X2 Elite Chips and Cheese

SiliconEfficient MoE Training for Biological Foundation Models NVIDIA Technical Blog
VoicesMoving Beyond RAG with Precomputed Context Software Engineering Daily
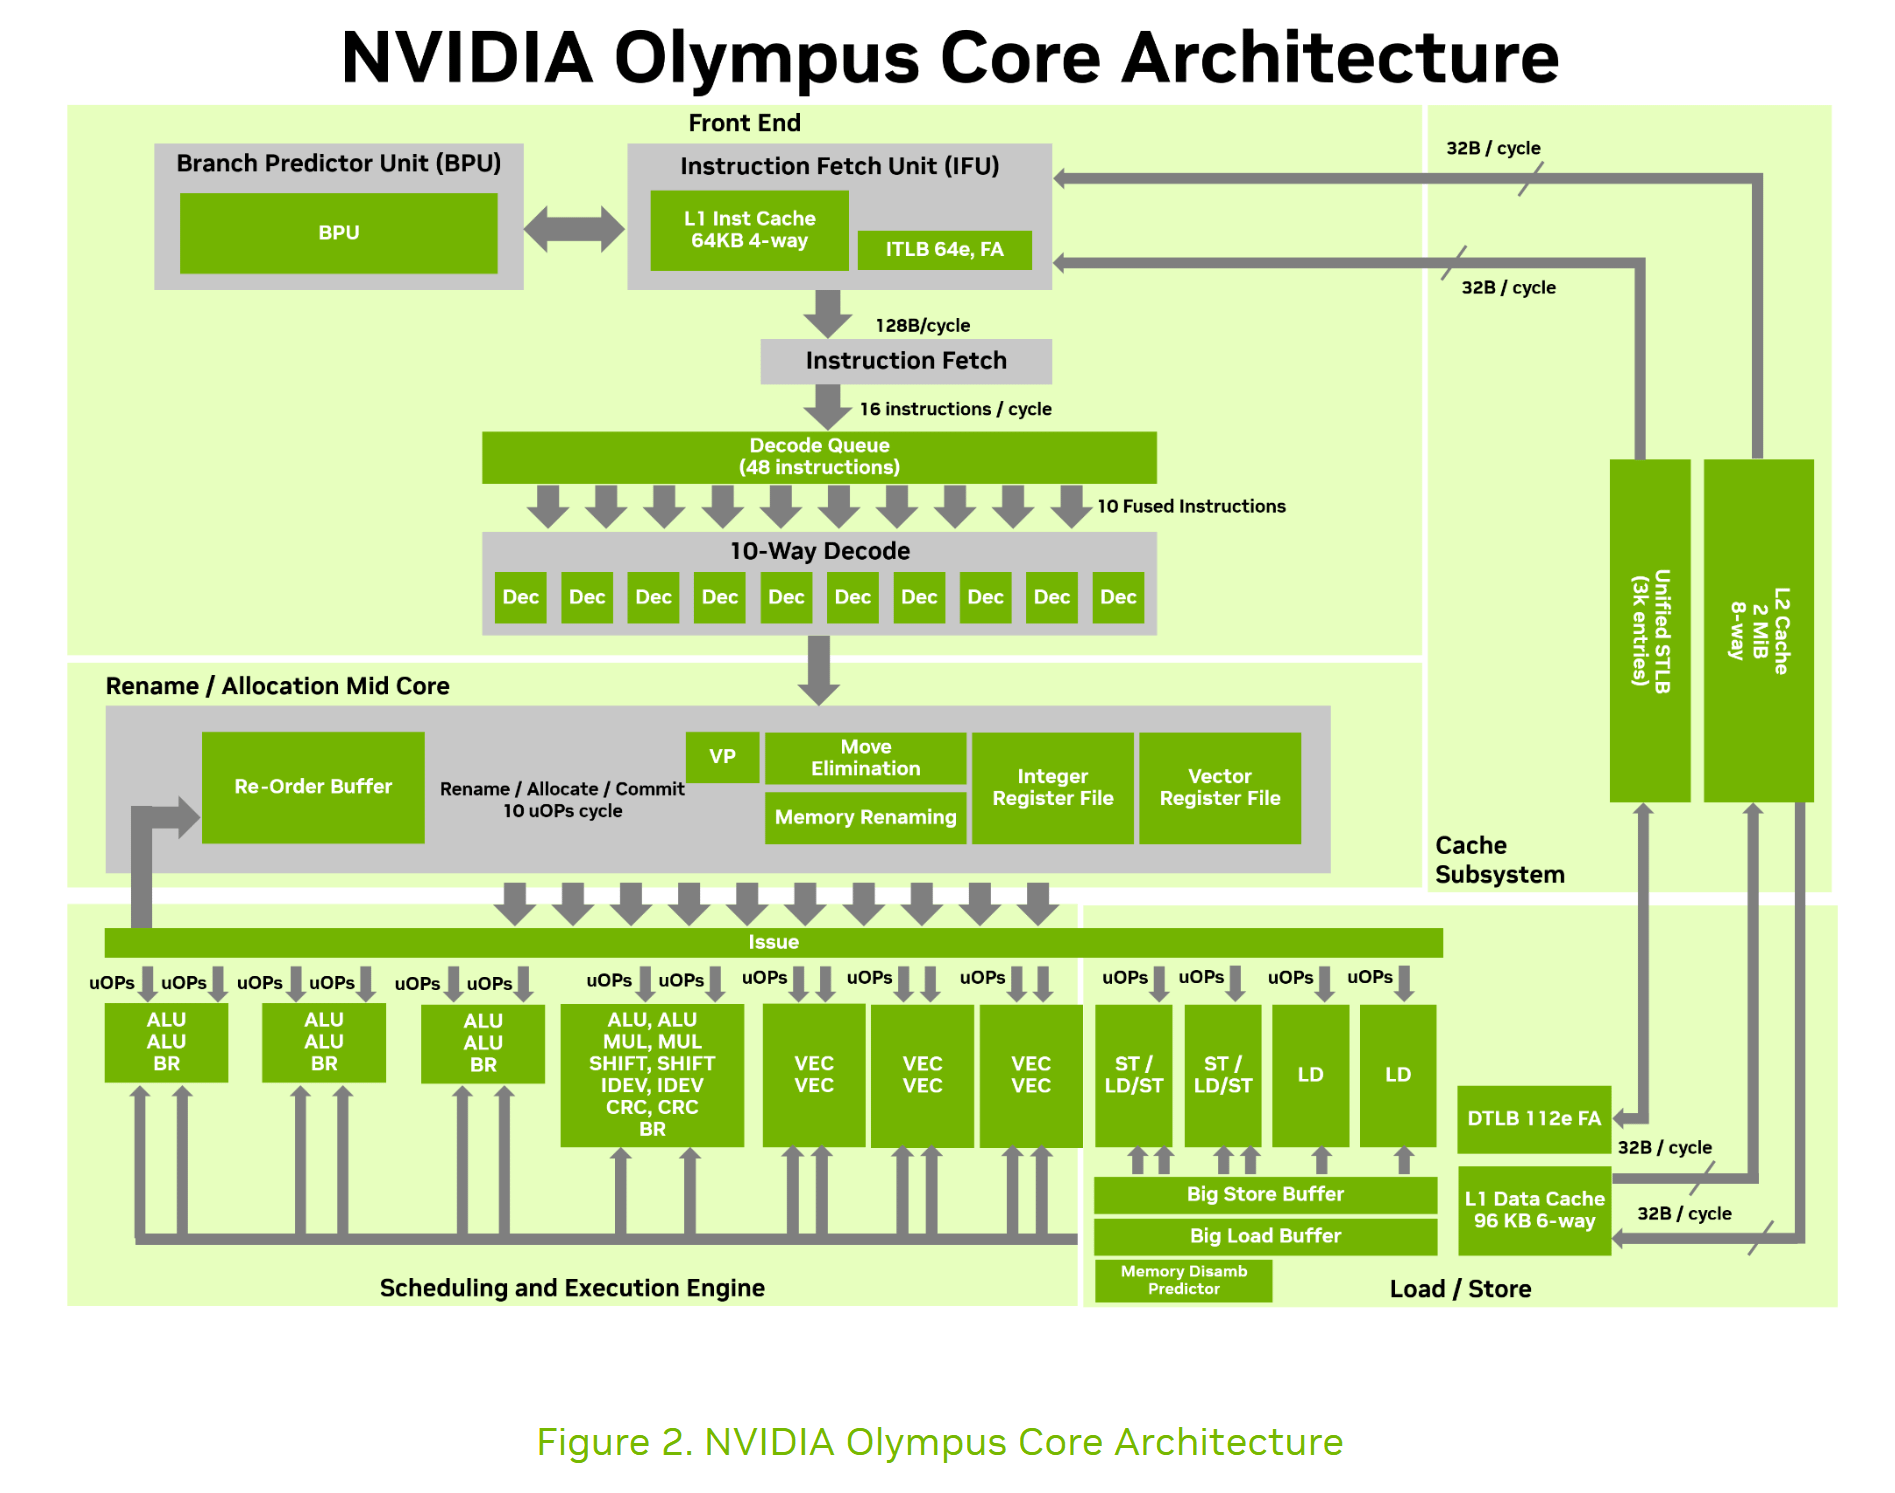
SiliconNVIDIA’s Vera Whitepaper Has a Thread Loose Chips and Cheese
Voices#490 – State of AI in 2026: LLMs, Coding, Scaling Laws, China, Agents, GPUs, AGI Lex Fridman Podcast
